Enhancements in Cold Start Performance with GPU Memory Snapshots
- Gate
- Machine Learning
- Departs
- Crew
- Luis Capelo
- Passengers
- 564
Modal's introduction of GPU memory snapshots accelerates cold start times for GPU workloads, achieving startup speeds up to 10x faster than traditional methods.
Introduction to GPU Memory Snapshots
At Modal, addressing cold start latency has been a focal point. Earlier this year, we unveiled memory snapshots that reduced startup times significantly. Now, with GPU memory snapshots, we enhance this concept to optimize GPU-accelerated tasks, carrying the same checkpoint/restore principles to GPU workflows.
Improving Cold Boot Times
Modal has systematically tackled the issue of cold boot latency from three central angles:
- Custom file system optimized for cold boots
- CPU memory snapshots
- GPU memory snapshots
Our unique distributed file system harnesses multiple caches to store frequently accessed files directly in the worker memory. This boosts performance significantly, achieving speeds that are typically 3-5 times faster than downloading files without a caching mechanism.
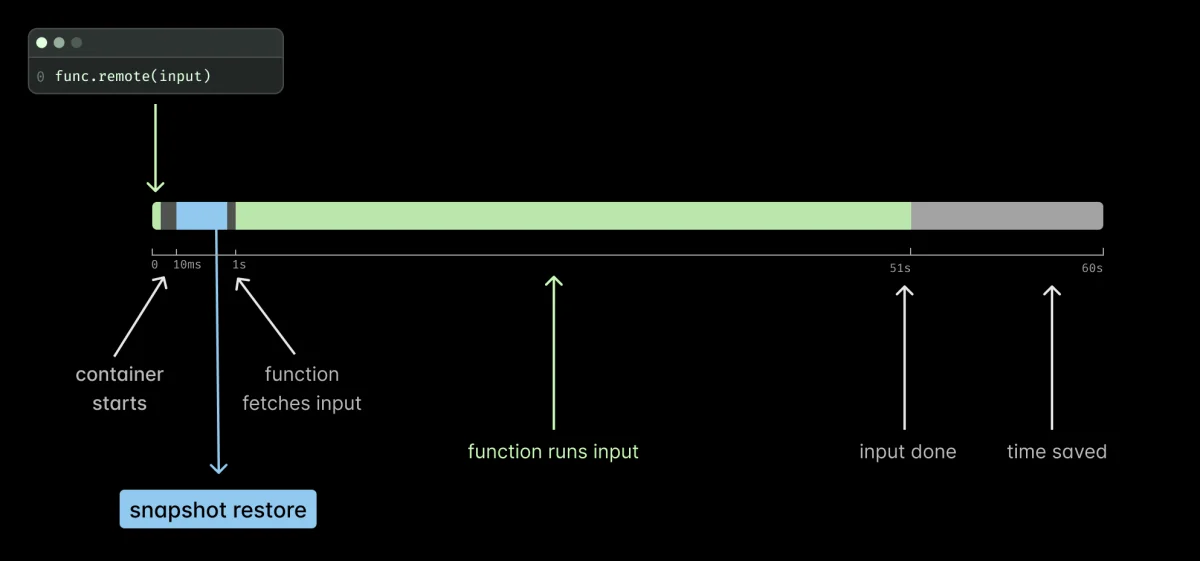
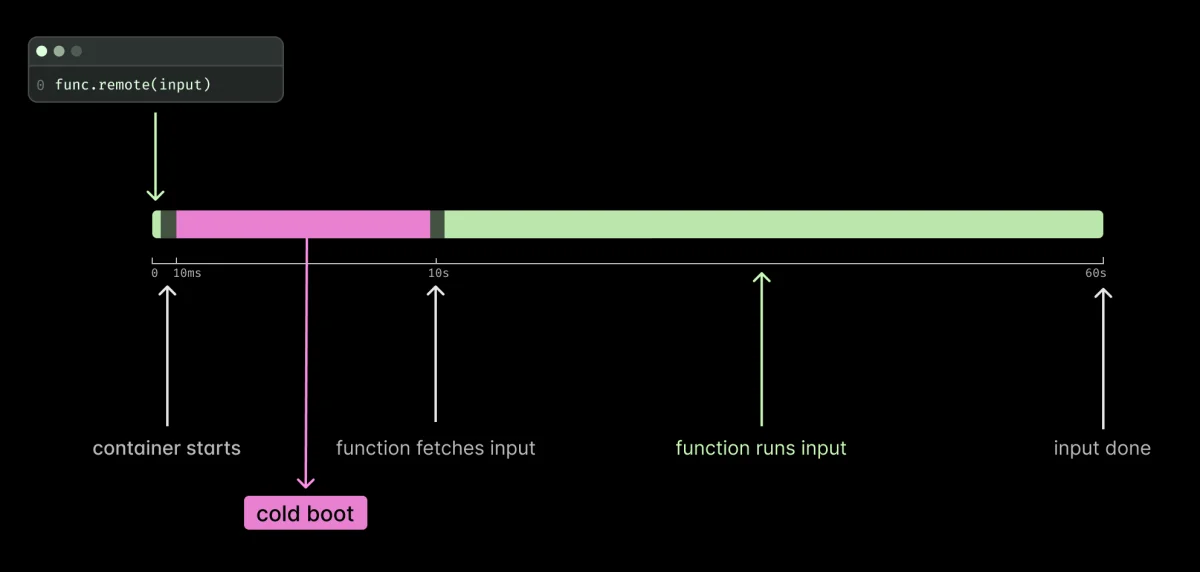
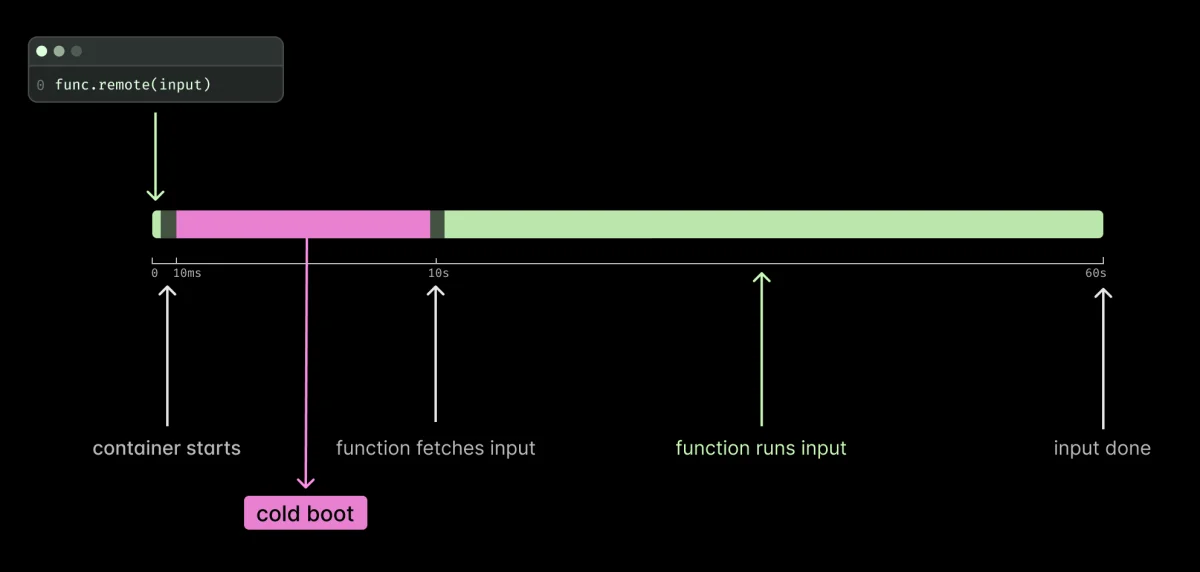
The Modal Function lifecycle entails various stages including container cold boot and input processing. A cold boot primarily involves downloading program files and loading them into memory. These operations can be time-consuming, prompting the desire to save the memory representation of a program into an image. By doing so, we can streamline cold boots, skipping the file reading and recreation of program states.
In January 2025, we introduced memory snapshots, facilitating faster cold boot times by freezing and caching your function's state just before it processes inputs. From then on, cold boot operations begin from this optimized state.
The Challenges of GPU Memory Management
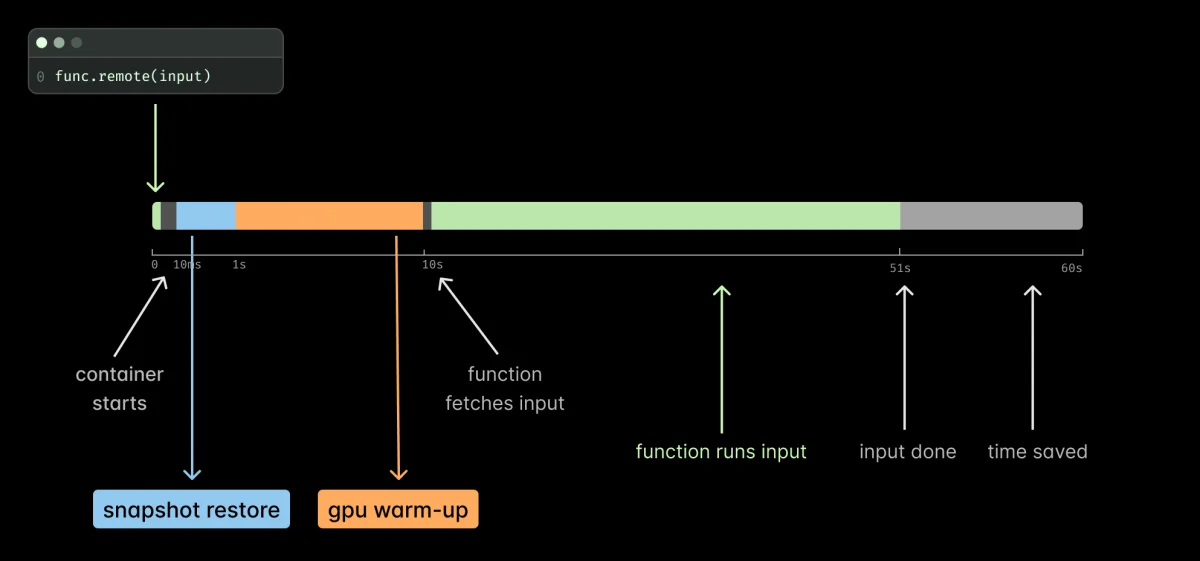
While our memory snapshots significantly enhanced cold boot times for many functions, a notable limitation existed for GPU workloads—the GPU state could not be included in the snapshot. Traditionally, managing NVIDIA GPU states post-restore required additional steps, such as copying model weights from CPU to GPU, which extended the startup process.
For example, the previous method required a two-step approach: files would load into CPU memory, followed by a manual transition to GPU memory. This approach proved effective, resulting in startups up to three times faster, but it wasn’t the most efficient method. Developers were obliged to manage multi-stage processing and could break snapshots by inadvertently invoking CUDA sessions or checking GPU availability with commands like torch.cuda.is_available().
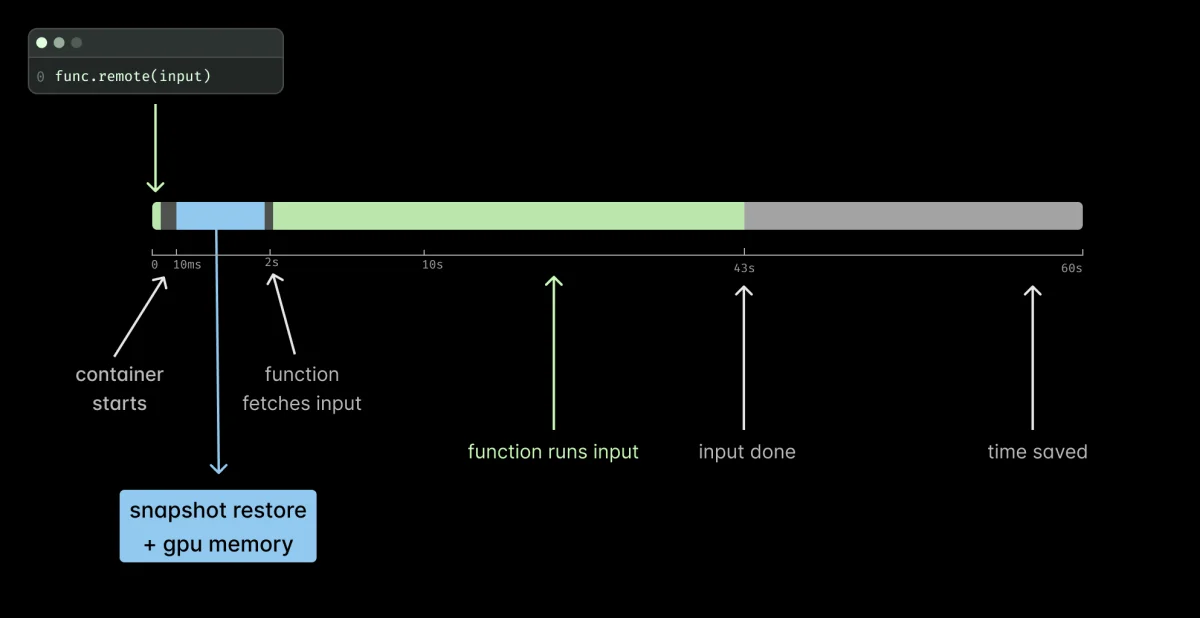
This cumbersome process was particularly inefficient for programs utilizing torch.compile to optimize GPU performance, which necessitated recompiling models regardless of prior configurations.
Introducing CUDA Checkpoint APIs
The release of the CUDA checkpoint/restore API, now available in the 570 and 575 driver branches, allows for a seamless management of GPU memory. This API facilitates the checkpointing and restoration of CUDA state, covering essential aspects like:
- Device memory contents (GPU vRAM) including model weights
- CUDA kernels
- CUDA objects such as streams and contexts
- Memory mappings and addresses
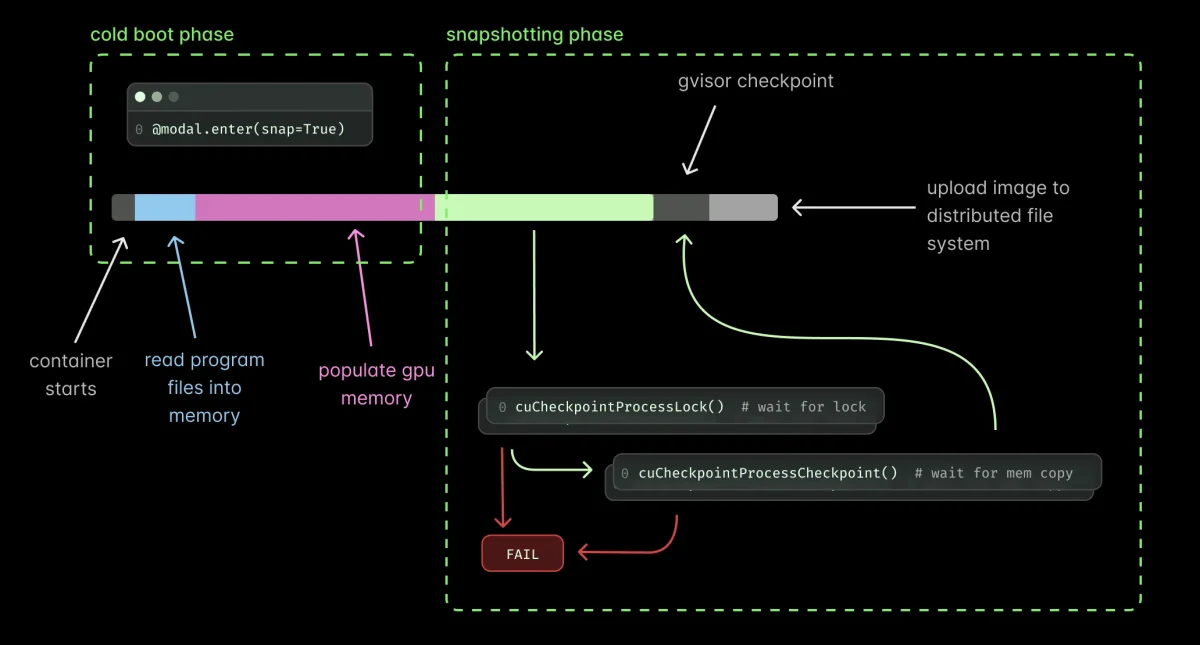
In conjunction with CPU memory snapshots, GPU memory snapshots capture the container's full state before it processes requests. The new method locks CUDA processes, ensuring that ongoing CUDA calls complete before operations can proceed. This involves a sequence of actions:
- Lock CUDA processes: Prevents new CUDA calls from being executed until running calls finish.
- Checkpoint: Transfers GPU memory and CUDA state into host memory before releasing GPU resources and terminating CUDA sessions.
To maintain reliable memory snapshotting, we monitor CUDA session statuses closely. Only after confirming all active sessions have reached the CU_PROCESS_STATE_CHECKPOINTED state does the system commence full memory snapshotting.
This meticulously integrated process maintains compatibility across diverse worker hosts, ensuring that a snapshot created on one machine can be restored on another with compatible GPU hardware.
Performance Gains with GPU Memory Snapshots
Testing of GPU memory snapshots across various workloads has demonstrated impressive results, with startup speeds reaching up to 10 times faster compared to baseline operations. This dramatic improvement is critical for scaling down and optimizing serverless architectures while maintaining an efficient user experience. For instance, an audio transcription model like Parakeet that once required about 20 seconds to cold boot can now do so in as little as 2 seconds.
Similarly, a ViT inference function has been improved from 8.5 seconds to 2.25 seconds, avoiding the need to re-run torch.compile. The transition from a 45-second startup for vLLM running Qwen2.5-0.5B-Instruct to just 5 seconds exemplifies the transformative effect of this technology.
Implementing GPU Memory Snapshots
Incorporating GPU memory snapshots into existing Modal applications requires only minor changes—adding a new flag when configurations are set. Users already utilizing memory snapshots simply include experimental_options={"enable_gpu_snapshot": True} to their application settings.
Furthermore, the revised API eliminates the need for separate snap=True and snap=False statements. Models now load directly to GPU, and the complete GPU state is snapshotted in a single step.
Exploring GPU Memory Snapshots
Currently, GPU memory snapshots are in alpha at Modal. As we delve deeper into the limitations and functionalities of this feature, we encourage developers to experiment and provide feedback on their experiences, contributing to future enhancements of this promising technology.
Acknowledgments
We extend our gratitude to NVIDIA/CUDA for integrating checkpoint/restore functionalities into the CUDA API. Additional thanks go to the contributors of the cuda-checkpoint project for creating a platform to evaluate these new APIs and to the gVisor team at Google for their ongoing support in developing a secure and high-performance runtime environment.


