Modal Launches B200 and H200 GPUs for Enhanced Performance and Accessibility
- Gate
- Machine Learning
- Departs
- Crew
- Richard Johnson
- Passengers
- 639
Modal introduces B200 and H200 GPUs, offering significant performance gains for large models at accessible pricing without complex sales processes.
Modal is expanding its GPU offerings with the introduction of the B200 and H200 models, both designed to deliver considerable performance improvements for various computing tasks. Unlike previous product launches, Modal is providing direct access to these GPUs through a straightforward account setup, eliminating the need for cumbersome sales processes.
The B200s, priced at $6.25 per hour, and H200s, available for $4.54 per hour, can seamlessly be incorporated into existing Modal Functions with minimal setup. For example, developers can implement these GPUs with a simple one-liner in their code:
import modal

app = modal.App()

@app.function(gpu="B200") # or "H200"
def run_big_model():
    # This will run on a Modal B200
Specifications Comparison of B200 and H200 GPUs
When comparing the specs of the new B200 and H200 GPUs with the earlier H100 models, the advancements are clear. The following table highlights the key specifications:
| B200 | H200 | H100 | |
|---|---|---|---|
| Streaming Multiprocessor Architecture | Blackwell | Hopper | Hopper |
| GPU RAM | 180 GB | 141 GB | 80 GB |
| GPU RAM ↔ Streaming Multiprocessor Memory Bandwidth | 8 TB/s | 4.8 TB/s | 3.5 TB/s |
| FP4 Tensor Core Arithmetic Bandwidth | 9 PFLOP/s | n/a | n/a |
| FP8 Tensor Core Arithmetic Bandwidth | 5 PFLOP/s | 2 PFLOP/s | 2 PFLOP/s |
Understanding GPU Specifications
The B200 GPU features an impressive 180GB of HBM3e on-device memory, which is more than twice the storage capacity of the H100. This increased memory allows for more extensive data handling, particularly beneficial for large-scale models like DeepSeek-R1, Qwen 3, and LLaMA 4. Such models often exceed the capabilities of earlier technologies and can now be effectively managed with either eight B200s or H200s.
Additionally, the B200's memory bandwidth of 8 TB/s significantly outpaces the Hopper GPUs' ~4 TB/s rate. This improved bandwidth enables faster data transfer between memory and computing units, which is particularly advantageous for applications such as chatbot inference. Users can expect over a twofold reduction in latency simply by upgrading from H100s to B200s without any modifications to their inference code.
The new Blackwell architecture is another noteworthy aspect, featuring native support for 4-bit floating-point operations. This support allows for approximately a fourfold acceleration compared to the 8-bit floating-point operations standard on Hopper models. This improvement efficiently reduces memory bandwidth contention and increases arithmetic bandwidth simultaneously, making it ideal for demanding compute-bound tasks.
Performance Enhancements with B200 GPUs
Users can anticipate significant performance improvements when migrating from H100s or H200s to B200s. Early testing indicates that many workloads enjoy speed increases ranging from two to four times. However, realizing the full potential of B200s will require time and incremental software optimizations; for instance, the popular vLLM serving engine has recently gained support for Blackwell GPUs, with version 0.9 launched just days ago. Achieving peak performance will depend on further work across various applications.
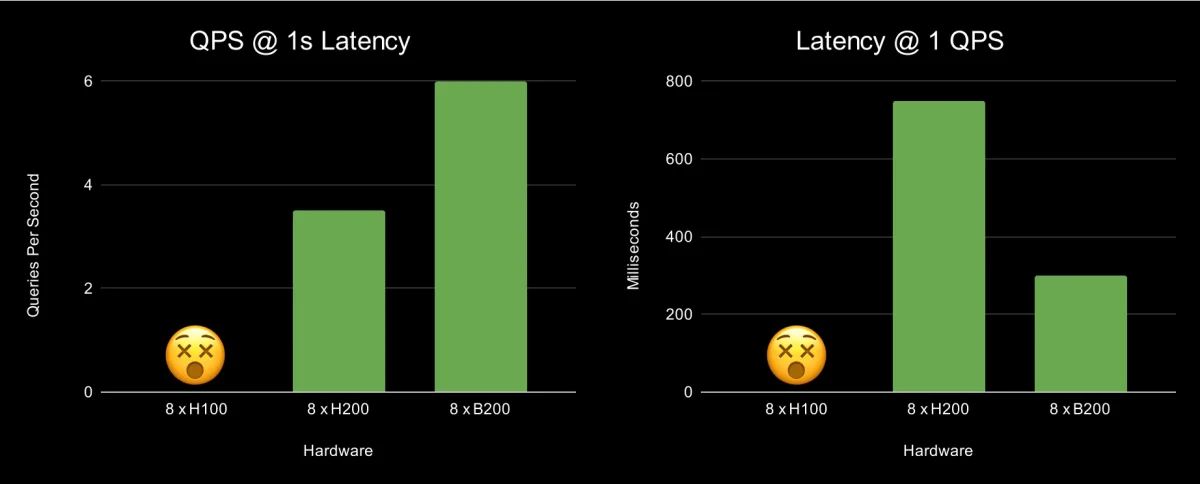
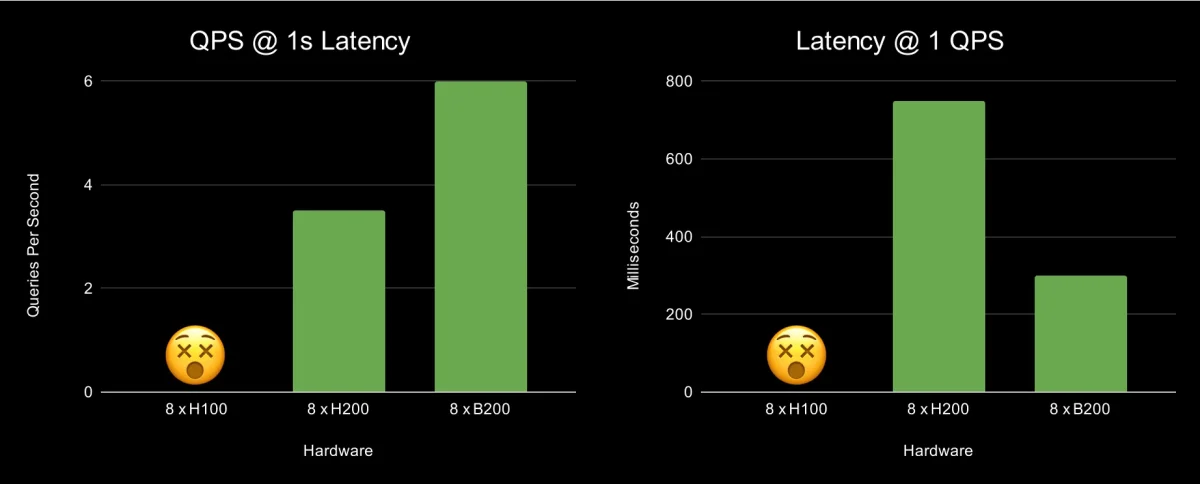
Benchmarking results from the vLLM engine demonstrate substantial performance gains when using a Large Mixture-of-Experts Language Model with the necessary resources:
- The median time-to-first-token improved by 2.5x on B200s compared to H200s at a single request per second.
- Queries-per-second rates surged to 1.7x higher on B200s compared to H200s at one second median time-to-first-token.
This performance can be harnessed directly on Modal with a simple code sample, showing how easy it is to access these powerful resources.
Why Choose Modal for B200 and H200 GPUs?
Modal differentiates itself by offering an effortless way to deploy GPU-based applications with no upfront commitments. By leveraging custom infrastructure, users can quickly activate GPU containers for their code, often in under a second. Modal's platform is designed for seamless autoscaling, enabling users to utilize hundreds of GPUs as needed while ensuring that they only pay for the compute resources they actually use.
Moreover, Modal provides $30 worth of free compute monthly, allowing users to explore the features of B200s and H200s without any initial investment. Interested users can sign up to start experiencing these powerful GPUs right away.


