Understanding the Need for Flexible GPU Capacity in AI Development
- Gate
- Machine Learning
- Departs
- Crew
- Erik Bernhardsson
- Passengers
- 716
AI's demand for GPU compute is surging, but supply challenges exist. Exploring the shift to on-demand GPU models highlights implications for startups and the industry.
The growth of generative AI has precipitated a substantial increase in GPU demand, especially for training complex models such as Copilot and Suno. This surge, however, is clashing with a constrained supply of GPUs, creating an imbalance in the cloud GPU market that distinguishes it from other cloud sectors.
Monetizing AI Models: The Role of Inference
AI heavily relies on GPUs to power operations, with the primary focus currently resting on training large generative models. However, the challenge lies in the need to eventually turn this computational cost into revenue. This is where inference— the less glamorous but financially crucial counterpart to training—comes into play.
Despite being the revenue-generating process post-training, inference workloads are often overshadowed by the intensive GPU consumption required for training. This reflects the industry's current stage, where creators must invest heavily in training to tap into the significant revenue potential of inference. However, for the economic cycle to sustain itself, a more substantial portion of GPU expenditures must shift toward inference.
The Volatility of Inference Workloads
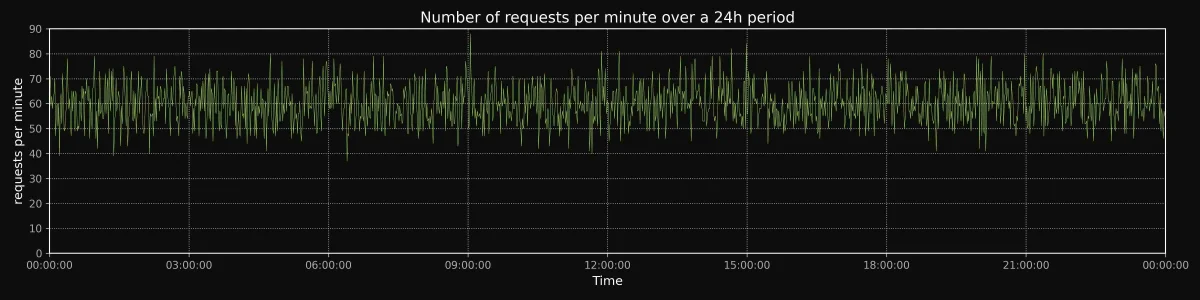
When planning for inference, a key issue arises: its variability. For instance, an average service might expect just one request per second, yet the distribution of requests often resembles a Poisson process, meaning that demand can fluctuate unpredictably.
Consider a scenario where each request requires 10 seconds to resolve. While an organization might think they need precisely 10 GPUs for constant utilization, real-world scenarios necessitate a buffer. Typically, provisioning around 12 to 15 GPUs running at 60-75% utilization is more practical to accommodate this variability and ensure service reliability.
Complications Over Time: Daily and Weekly Cycles
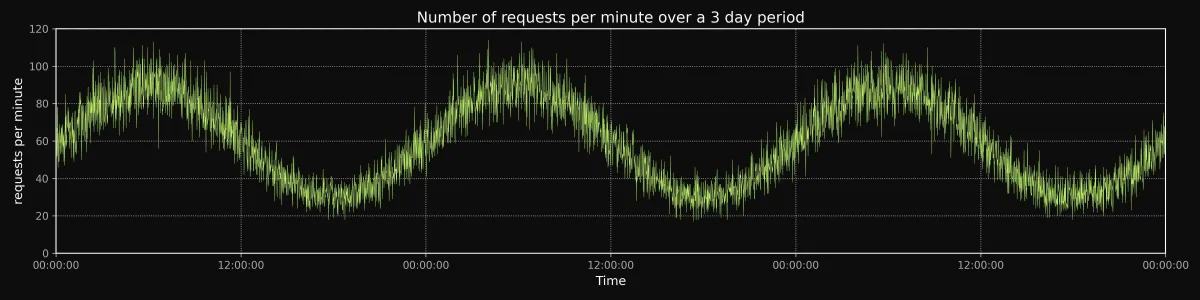
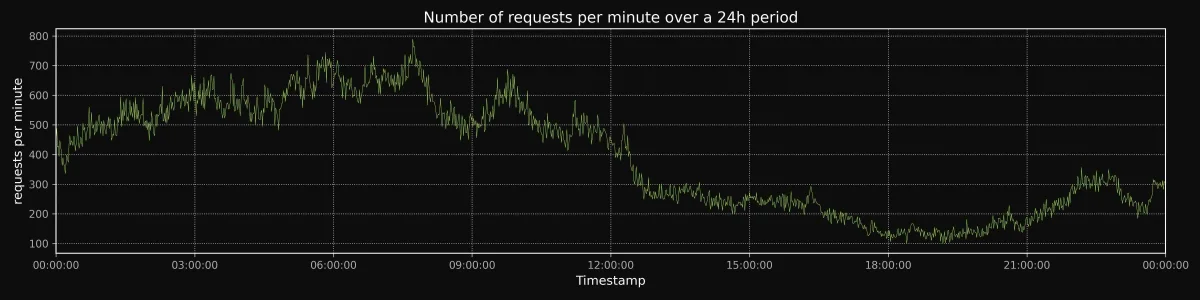
Factors like the daily cycle also contribute to the complexity of GPU provisioning. Request rates often resemble a sine wave over 24 hours, resulting in peak usage times that might drop overall GPU utilization below 50%. Therefore, if fixed capacity is set too rigidly, organizations risk being over-provisioned at off-peak times, leading to wasted resources.
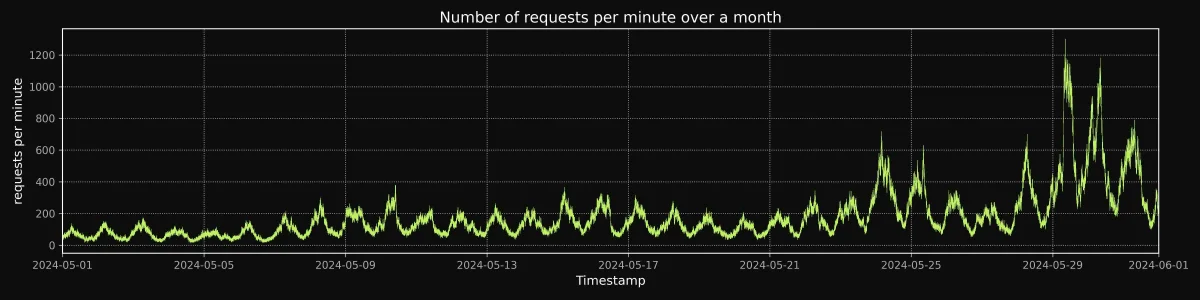
Furthermore, additional sources of demand variability exist, such as weekly cycles, unforeseen events (like a tweet going viral), and longer-term trends in service usage. Consequently, usage patterns can appear erratic in daily and monthly views, complicating capacity planning further.
Training: Another Volatile Element
The inconsistencies don't stop with inference. Training workloads share similar volatility issues. While less sensitive to latency, the demand for training resources can vary widely. Companies may experience periods of high demand due to critical tasks or exploration of new ideas, requiring spurts of GPU availability for short durations.
Other Workloads Also Require Flexibility
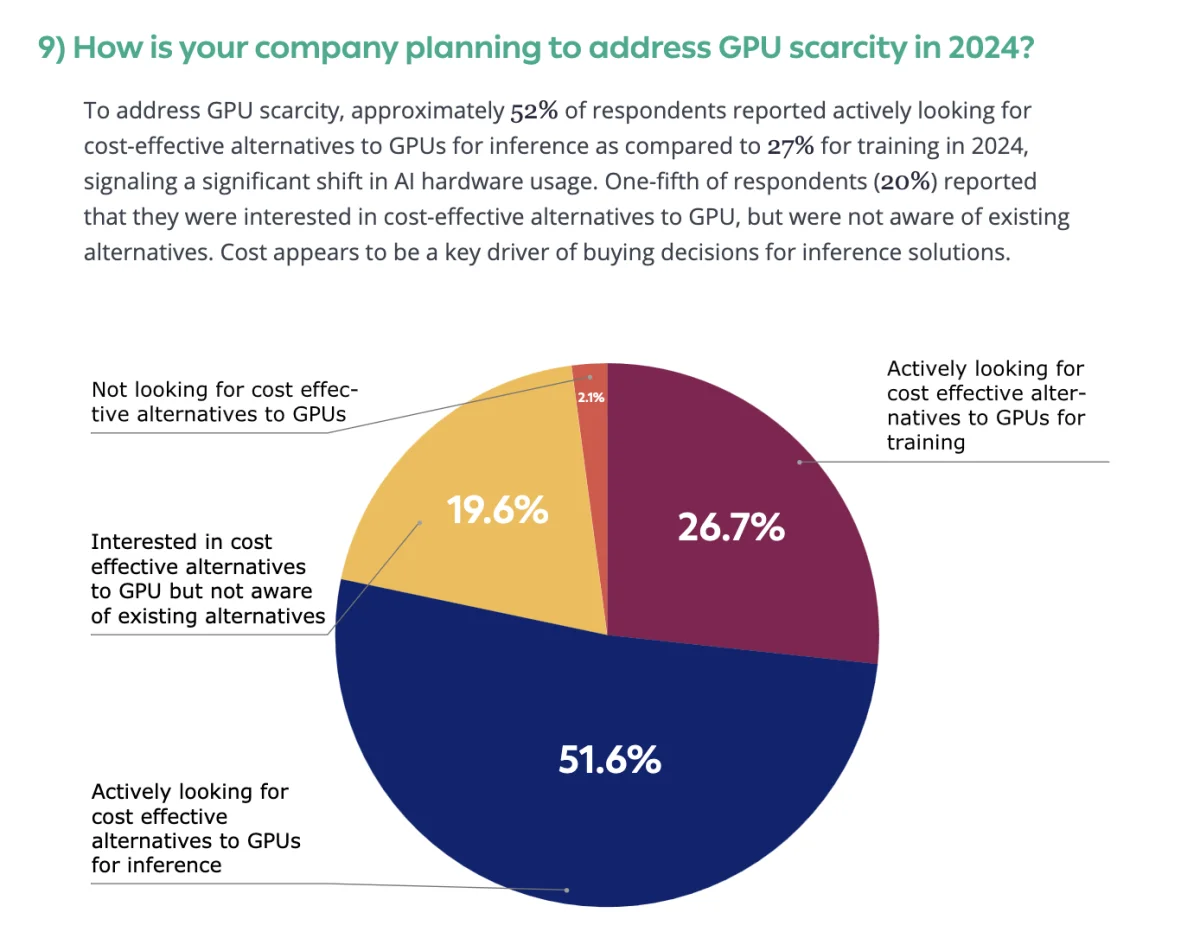
It's not just inference and training that are subject to unpredictability. Batch jobs, small training tasks, and other computational tasks also benefit from flexible GPU consumption. Data from the field indicates that large GPU clusters often operate with utilization rates falling below 50%, highlighting the need for better handling of workload peaks and troughs.
Adapting GPU Supply for On-Demand Consumption
Beyond understanding demand, flexibility in GPU supply could play a pivotal role. The goal would be to make GPU consumption more adaptable, resembling the current CPU market where flexibility is the norm. While creating a flexible GPU supply model poses challenges, several potential strategies could be effective.
Demand Pooling
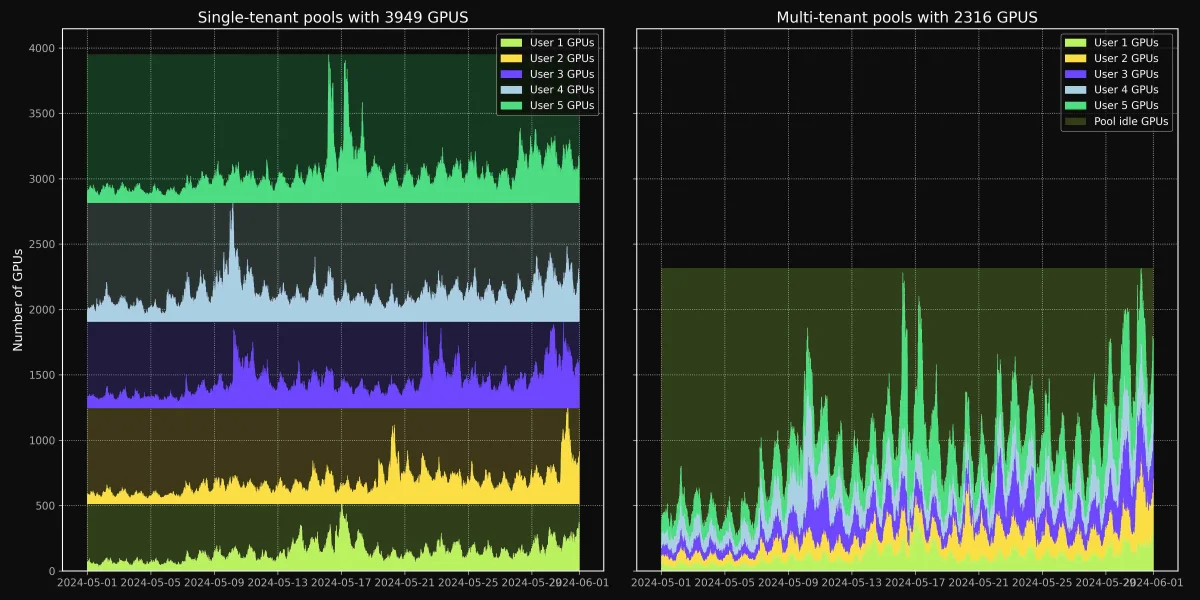
One effective strategy involves pooling demand from various users into a single compute source, dramatically improving utilization rates. In this model, instead of catering to each user’s individual peak demands, providers can meet the collective peak demand across all users, optimizing resource allocation.
Supply Pooling
Pooling the GPU supply can also enhance capacity. Utilizing multiple regions could allow providers to offload requests across geographical boundaries with minimal impact on performance, benefiting certain applications like Stable Diffusion. Additionally, aggregating different GPU types and incorporating older models could help maximize the operational efficiency of GPU resources.
Fast Scaling in Multi-Tenancy Setups
With a multi-tenant setup, fast scalability becomes critical, especially given the need for quick provisioning and managing variance in demand. Quick response times for spinning up GPU instances greatly affect overall utilization, enabling systems to allocate resources where and when they are most needed without delay.
Demand Smoothing Techniques
Another approach to managing variance is demand smoothing—shifting less time-sensitive workloads to periods of lower overall demand. Implementing features like providing discounts for these jobs could help balance the load effectively over time, further refining resource usage.
Anticipating the Future of GPU Consumption
Looking forward, several trends regarding GPU utilization appear likely:
- Increased focus on inference-driven workloads as opposed to sole training efforts.
- Expansion in the market for on-demand GPU options to accommodate unpredictable demand.
- Higher adoption of on-demand capabilities for smaller and medium-sized training tasks due to enhanced flexibility.
- While long-term GPU reservations will remain for cost savings, the reliance on flexible models will grow.
Companies poised to invest in flexible consumption models, such as Modal, are actively working to develop systems that support bursty workloads and scalable GPU functions that can adjust dynamically to varying demand. As industry conditions continue to evolve, the emphasis on adaptable GPU capacity will become increasingly essential for AI development.


