Leveraging Search with LLaMA: Surpassing GPT-4o in Python Tasks
- Gate
- Machine Learning
- Departs
- Crew
- Charles Frye
- Passengers
- 642
This exploration shows how scaling search techniques with the LLaMA model can match or surpass the performance of GPT-4o in coding tasks, highlighting practical implications.
Richard Sutton's concept of the "Bitter Lesson" underscores the significant power of general-purpose methods, particularly how search and learning adapt as computational resources expand. While it's often asserted that only larger models can achieve frontier capabilities, recent findings suggest that smaller models, when coupled with effective search strategies, can challenge this notion.
The recent arXiv paper titled Large Language Monkeys illustrates this concept by demonstrating that smaller generative models can yield impressive performance in certain domains, provided that the right search techniques are employed. Importantly, this suggests a potential pathway for organizations to utilize smaller models more effectively and economically, dispelling the myth of total reliance on models exceeding one trillion parameters.
Experimenting with LLaMA 3.1 on HumanEval
In an effort to replicate the findings of the Large Language Monkeys paper, we conducted experiments using the LLaMA 3.1 model with a focus on the HumanEval dataset. This dataset consists of Python function specifications along with their corresponding tests, which serve as a benchmark for our evaluation.
Searching through this dataset is particularly beneficial since every candidate solution can be verified against the existing test cases, making it an objective measure of correctness without the uncertainties accompanying human evaluation. This A/B testing methodology allows us to bypass the challenges that often come with assessing AI-generated content.
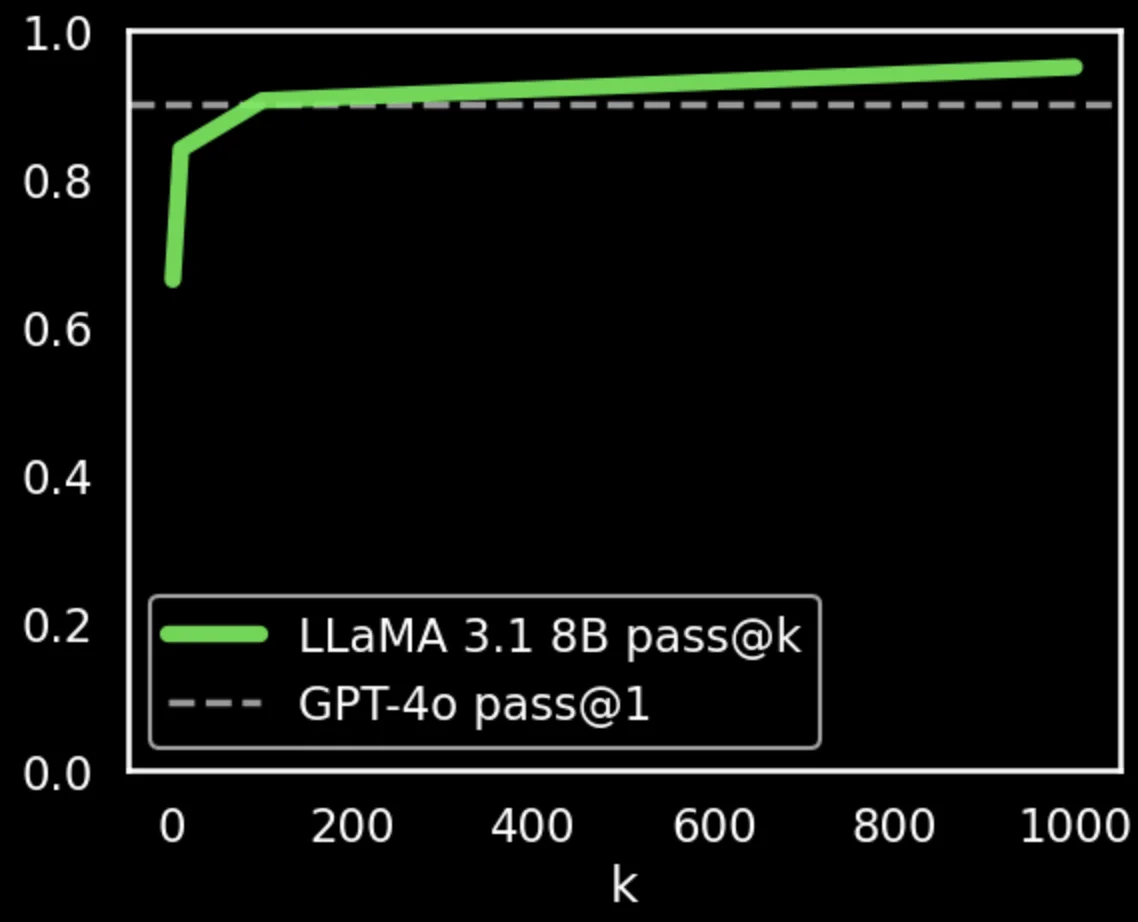
In our experiments, we aimed to determine whether LLaMA 3.1 could match or exceed the performance of GPT-4o based on the “pass@k” metric, which denotes the likelihood that at least one of the k generated solutions successfully passes the tests. For comparison, GPT-4o's pass@1 performance is reported at 90.2%, a target we aimed to reach and surpass.
Infrastructure and Evaluation Techniques
Conducting the experiments involved leveraging Modal’s serverless GPU infrastructure, which is especially advantageous for smaller models like LLaMA. This architecture facilitates rapid loading and offers a powerful arithmetic throughput advantage absent in larger models operating on fixed hardware configurations.
Utilizing vLLM inference server software, we implemented efficient caching mechanisms that enhance performance during the inference phase. By scaling our GPU resources to ten A100-40GB GPUs, we achieved an output throughput of approximately 40,000 tokens per second without necessitating complex tuning processes. This performance level confirms the efficiency of search-centric strategies, at a cost-effective rate of about $0.25 per million tokens, appealing for both startups and established enterprises.
To evaluate the model’s output effectively, we required a secure environment capable of executing arbitrary Python code. This is where Modal Sandboxes play a crucial role. These environments utilize cutting-edge containerization technology that allows for real-time creation and tearing down of execution contexts. We successfully executed around 3,000 tests in parallel, ensuring we had sufficient computational power to validate the results without pushing beyond operational limits.
Performance Comparisons and Results
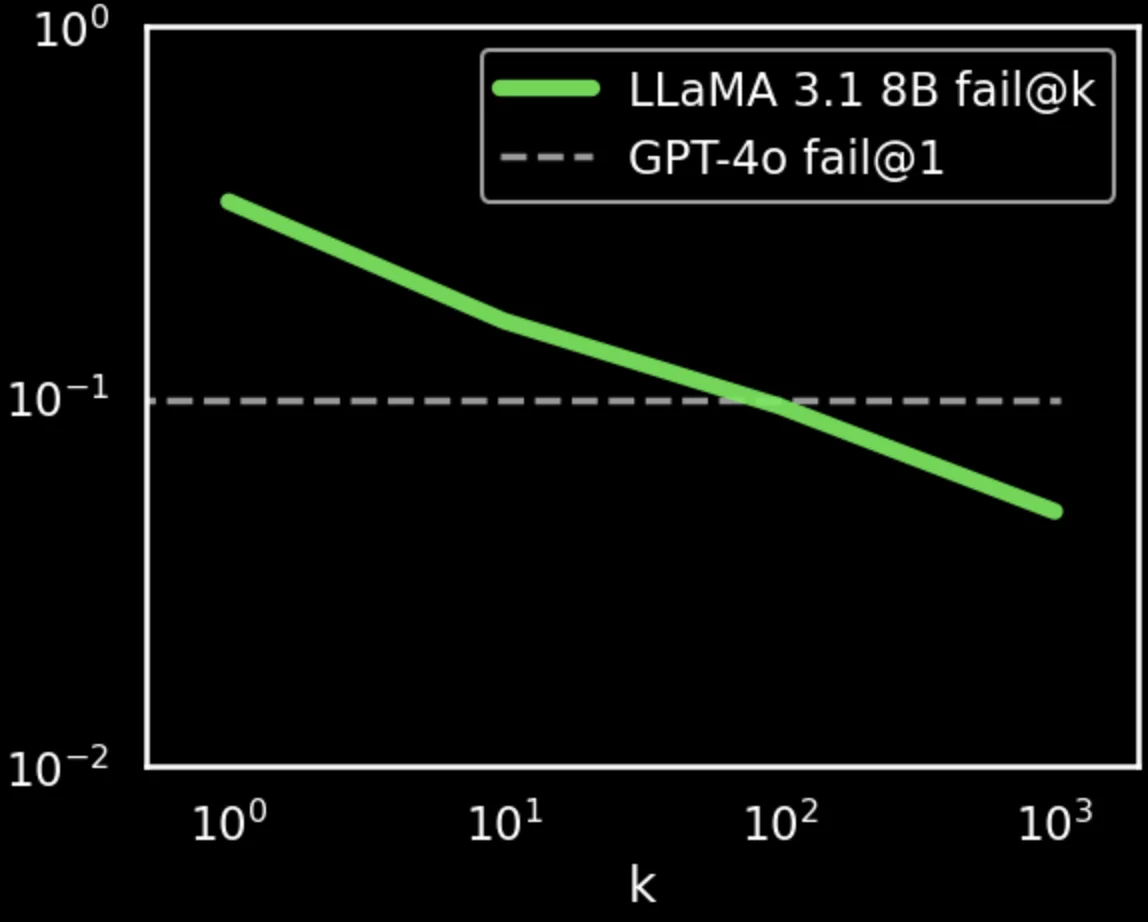
Our efforts revealed that with minimal prompt tuning, LLaMA 3.1 8B could outpace GPT-4o’s performance on HumanEval. Specifically, we noted that by increasing the number of generations, we could elevate LLaMA's pass rate from 66.4% in a single generation to 90.5% with 100 generations, ultimately achieving a 95.1% pass rate with 1,000 generations.
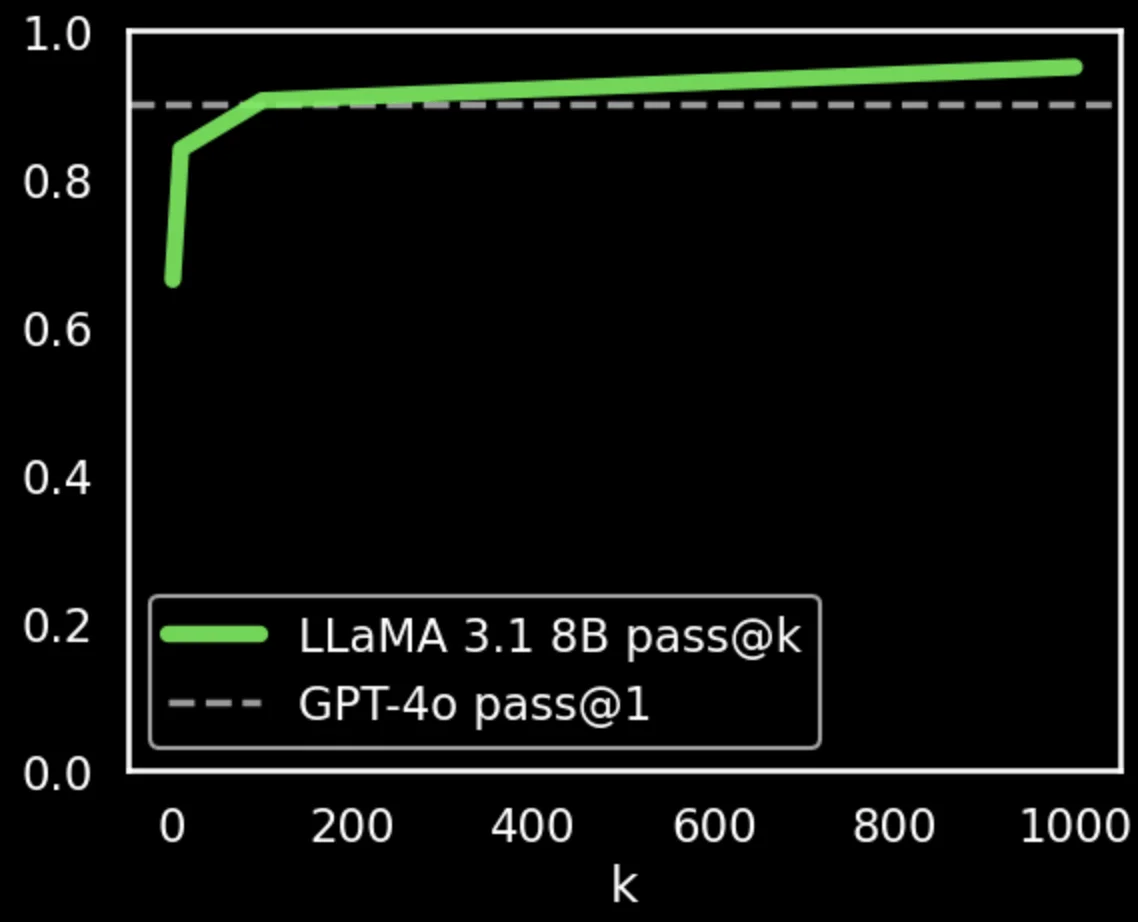
The insights garnered from our results exhibited a clear trend of predictability, revealing a logarithmic relationship between generations and success rates. This reinforces the assertion that smaller models paired with robust search techniques can emulate or even surpass larger architectures.
Future Directions
The implications of these findings are significant. Search, as a scaling method, remains underutilized in the current AI landscape, particularly given the prevailing focus on deep learning. Yet, as Sutton articulated, its adaptability to increasing computational limits positions it as a valid contender in optimizing models for intelligence tasks.
With trends in semiconductor technology further favoring compute over memory, and with platforms like Modal streamlining serverless architecture, the demand for traditional large models might diminish. The intersection of search with high-quality result evaluations also fosters a fertile ground for advancements, particularly in fields like mathematics and programming. As evidenced by DeepMind's recent mathematical contributions, formalizing problems and leveraging compilers can substantially enhance the efficacy of generative models.
While applying search techniques to less structured domains remains challenging, ongoing enhancements in evaluation metrics will likely yield better outcomes. Future explorations may focus on leveraging generative models in controlled digital environments, which can facilitate precise measurement and rapid iteration. As the effectiveness of search strategies in diverse applications grows clearer, the supply of computational resources will continue to cultivate this evolution in model use.


