Efficiently Fine-Tuning Stable Diffusion for Custom Icon Generation
- Gate
- Machine Learning
- Departs
- Crew
- Yiren Lu
- Passengers
- 440
Learn how to fine-tune Stable Diffusion for building an endless library of icons, including setup, dataset preparation, training, and deployment details.
Creating icon libraries adds a polished and cohesive appearance to web interfaces. At Modal, we often utilize Lucide and Heroicons, the latter being a free resource from the creators of Tailwind CSS. While these libraries are invaluable, they inevitably have limitations. For instance, if our application requires specific icons for concepts like golden-retriever or barack-obama, we find ourselves lacking the necessary resources.
Imagine if icon libraries could be infinite, much like Borges’ Biblioteca de Babel. Generative models such as Stable Diffusion offer this potential. After training on sufficient example data, these models learn to replicate the generative processes that create that data, allowing for endless new designs.
Fine-Tuning Experiment Overview
As a proof of concept, we took the Stable Diffusion model and fine-tuned it using the Heroicons library dataset.
Here’s an example of an icon it generated for barack-obama:
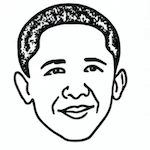
You can experiment with the fine-tuned model here.
Through this process, we produced several appealing black-and-white line icons that emulate the Heroicons style:
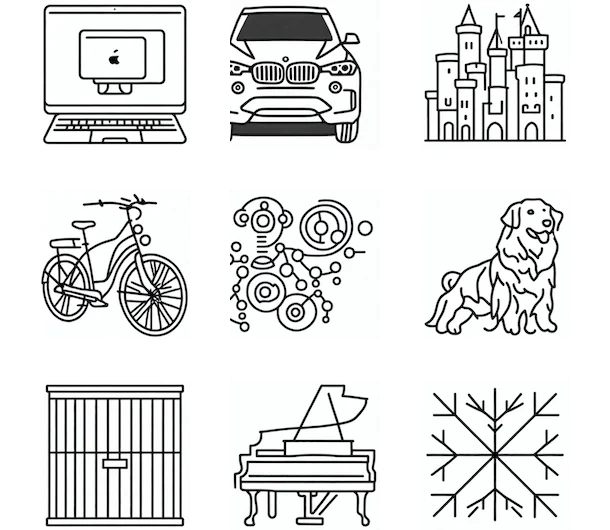
apple-computer, bmw, castle.Middle row:
ebike, future-of-ai, golden-retriever.Bottom row:
jail, piano, snowflakeThe entire workflow, from downloading a pretrained model to fine-tuning and serving an interactive web application, is facilitated by Modal—a scalable, serverless cloud computing platform that simplifies infrastructure management.
Implementation Steps
This blog post will detail the process of fine-tuning the model, exploring these key steps:
- Choosing a fine-tuning technique
- Setting up accounts
- Preparing the dataset
- Training on Modal
- Serving the fine-tuned model
- Wrapping inference in a Gradio UI
- Parting thoughts
Choosing a Fine-Tuning Technique
The first decision in fine-tuning a model revolves around the method employed. Here are several techniques:
- Full fine-tuning: Updates the entire model during training. This method is memory-intensive and computationally expensive, imposing significant demands on resources.
- Sequential adapter fine-tuning: Involves appending new layers to the model which require less memory than full fine-tuning. However, it does not modify the initial layers, potentially limiting representation adjustment.
- Parallel adapter fine-tuning: Inserts new layers alongside existing ones, utilizing GPU parallel processing and has gained popularity with techniques like Low Rank Adaptation (LoRA).
For our purposes, full fine-tuning proved most effective, particularly given the size of our dataset.
Setting Up Accounts
To follow along with this implementation, create the necessary accounts for the following platforms:
Preparing the Dataset
Dataset preparation is a critical step often understated in blog posts. Our experience indicates that it's typically the most challenging aspect of the fine-tuning process. For fine-tuning using the Heroicons dataset—which consists of roughly 300 SVG icons—we proceeded with the following steps:
- Download the Heroicons from the GitHub repository.
- Convert the SVGs to PNGs and apply white backgrounds—as image models require rasterized graphics.
- Generate captions corresponding to each image and create a
metadata.csvfile, associating image filenames with their captions. - Upload the prepared dataset to the HuggingFace Hub.
Here’s an example configuration for how the directory structure of your dataset should look:
# tree heroicons_training_dir
heroicons_training_dir/
 ├── arrow.png
 ├── bike.png
 ├── cruiseShip.png
 └── metadata.csv
And a snippet of the metadata.csv file:
# metadata.csv

file_name,text
arrow.png,"an icon of a arrow"
bike.png,"an icon of a bike"
cruiseShip.png,"an icon of a cruise ship"
You can explore the post-processed dataset here.
Training on Modal
We employed the Diffusers library from HuggingFace, which offers straightforward scripts for fine-tuning models on custom datasets. For our task, we used the train_text_to_image.py script, which implements full fine-tuning.
Setting Up Diffusers Dependencies
While running the code on Modal, all dependencies must be set up in a containerized cloud environment. Modal allows this by providing an easy-to-use API that functions like a Dockerfile without the associated complexity.
# fine-tune-stable-diffusion.py
import os
from dataclasses import dataclass
from pathlib import Path
from fastapi import FastAPI
from modal import Image, App, Volume, gpu

image = (
    Image.debian_slim(python_version="3.10")
    .pip_install(
        "accelerate==0.27.2",
        "datasets~=2.19.1",
        "ftfy~=6.1.1",
        "gradio~=3.50.2",
        "smart_open~=6.4.0",
        "transformers~=4.38.1",
        "torch~=2.2.0",
        "torchvision~=0.16",
        "triton~=2.2.0",
    )
)
Setting Up Volume for Model Weights
Modal also provides Volumes for persistent storage of model weights. These can be used to store weights post-training and accessed during the inference phase.
# fine-tune-stable-diffusion.py

model_volume = Volume.from_name("diffusers-model-volume", create_if_missing=True)

VOLUME_CONFIG = {
    "/model": model_volume,
}
Hyperparameter Configuration
We conducted the fine-tuning based on the StableDiffusion v1.5 model. Our training setup included:
- 4000 training steps
- Learning rate of
1e-5 - A batch size of 1
We defined configurations for both training and inference using dataclasses:
# fine-tune-stable-diffusion.py

@dataclass
class TrainConfig:
    model_name: str = "runwayml/stable-diffusion-v1-5"
    max_train_steps: int = 4000
    train_batch_size: int = 1
    learning_rate: float = 1e-05

@dataclass
class AppConfig:
    num_inference_steps: int = 50
    guidance_scale: float = 20
Running Fine-Tuning
Next, we prepare the training function decorated with @app.function to indicate to Modal that this particular function should run in a cloud container. Signals for GPU type, Modal Volumes, and any necessary secrets for authentication are included within this decorator.
# fine-tune-stable-diffusion.py

@app.function(
    image=image,
    gpu=gpu.A100(size="80GB"),
    volumes=VOLUME_CONFIG,
)
def train():
    from accelerate import notebook_launcher
    from examples.text_to_image.train_text_to_image import main
    ...
    notebook_launcher(launch_training, num_processes=1)
With everything set up, we can initiate the training from anywhere using a single command:
modal run fine-tune-stable-diffusion.pyServing the Fine-Tuned Model
Upon completing the training, we can save the fine-tuned model in the Volume and set up a new Modal inference function to utilize it:
# fine-tune-stable-diffusion.py

@app.cls(
    image=image,
    gpu="A10G",  # less VRAM is needed for inference
    volumes=VOLUME_CONFIG,
)
class Model:
    @enter()
    def load_model(self):
        from diffusers import StableDiffusionPipeline
        self.pipe = StableDiffusionPipeline.from_pretrained(MODEL_DIR).to("cuda")

    @method()
    def inference(self, text, config):
        image = self.pipe(text, num_inference_steps=config.num_inference_steps, guidance_scale=config.guidance_scale).images[0]
        return image
Wrapping Inference in a Gradio UI
Finally, we establish a Gradio interface that enables user interaction with our icon generator. We define an app that connects to the Model.inference function:
# fine-tune-stable-diffusion.py

@app.function(image=image, max_containers=3)
@asgi_app()
def fastapi_app():
    ...
    interface = gr.Interface(fn=go, inputs="text", outputs=gr.Image(shape=(512, 512)), title="Generate custom heroicons", description=description)
    return mount_gradio_app(app=web_app, blocks=interface, path="/")
Deployment is straightforward with a simple command:
modal deploy fine-tune-stable-diffusion.pyParting Thoughts
After going through the fine-tuning process, how well does our newly created model function as an infinite icon library?
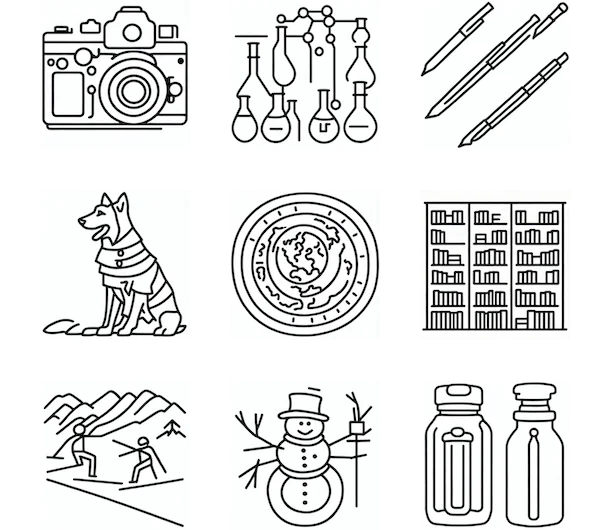
camera, chemistry, fountain-pen.While the results are impressive, they are not without their flaws. Common issues include:
- Occasionally generating multiple objects for a single prompt (ex:
water-bottle,fountain-pen). - Visual artifacts or odd shapes in some cases (ex:
snowman). - Less simplified outputs compared to the original Heroicons (ex:
camera,german-shepherd).
Fine-tuning performance can vary significantly based on hyperparameter choices, including dataset size, learning rates, and other configurations.
Given that we set the training to run in Modal, scaling up to conduct extensive grid searches is well within reach. You can easily test different combinations of hyperparameters across numerous training sessions with just a few lines of code.
RESOLUTIONS = [128, 512]
LEARNING_RATES = [1e-5, 1e-4, 1e-3, 1e-2, 1e-1]
LEARNING_RATE_SCHEDULERS = ["constant", "cosine"]

@app.local_entrypoint()
def run():
    for resolution in RESOLUTIONS:
        for learning_rate in LEARNING_RATES:
            for learning_rate_scheduler in LEARNING_RATE_SCHEDULERS:
                train.spawn({...})
Evaluating the most effective combinations of hyperparameters will likely require a nuanced approach, as style preferences can be highly subjective. Yet, this makes the pursuit of machine learning development both challenging and rewarding!


