Achieving Superior Performance through Fine-Tuning Open Source Embedding Models
- Gate
- Machine Learning
- Departs
- Crew
- Jason Liu
- Passengers
- 464
This article explores how fine-tuning an open source embedding model can outperform proprietary models like OpenAI's text-embedding-3-small, even with minimal data.
Fine-tuning an open source embedding model can yield higher accuracy at a lower cost than proprietary alternatives such as OpenAI’s text-embedding-3-small. This piece discusses the process of creating an effective model using Modal and presents insights from an experiment focused on the necessary amount of fine-tuning data for a question-answering use case.
The Importance of Fine-Tuning
Understanding the Role of Custom Models
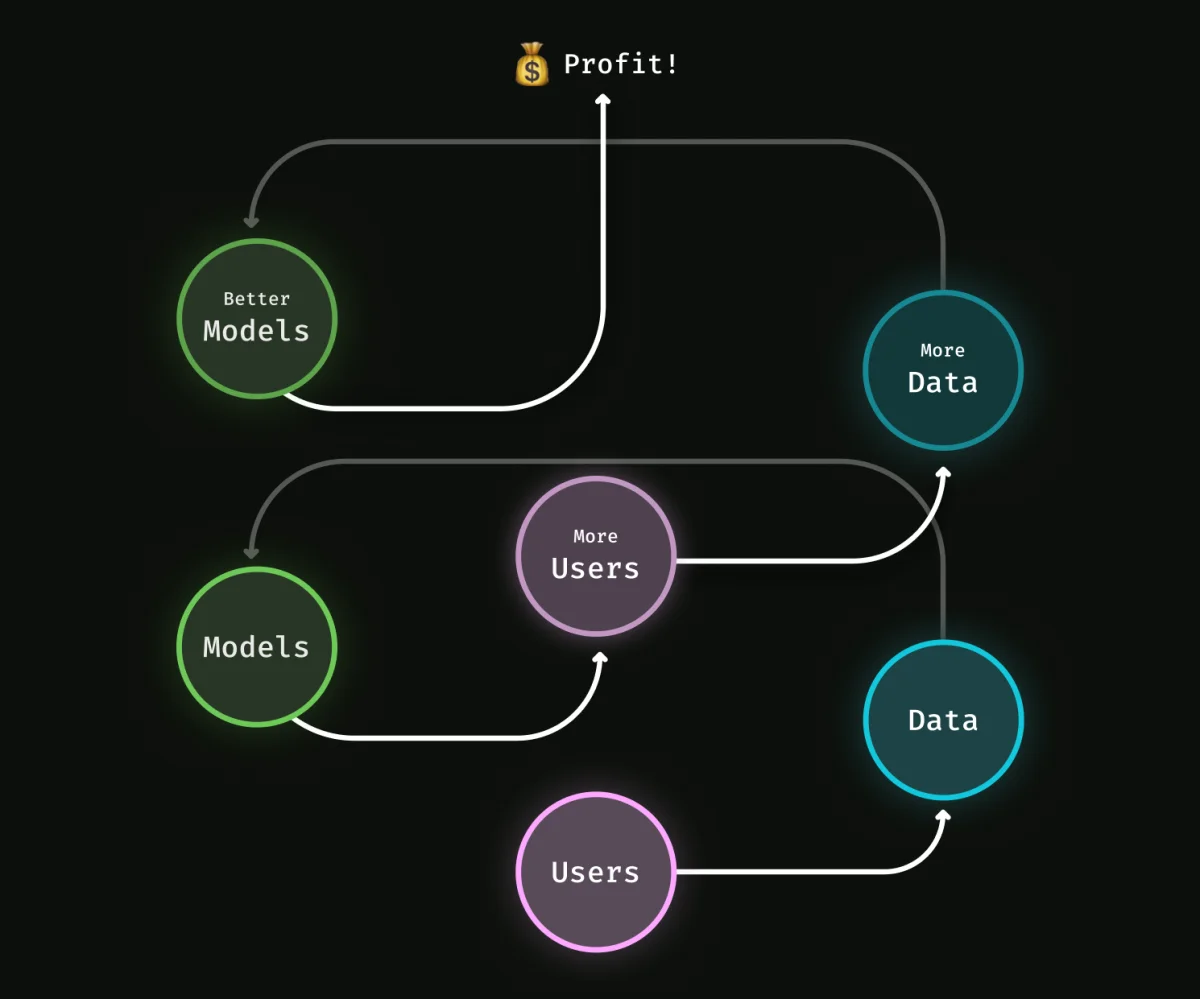
Custom machine learning models serve as the backbone for platforms like Netflix and Spotify to deliver tailored user experiences. By monitoring user interactions—such as completed movies or skipped songs—these companies refine their internal embedding models and recommendation systems, fostering improved suggestions. This iterative improvement process is encapsulated in the concept of the data flywheel, where increased user engagement results in more data collection, leading to enhanced models and, consequently, further user engagement.
While major organizations leverage years of data to build their models from scratch, startups often lack the extensive datasets necessary for their custom models. Historically, generating a viable data flywheel has demanded substantial creativity and investment. However, the emergence of highly capable pre-trained models with permissive licenses in the 2020s has simplified the initial stages of this process, allowing projects to utilize these models for reasonable performance right out of the gate.
For instance, in a prior experiment, we successfully utilized to embed the entirety of English Wikipedia within a mere 15 minutes using a serverless infrastructure.
Accelerating the Data Flywheel Through Fine-Tuning
Access to pre-trained models and an infrastructure capable of running them presents a significant advantage for organizations without existing user data. Rapidly advancing to a customized model that demonstrates superior performance over off-the-shelf solutions is critical. The good news is that user interaction quickly translates into valuable data; just a few dozen users engaging with a service multiple times daily can yield hundreds of data points in mere days.
This amount of data was sufficient for our experiment: we trained a model that outperformed OpenAI’s text-embedding-3-small in identifying textual similarities based on a sample dataset.
Using Modal’s scalable serverless infrastructure, we not only generated embeddings from an existing model but also implemented fine-tuning, which helps enhance performance while significantly cutting operational costs—a critical first step in establishing your own data flywheel.
The Mechanics of Fine-Tuning: Choosing Datasets, Models, and Infrastructure
Embarking on the fine-tuning process entails several design decisions, which we will outline here.
Dataset Selection: Finding or Creating the Right Data
In machine learning, the dataset is often more crucial than the model itself. Typically, embedding models are developed using datasets made of pairs of items, where certain pairs are flagged as “similar” and others as “different.” This principle applies across various formats, whether it is text, images, audio, or combinations thereof.
For our experiment, we utilized the Quora dataset, which comprises pairs of questions marked for duplicates. This specific dataset will enhance our model's performance in recognizing nuanced differences in questions, making it applicable for retrieval-augmented generation (RAG) chatbots.
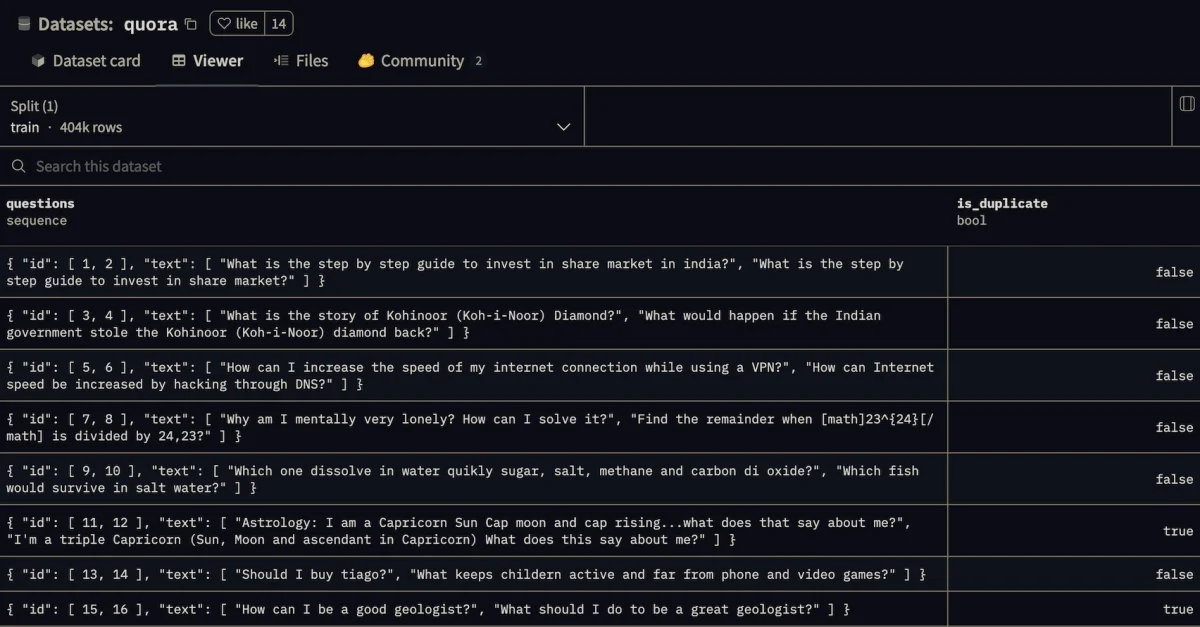
This dataset trains the model to detect very small distinctions in question topics and aids in either removing near-duplicates before retrieval or during training, a process referred to as “semantic deduplication.”
Selecting a Base Model for Fine-Tuning
For our purposes, focusing on permissively licensed models that allow for easy weight modifications is essential. Known as “open source” models (though not all strictly meet the Open Source Initiative's definitions), these models are commonly available via Hugging Face’s model repository. In contrast to fine-tuning proprietary models through APIs, we prefer open-source models due to the need for precise control over the training process that fine-tuning demands.
Choosing among available models generally depends on observed performance in public benchmarks like MTEB. Additionally, it is crucial to assess resource efficiency and throughput/latency, referring again to benchmarking data from reliable sources such as Lambda Labs.
Factors to consider include the embedding dimension. While larger embeddings may offer enhanced performance, they incur greater costs associated with storage and processing. During fine-tuning, this dimension can be adjusted according to specific use cases.
Infrastructure Requirements for Training
Fine-tuning necessitates considerable compute power. Though models might run efficiently on CPUs, GPU-based training is preferable given their high throughput capabilities for parallel workflows. A typical fine-tuning operation might require one to eight server-grade GPUs, with configurations beyond that leading to increased cost and complexity.
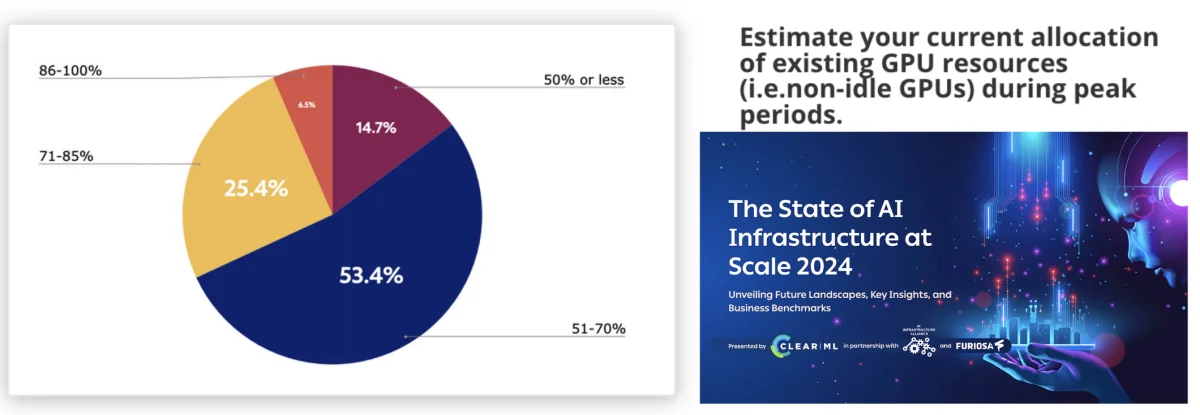
Server-grade GPUs are not only in high demand but also expensive to acquire or rent. Cloud services usually mandate minimum commitment durations and capacities, which are problematic for the less predictable nature of fine-tuning jobs. As a result, organizations often face over-allocation issues, leading to significant waste. Surveys indicate that current average peak utilization for such resources hovers around 60% or even lower during off-peak times, making cost management necessary.
Modal addresses these challenges by providing a serverless infrastructure that scales according to actual usage, enabling users to pay only for necessary compute. This innovative model allows data scientists and machine learning experts to maintain control over their infrastructure without the typical overhead associated with traditional setups.
Once the infrastructure is in place, a thorough approach to scoping the training process includes grounding efforts in established metrics or aiming for specific performance criteria while enforcing limits on resource and time expenditures.
Conducting a Grid Search for Fine-Tuning Hyperparameters
Exploring new model architectures or tasks equates to a broad research endeavor, necessitating proper scoping. However, fine-tuning allows for more straightforward utilization of pre-existing training recipes, enabling experimentation particularly regarding hyperparameters.
For our experiment, we identified three crucial parameters: the choice of pre-trained model, the dataset size for training, and the output dimension count. These hyperparameters influence the values of weights and biases within the model.
An effective strategy for hyperparameter exploration is grid searching, where every combination of selected hyperparameters is assessed. Although a brute-force technique, grid search is efficient and lends itself well to parallelization.
We used several model variations in our grid search, including bge-base-en-v1.5, sentence-transformers/all-mpnet-base-v2, and jinaai/jina-embeddings-v2-small-en, experimenting with embedding dimensions and dataset sizes varying from 100 to over 100,000 samples:
MODELS = [
    "BAAI/bge-base-en-v1.5",
    "sentence-transformers/all-mpnet-base-v2",
    "jinaai/jina-embeddings-v2-small-en",
]
DATASET_SIZE = [
    100, 200, 400, 800, 1600, 3200,
    6400, 12800, 25600, 51200, 102400,
]
DENSE_OUT_FEATURES = [256, 512]
All additional hyperparameters remained constant. Then, we generated configurations using the product function from Python’s itertools module, creating an iterator that generates every potential combination from our inputs.
def generate_configs():
    for model, sample_size, dense_out_features in product(
        MODELS, DATASET_SIZE, DENSE_OUT_FEATURES
    ):
        yield grid_search_config(model, sample_size, dense_out_features)
Each fine-tuning process requires configuration inputs, which, in turn, produce performance outcomes. We encapsulated this process in a function decorated with @app.function(), which integrates seamlessly with Modal’s serverless architecture.
@app.function(gpu="A10G")  # configure autoscaling and other infra parameters here
def objective(config) -> dict:
    model = Model.from_config(config)
    model.setup()
    results = model.train()
    return results
To facilitate scaling, the function objective.map runs experiments in parallel, while being wrapped in a command-line callable function, enabling easy experimentation through Modal CLI.
@app.local_entrypoint():
def run():
    results = []
    for experiment_result in objective.map(generate_configs()):
        results.append(experiment_result)

    df = pd.DataFrame(results).sort_values("metric_accuracy", ascending=False)
    df.to_csv("trial_results.csv", index=False)
With our training process capable of operating on a single GPU while allowing for parallel execution of experiments, scaling up to thousands of simultaneous workers through Modal can drastically reduce the time needed for experimentation.
Exceeding Proprietary Model Benchmarks with Limited Data
The following figure summarizes our findings, illustrating the error rates (incorrect prediction fractions) from the models we fine-tuned on the Quora dataset, based on varying dataset sizes. For comparative context, the performance of OpenAI’s text-embedding-3-small model is included. We explored different embedding dimensions, although we found no performance disparity based on this aspect across hyperparameter settings.
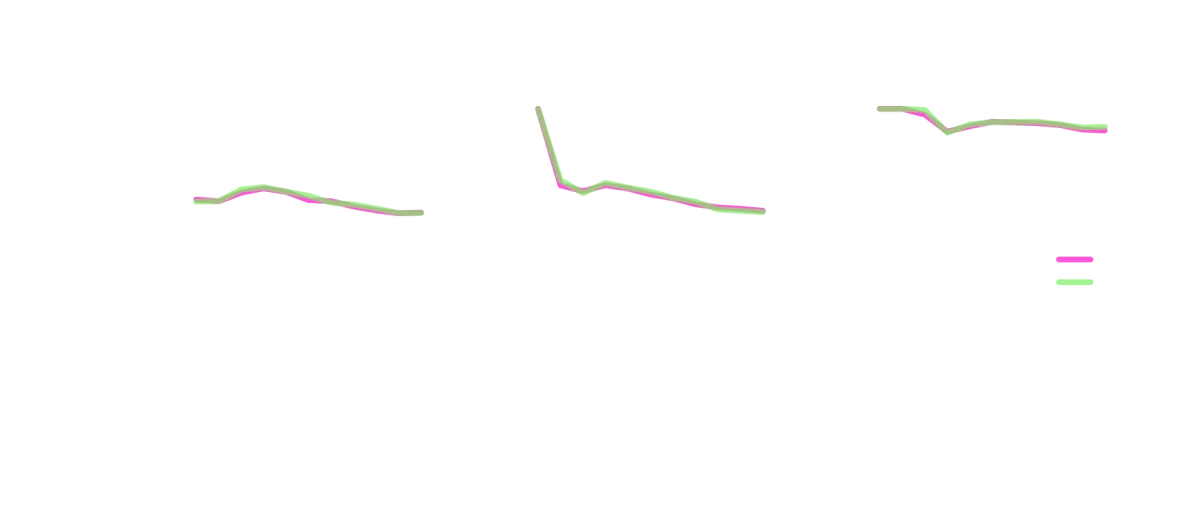
Several trends emerged from our observations:
- The
jina-embeddings-v2-small-enmodel exhibited a consistently higher error rate than the baseline across all dataset sizes with no indication of improvement. Such results underscore the importance of carefully tuning various hyperparameters. - The
all-mpnet-base-v2model demonstrated a lower error rate than the baseline at just 100 examples, but showed limited improvement, suggesting it might plateau quickly. - The
bge-base-en-v1.5model initially performed worse than the baseline but improved significantly as the dataset size increased, eventually outperforming the baseline by 200 examples and continuing to improve with a data size of 100,000 samples.
Based on these results, we’d prioritize the fine-tuned bge-base-en-v1.5 model moving forward, primarily if we anticipate accumulating more data through a data flywheel. The 256-dimensional embedding is likely the better option due to its lower cost and minimal loss in accuracy compared to the 512-dimensional alternative.
Although the absolute improvement might seem modest—17% error rate versus 13%—the relative difference denotes a significant enhancement, with a quarter of baseline errors mitigated by the fine-tuned model. Such improvements become increasingly impactful as error rates approach lower thresholds where the difference between being 95% or 99% reliable can dictate usability in critical applications.
Future Directions
This exploration illustrates how fine-tuning an open source embedding model can surpass proprietary offerings in particular applications, driven by crucial design considerations and an effective model training approach. The next logical step involves operationalizing this fine-tuning process for continuous data collection and iterative enhancements. By automating the pipeline, we could facilitate ongoing updates to the model driven by fresh user data.
Ultimately, successful machine learning implementations rely more on robust pipelines and processes for converting raw data into valuable user features than on the models themselves. With accessible open source options and adaptable serverless infrastructure, establishing these systems is more achievable than ever.


