Optimizing Sandbox Architecture for Handling Millions of Concurrent Instances
- Gate
- Machine Learning
- Departs
- Crew
- David Miller
- Passengers
- 985
Modal has reengineered its sandbox platform to support rapid scaling, achieving the creation of one million concurrent sandboxes in under a minute.
At Modal, our primary focus is on building efficient computing sandboxes for various applications, including the deployment of agents that require high performance. Currently, we manage millions of sandboxes daily, with the capacity to support up to fifty thousand concurrent sandboxes per individual customer. This capability is crucial for applications like reinforcement learning and other resource-intensive tasks that involve creating massive numbers of sandboxes rapidly.
As user demands continue to surge, we recognized that existing infrastructures weren't equipped to handle the increasing complexity and scale needed for our sandbox environments. We compelled our team to rethink our platform, emphasizing performance and scalability to better accommodate the expanding needs of our clients and applications.
Rebuilding for Scale and Reliability
Over several months, we undertook a major overhaul of our core sandbox platform to drastically enhance both scale and reliability. Under the new system, users can now run millions of sandboxes concurrently and create tens of thousands of new ones every second. We removed central bottlenecks within our control plane, ensuring that practical limits on scaling no longer exist. We also focused on optimizing every aspect of container scheduling and startup. This led to a simplification of our scheduling process through a system of load balancers that interact directly with our worker nodes.
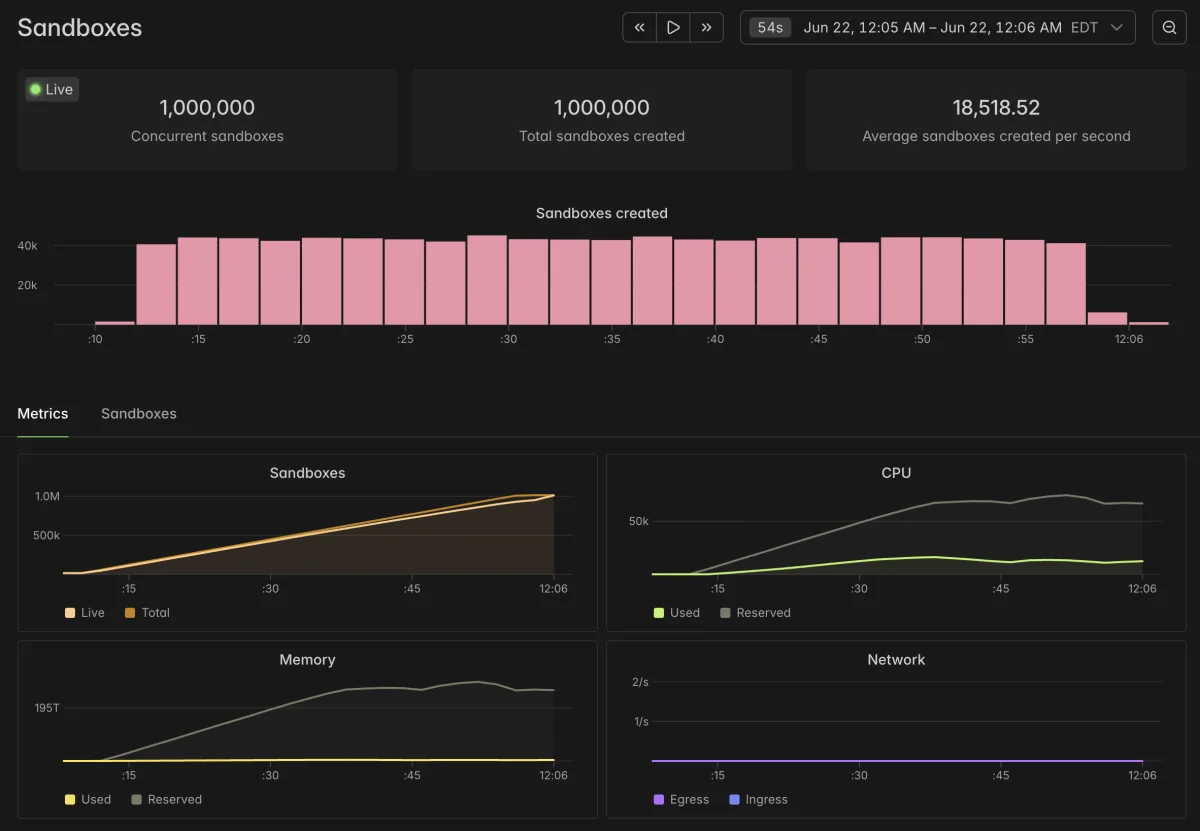
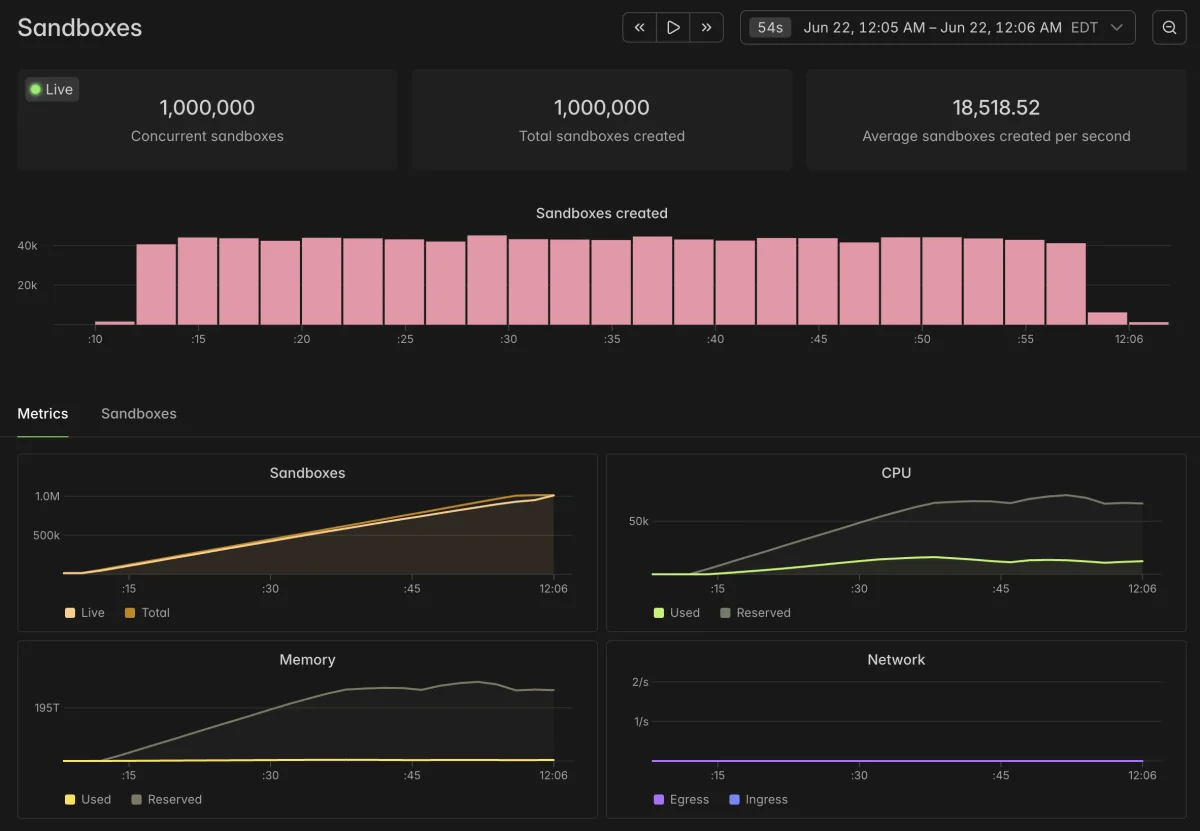
One of the most notable achievements from this reengineering process is our demonstration of successfully running one million concurrent sandboxes, creating all instances in less than a minute. This showcases our platform's significant capabilities.
The Limitations of Traditional Solutions
Running one million sandboxes is a challenging endeavor for any container management platform. The task requires tens of thousands of compute nodes, exposing limitations of traditional systems. Many operations scale exponentially with the number of containers or nodes, which typically pushes conventional platforms to their limits.
Taking Kubernetes as an example, several factors illustrate these scaling challenges:
- The scheduling algorithm throughput can degrade to O(n x p), where n represents the number of nodes and p is the number of pods, resulting in a serialized scheduling process by default.
- Each pod generates multiple writes to etcd, creating consistency bottlenecks under high volumes or quick churn rates. etcd does not support sharding within a keyspace.
- Every node must send at least one heartbeat to etcd, creating a baseline load that is strictly O(nodes) and independent of pod lifecycle events.
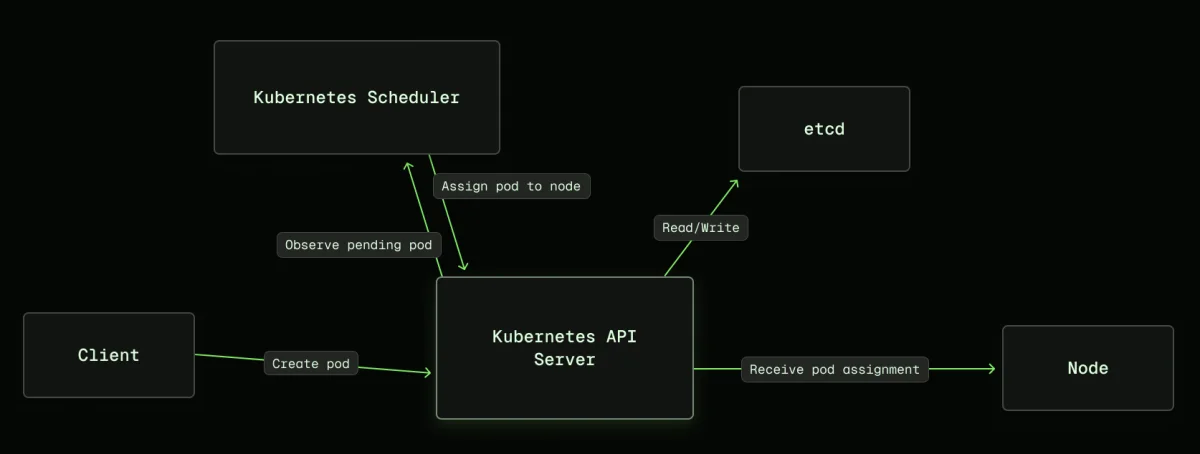
While Kubernetes can accommodate larger clusters, operational complexity increases significantly. This often involves scaling etcd or replacing elements to manage a requisite level of efficiency, which can be labor-intensive.
Introducing a New Architecture at Modal
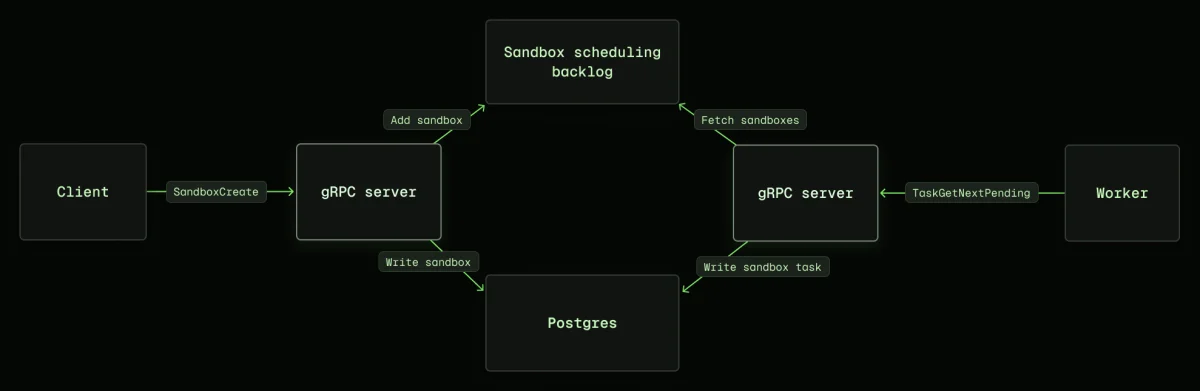
At Modal, we discovered that our existing sandbox architecture faced challenges similar to Kubernetes due to its reliance on strong consistency and global coordination for our processes. Consequently, operations scaled at O(sandboxes) or O(nodes), and certain backend elements were difficult—in some cases impossible—to scale out effectively.
By starting from scratch, we reimagined our architecture to allow for better scaling properties. Our solution involved:
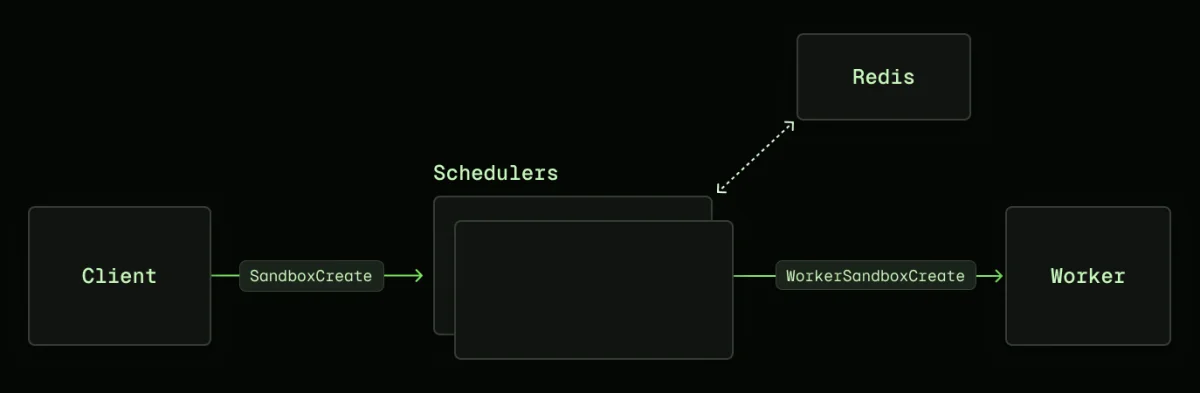
- Transitioning from a singular serialized scheduler to a distributed fleet of scheduling servers that manage sandbox creation requests concurrently. This enables horizontal scaling and achieves a load balancing-like effect in scheduling.
- Shifting away from a centralized datastore for sandbox management to individual workers acting as local sources of truth. Workers periodically publish their state to a Redis stream, allowing scheduling servers to operate more asynchronously.
- Eliminating data stores from the critical path of sandbox creation altogether. While we still write metadata and results to durable storage, these are handled in an asynchronous manner, improving overall performance.
- Batching control messages for multiple sandboxes within single RPC calls to reduce overhead.
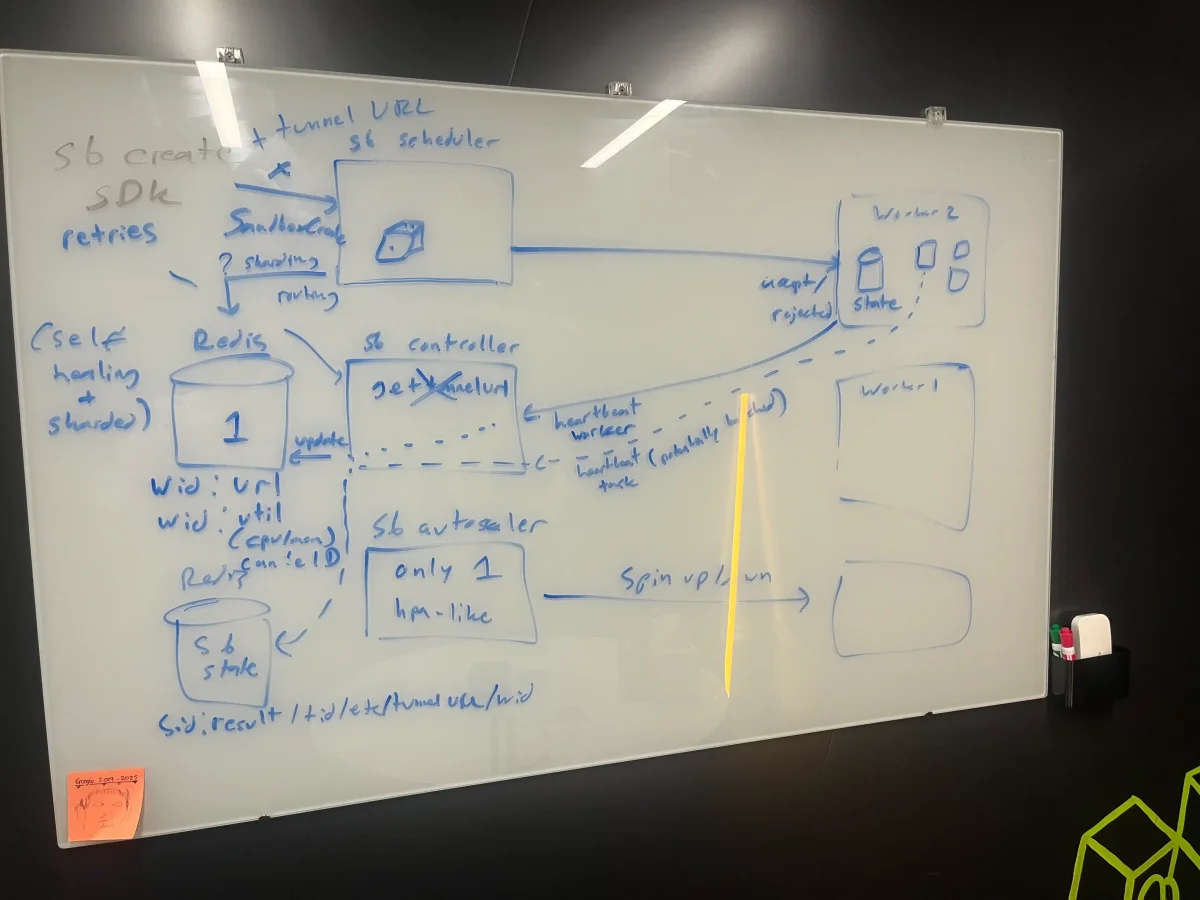
This new approach reduces the complexity of our sandbox creation path to just two network hops and a modest CPU operation. As a result, we have eliminated central bottlenecks, coordination costs, and single points of failure, allowing us to scale sandbox creation and management without practical limits.
Development Journey
Designing and implementing this new system was no minor task. It took extensive collaborative effort to finalize our architecture, involving months of iterative design sessions and prototyping efforts. We even spent a focused week away in a dedicated setting to minimize distractions while we concentrated on coding and testing our initial prototypes.
Upon returning to our primary development environment, we needed to reintegrate existing features and observability dimensions into our new system. This undertaking also involved modifying our worker management stack and container runtime to align with the new architecture's requirements.
For instance, our updated schedulers developed a propensity to push container creation requests to workers so quickly that they risked overwhelming the kernel when setting up networking rules. This required further adjustments to our networking setup to mitigate against traffic spikes during peak sandbox creation periods.
Performance Benchmarks
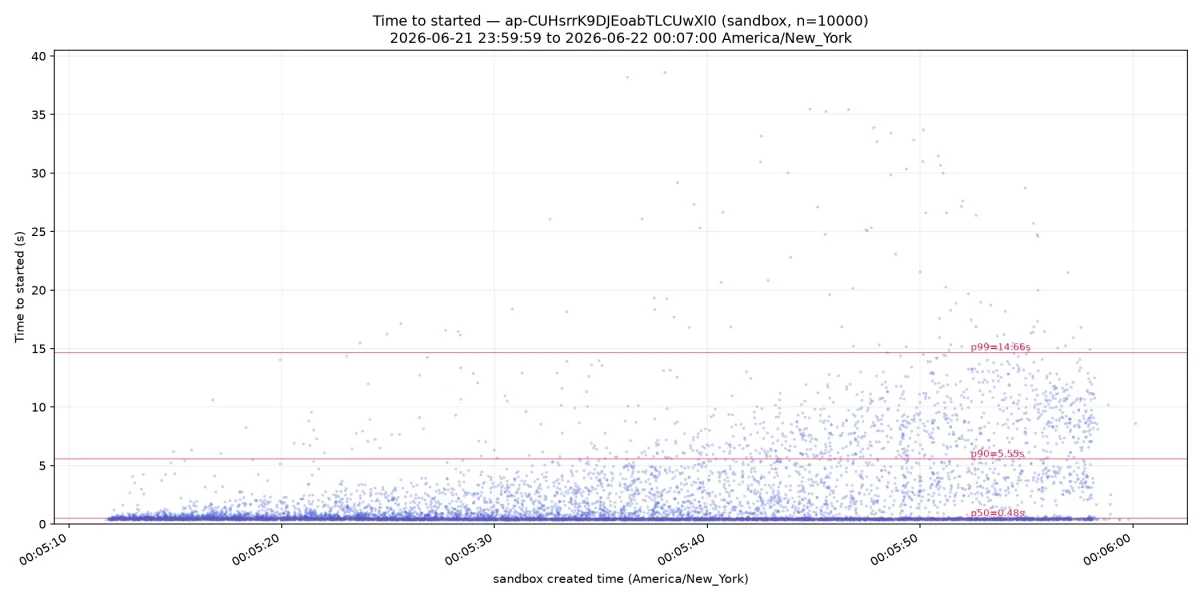
The enhancements to our infrastructure have been validated through rigorous benchmarks. We can now create one million sandboxes in well under a minute, with primary limits arising from the benchmarking setup itself rather than any inherent performance degradation.
From an operational perspective, sandbox time-to-interactivity is consistently low, sustaining efficiency irrespective of the scaling. We believe these results are a direct consequence of our design philosophy: the absence of coordination in the scheduling process leads to swift responses that remain efficient at high concurrency levels. Thus far, we haven't encountered significant hurdles in scaling our concurrent scheduling capabilities.
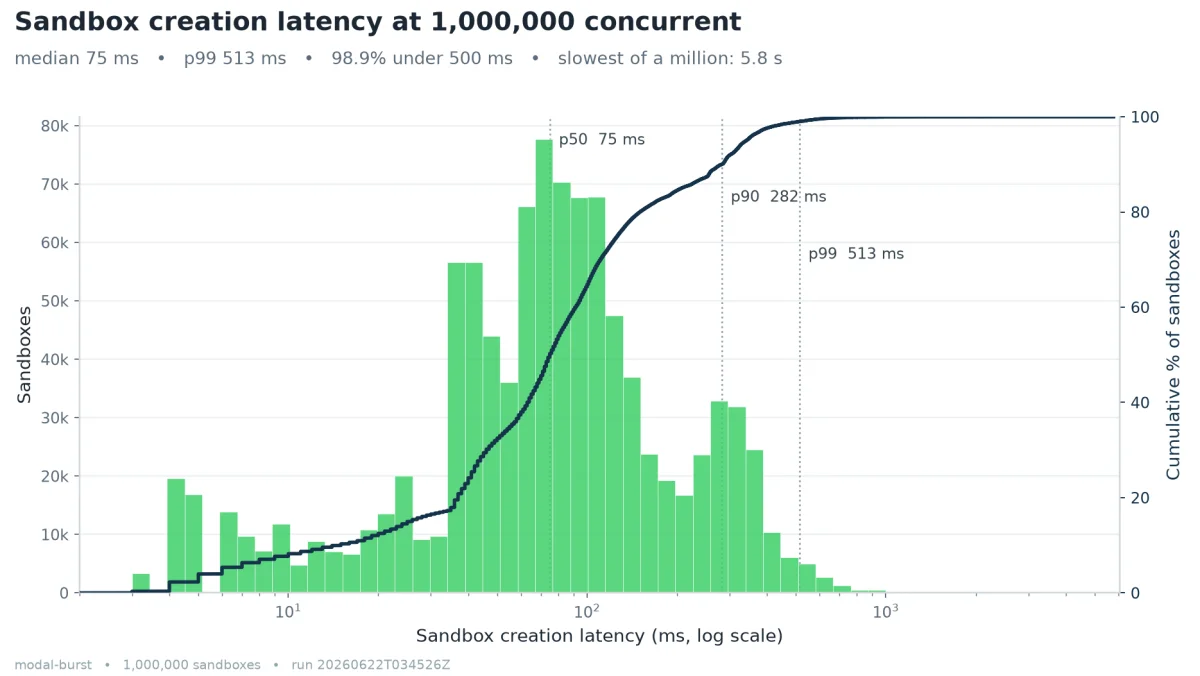
The time from when a user initiates a sandbox creation request to when the sandbox is running user code remains less than half a second at the median, providing a marked improvement over our prior system. Even scheduling times have dramatically shortened to mere milliseconds. Although the long tail for latency could be improved, we attribute it primarily to kernel contention when numerous sandboxes initiate simultaneously on given worker nodes, an area we will continue to refine.
Next Steps and Future Prospects
We are excited about the future possibilities this new system continues to unlock and are already in the beta phase of transitioning it into full operational status across all sandbox scheduling at Modal. Interested users can easily opt in by making minimal adjustments to their codebase.
As we look ahead, we remain committed to further optimizing performance and scalability while aligning our capabilities with the evolving needs of our customers across diverse applications.
Acknowledgments
This project would not have materialized without the invaluable efforts of our team members who dedicated themselves to this initiative. Contributions came from Colin Weld, Daniel Shaar, Walter Tang, Gleb Posobin, Connor Adams, Akshay Balwally, Tom Wildenhain, Scott Hao, Taylor Baldwin, and others whose hard work was essential in realizing this scalable solution.


