Speculative Decoding: Achieving Superior Inference Latencies with Advanced Techniques
- Gate
- Machine Learning
- Departs
- Crew
- Robert Smith
- Passengers
- 497
Modal’s new speculative decoding approach enhances inference speed, beating proprietary systems by over 60ms, showcasing the power of optimized AI inference.
This week marked an important milestone with the introduction of Modal's Auto Endpoints, a deployment solution designed to leverage their infrastructure for achieving leading-edge inference performance with minimal configuration. The focus is on enhancing model inference latencies without sacrificing developer control over their code.
To reach these high performance levels, a combination of factors—GPU capabilities, an efficient inference engine, infrastructure deployments, and clever optimization strategies—plays a critical role. Among these, speculative decoding stands out as a particularly effective optimization method.
The Low Latency Playbook
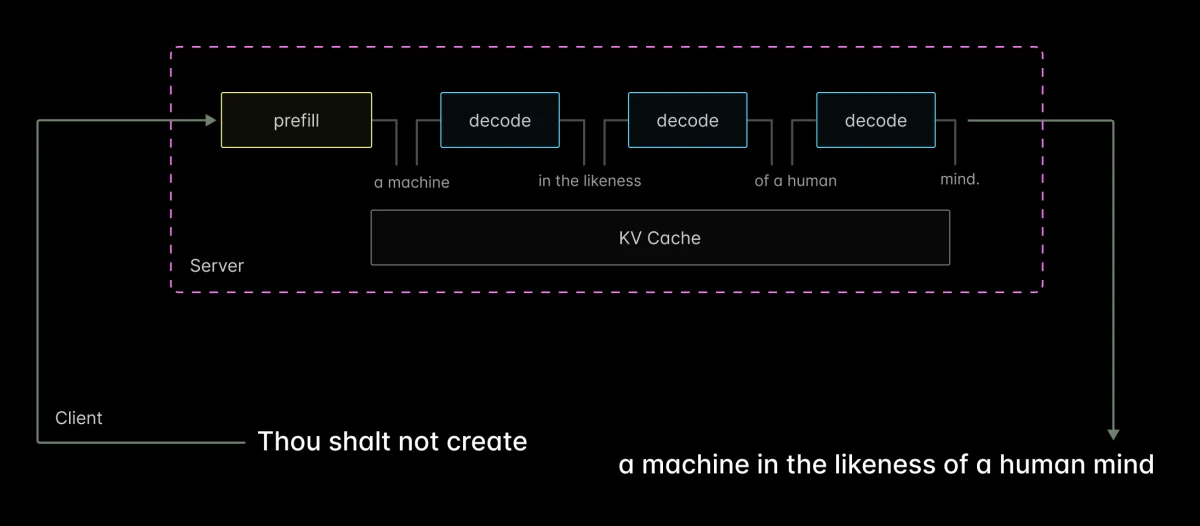
In the context of transformer inference, the operational flow resembles a request-response model where the client sends an input to the inference server. The server handles token processing in two main phases: prefill and decoding. During this process, four main sources of latency can be identified:
- Client-server communication latency
- Communication latency associated with the system architecture before and between processing stages
- Prefill latency when loading input tokens
- Decode latency during computation
The decode phase typically contributes the most significant latency. Each step within this phase requires a full forward pass through the model, necessitating weight loading from GPU memory to processing cores (SM SRAM). Thus, optimizing this portion of the process is vital for reducing overall latency.
To tackle these latency sources, several strategic optimization techniques emerge:
- Position servers to minimize distance to clients and reduce routing overhead.
- Employ an inference engine with minimal host overhead.
- Utilize high-performance GPU kernels specifically optimized for contemporary hardware.
- Implement speculative decoding, utilizing robust models for efficiency.
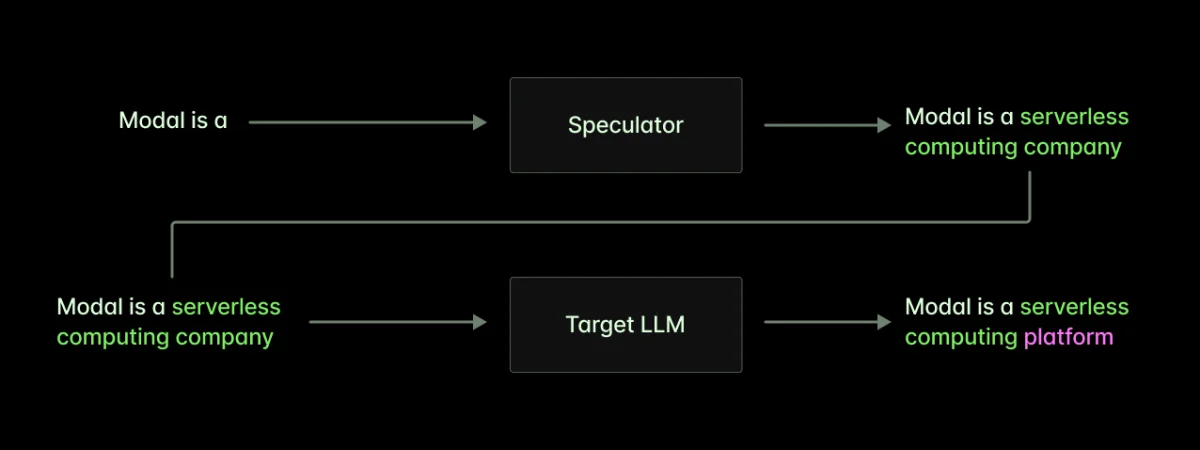
Speculative decoding significantly minimizes decoding latency by enhancing parallel processing capabilities. While traditional decoding operates sequentially—iterating through one token at a time—speculative decoding can process multiple tokens concurrently. This method mirrors techniques like speculative execution in computer processors, allowing for a more efficient workload distribution and effective hardware utilization.
Why Speculation is Effective
During speculative decoding, the model utilizes "guessed" or "speculated" tokens generated by a separate speculator model. While some speculative attempts may lead to wasted computational resources, the benefits often outweigh the overhead. In scenarios with small batch sizes, traditional decoding may not optimize GPU performance fully. Speculation can thus allow for more efficient use of the computational resources available.
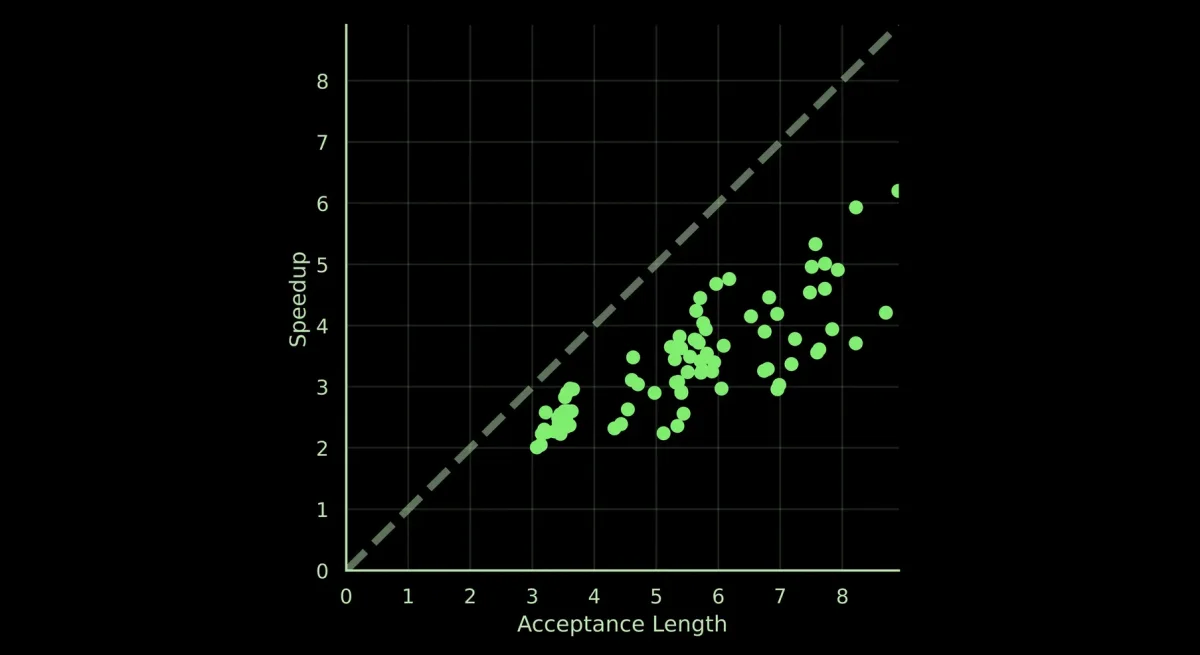
Research showcases impactful results from implementing speculative decoding, evidenced through performance improvements that scale linearly with the average number of accepted tokens. Following success in this vein, a detailed examination of acceptance length reveals its significance in bolstering speculative decoding effects.
Case Study: Decagon Agent Operating Procedures
Decagon, a platform dedicated to developing AI agents, faces unique challenges, especially regarding voice communication. Ensuring user interactions feel natural requires fast responses across various channels. To address these pain points, the Decagon team relies on their AI systems to convert input from voice signals into actionable outputs swiftly and accurately.
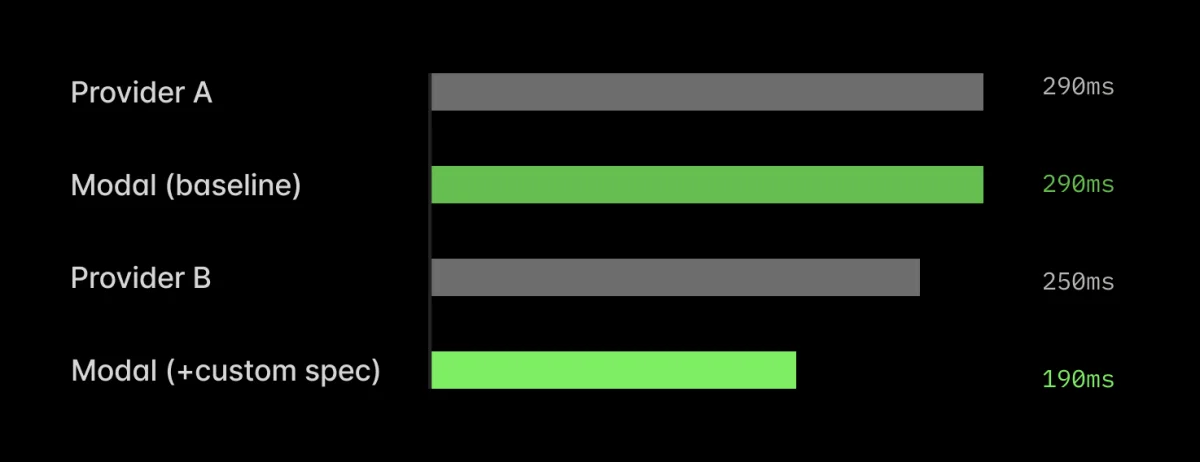
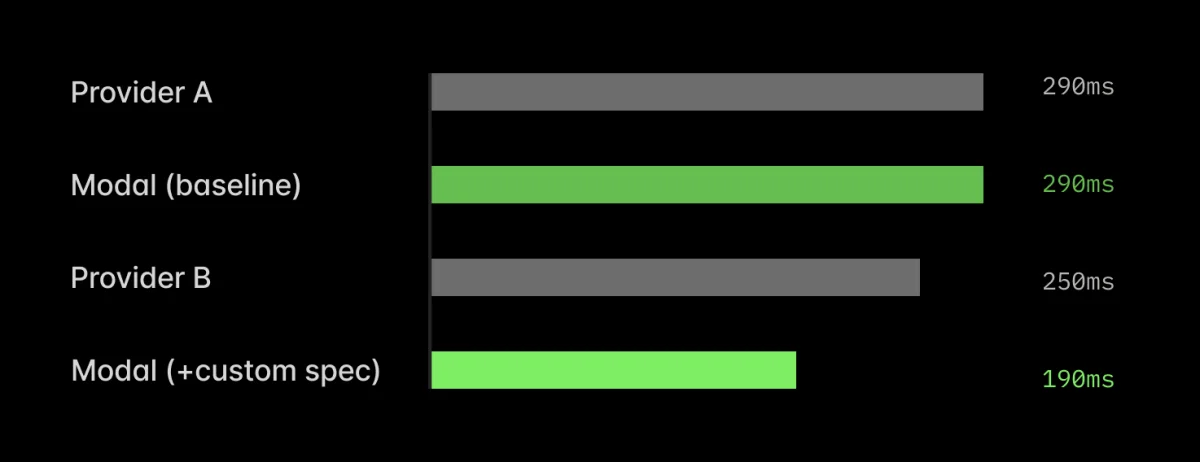
The collaborations with Decagon primarily involved optimizing their inference processes. Starting with a baseline performance of approximately 290ms for their operations, significant improvements allowed reductions of around 100ms. This brought Decagon’s ability to surpass proprietary inference latency benchmarks by over 60ms, resulting in enhanced operational efficiency.
Applying the Low Latency Playbook
Reducing Latency Across the Board
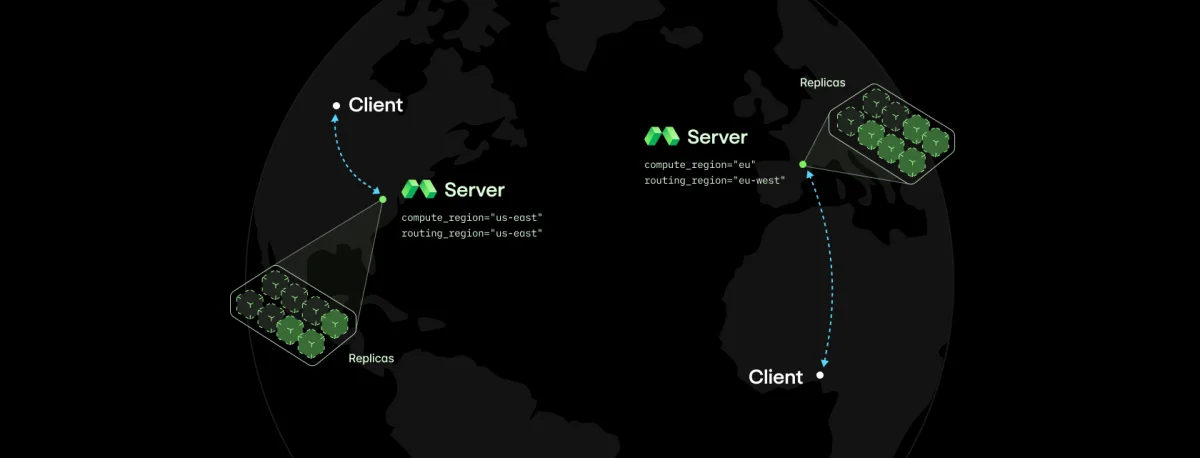
By deploying Modal's dynamic global compute fleet, they ensured that GPU resources are optimally located in close proximity to the client's environment. This infrastructure significantly curtails delays due to communication latency. During the processing of input tokens, high-performance kernels ensure execution speed, while lightweight regional proxies maintain minimal overhead in the routing of service requests.
In addition to reducing communication latency, prefill latency is improved through harnessing efficiently implemented GPU kernels for critical operations. These kernels form the backbone of effective performance enhancements.
The Big Win: Speculative Decoding and Training Optimization
Despite achieving initial reductions in latency, further enhancement was contingent on implementing a custom speculator model tailored to the specific needs of Decagon. This approach utilizes an existing understanding from pre-trained models and enhances them through mid-training—a process that refines models for targeted tasks rather than starting anew.
These custom speculator models, designed to focus on system requirements, significantly boost efficiency. They leverage cutting-edge methods, capitalizing on shared model activations to mitigate redundant calculations and synchronize workloads effectively.
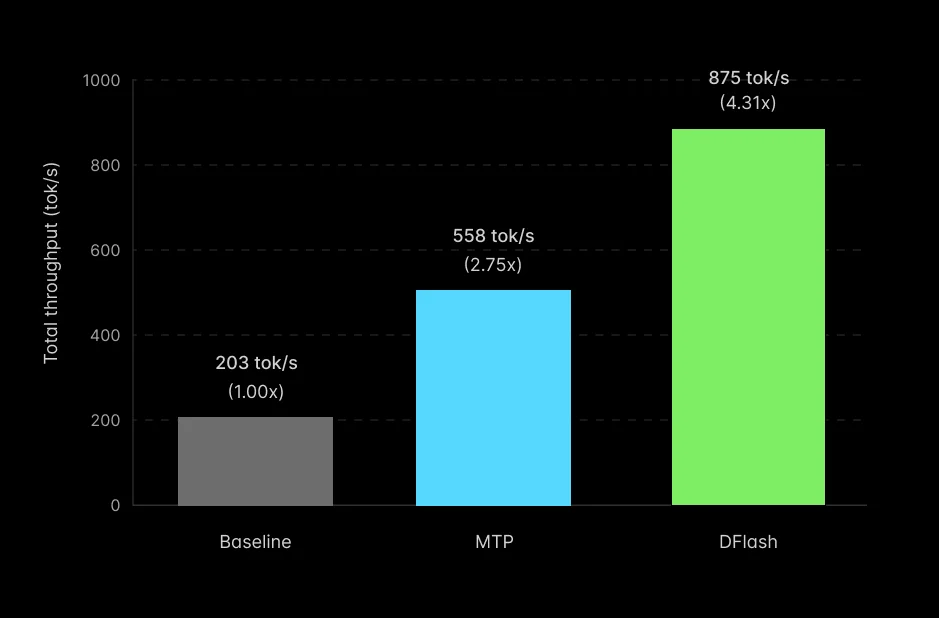
By integrating high-performance speculative decoding techniques into their infrastructure—formulated to manage layers of computational complexity—the team was able to achieve a further 100ms reduction in latency, enhancing overall performance while drastically improving throughput.
Outcomes and Future Directions
The journey with Decagon has not only resulted in performance improvements but also empowered their team with self-service deployment capabilities on Modal’s platform, thereby enhancing developer productivity. As the system expands capabilities, the savings in latency serve as valuable assets, affording opportunities for additional system enhancements or cost reductions.
Looking ahead, Modal anticipates automating speculator training, enabling continuous improvement driven by data accumulation and user interaction dynamics. This vision aims for a feature encapsulating autospec technology for ongoing optimization, enhancing inference systems’ adaptability and performance.
The contrasting dynamics of speculation require careful monitoring, particularly concerning synthetic data and performance assessments to mitigate risks of overfitting to non-production scenarios. These advancements confront ongoing challenges in infrastructure and model training. Yet the integration of synthetic datasets is proving invaluable for further refinement.
As the inference processing landscape continues to evolve, ensuring the static nature of certain models remains resilient against external biases will be paramount. Maintaining a balance between innovation and realistic application demands will define the next phase of advancements in AI model optimization.
For teams seeking to improve their inference systems, leveraging Modal’s platform and insights into speculative decoding can serve as a pathway to optimizing performance while maintaining control over infrastructure and operational costs.


