Mistral 3: Accelerating Model Deployment with GPU Snapshotting on Modal
- Gate
- Machine Learning
- Departs
- Crew
- Joseph Davis
- Passengers
- 884
Mistral 3 introduces a suite of multimodal models with GPU snapshotting capabilities that optimize cold start times, enhancing deployment efficiency.
Mistral has debuted Mistral 3, a series of open models designed for high performance and customization. These models are particularly beneficial for developers looking to implement advanced AI solutions with minimal overhead. Available on Modal, Mistral 3 enables instant deployment and efficient scaling without the burdens of managing underlying infrastructure. This integration is vital for organizations aiming to streamline their machine learning workflows. The challenge for many developers is finding a way to deploy AI solutions quickly while also maintaining quality. Mistral 3 aims to address this need, balancing performance with ease of use.
Understanding Mistral 3
Mistral 3 represents the latest advances from the company, boasting a versatile array of multimodal models with multilingual capabilities. The family features different versions, including sizes of 3 billion (3B), 8 billion (8B), and 14 billion (14B) parameters, enhancing adaptability based on various use cases. Each version of Mistral 3 is tailored for different scenarios. For instance, smaller models like the 3B version might suit developers working with less complex applications or those needing rapid iterations, while the larger models are designed for heavy lifting in data-intensive environments.
This article will specifically address the 3B version of Mistral 3, known as Ministral 3, which operates exceptionally well within Modal’s serverless environment. When it comes to benchmarking, Ministral 3 stands competitively against models like Qwen 3-VL, offering a favorable balance between computational efficiency and cognitive performance—a significant consideration for businesses optimizing AI applications. The current marketplace is littered with various AI solutions, so standing out requires models that not only perform well but can also integrate easily into existing workflows.
Quickstart Deployment
For developers eager to get started, Modal offers streamlined instructions. By following this sample code in the documentation, practitioners can deploy the 3B model efficiently using the vLLM framework. This simplicity in deployment cannot be understated, as it encourages experimentation and rapid development cycles, crucial elements in tech environments that demand agility.
To initiate the process, users should install Modal, clone the example repository, and run the provided example script. It’s a straightforward process:
pip install modal
modal setup

git clone https://github.com/modal-labs/modal-examples
cd modal-examples
modal run 06_gpu_and_ml/llm-serving/ministral3_inference.py
Configuration details are available in the example text under the modal deploy section, aiding in a smooth setup experience. Such clear guidance minimizes the barrier to entry, allowing developers of varying skill levels to adopt these advanced models more readily.
Underlying Mechanisms
This deployment takes advantage of several notable features in Modal:
- Serverless GPU capabilities automatically adjust based on request volume, enhancing user experience significantly.
- Distributed volumes allow for cached model weights and compiled artifacts, ensuring quick access during inference, which is often a bottleneck in model deployment.
- Python-defined infrastructure maintains compatibility between the application code and environmental needs, simplifying the developers' efforts in aligning their applications with the required infrastructure.
Together, these features minimize the burden of acquiring GPU resources and configuring complex settings, allowing developers to focus on refining their applications with Mistral 3 instead of wrestling with the setup. This is more significant than it looks. The friction often found in deploying models can stifle innovation, which the Modal infrastructure seeks to eliminate.
Reducing Cold Start Times
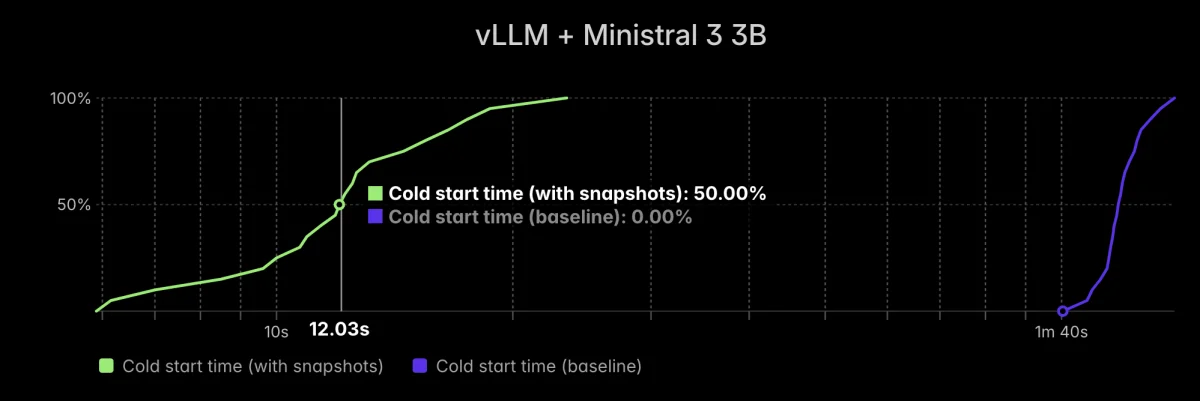
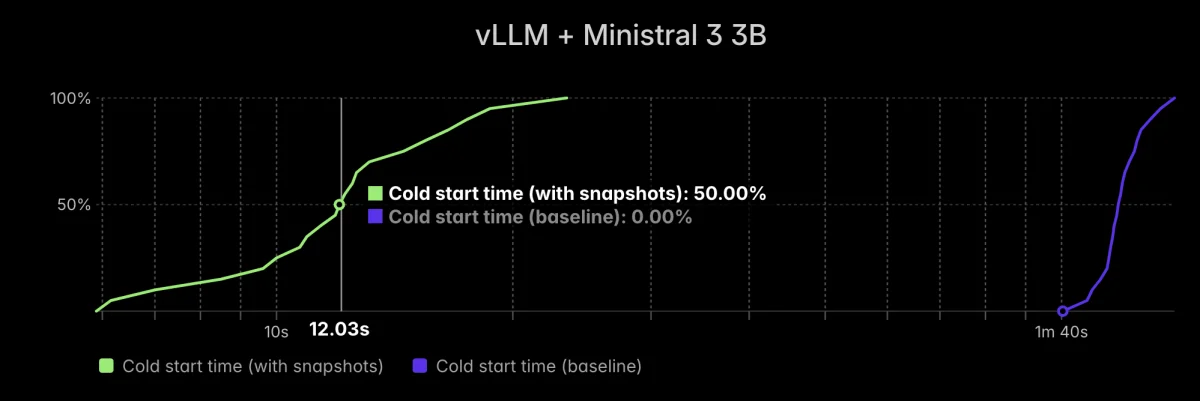
A significant advancement in the Modal platform is its newly introduced GPU snapshotting feature, which aims to optimize response times for applications requiring extensive initialization, like spinning up vLLM servers. Testing conducted on the 3B version of Ministral 3 showcased a remarkable decrease in median cold start time, from around 118 seconds to about 12 seconds—an almost 10x improvement. This kind of efficiency is not just a number on a ledger; it translates directly to user satisfaction and operational cost savings.
This reduction is critical for companies looking to deploy AI models that need to react promptly to user interactions, ultimately providing a more satisfying experience while ensuring cost-effectiveness. If you're working in this space, you know that delay in response can significantly impact user engagement and retention rates—something every business is keen to maximize.
Utilizing Snapshotting
To take advantage of the snapshotting feature, users must enable Sleep Mode on their vLLM servers and configure experimental_options={"enable_gpu_snapshot": True} within their Modal applications. When the server initially completes its setup, it transitions to a sleep state, shifting most data from GPU to CPU memory in a process that supports the snapshotting. Subsequent server activations then utilize this snapshot for much quicker initialization. (And this is the part most people overlook: the efficiency gained here isn't just technical; it greatly influences the overall user experience.)
Developers interested in experimenting with this setup can find the example code here. By actively engaging with these resources, developers can unlock the full potential of the features laid out by Modal.
Implications for the Future
The introduction of Mistral 3 signifies a step toward more efficient AI deployment strategies, especially with features like GPU snapshotting significantly reducing cold start times. As the demand for responsive AI applications grows, solutions like Ministral 3 appear to hold promise for organizations wanting to deliver intelligent, rapid responses aligned with user expectations. Such technologies are pivotal as businesses increasingly explore applications of AI across various sectors—whether it's customer service chatbots requiring immediate interactions or real-time data analysis tools.
However, the emergence of these capabilities raises questions about how effectively will organizations adapt. Investing in training staff to leverage these new tools is necessary, as is careful consideration of the ethical implications surrounding AI. In a rapidly advancing technological environment, keeping pace isn't just about adopting new models but also understanding their impacts on society and the workforce.
The numbers here may be compelling, but what matters significantly is the real-world application and the agility to respond to users. That's where the true value lies for those navigating the complexities of AI integration.


