Efficient Voice AI Chatbot Development Using Modal and Pipecat Framework
- Gate
- Machine Learning
- Departs
- Crew
- Ben Shababo
- Passengers
- 546
This article details the development of a low-latency voice AI chatbot using Modal and Pipecat, focusing on architectural strategies and model choices.
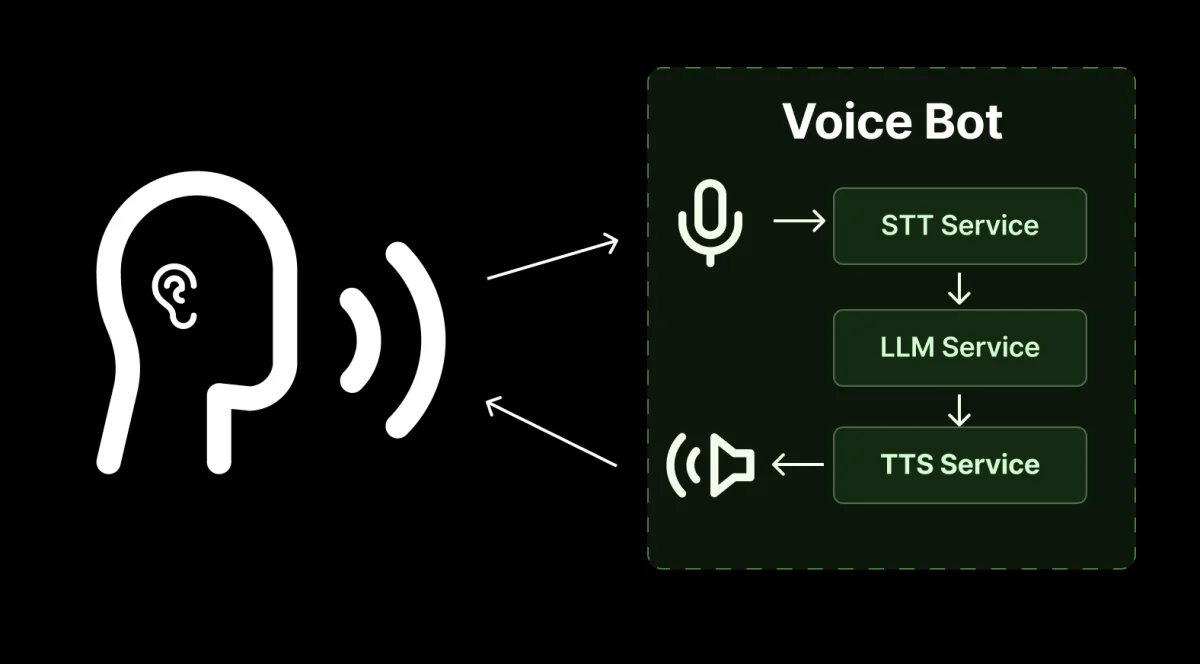
Building a voice AI chatbot capable of maintaining natural conversations requires significantly streamlined processes. Our approach leverages Modal, open-weight models, and the Pipecat framework to achieve low-latency interactions. In this article, we’ll outline the architecture, techniques employed, and resulting performance metrics, facilitating a deeper understanding of real-time applications in this domain.
Architectural Overview of Conversational Voice AI
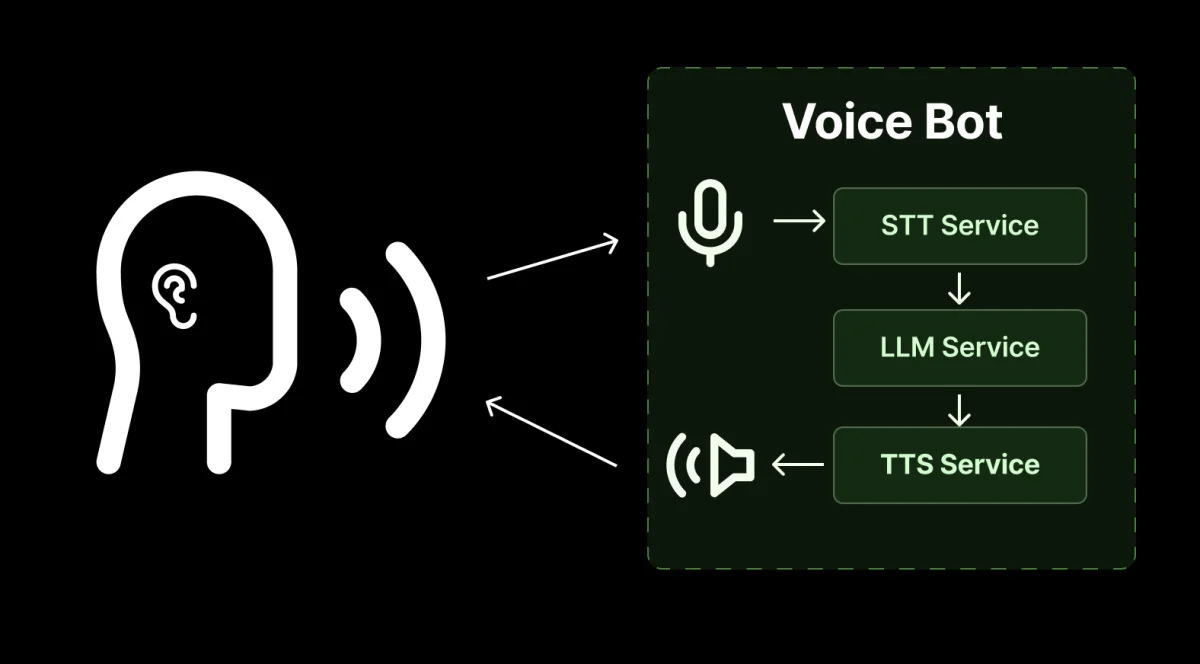
A conversational AI agent mimics human dialogue management, encompassing three primary functions:
- Speech-to-Text (STT): This involves converting spoken language into a text format.
- Language Model (LLM): The transcribed text serves as input for an LLM that generates relevant responses.
- Text-to-Speech (TTS): Finally, the generated response is transformed into audible speech.
Benefits of Using Voice AI Frameworks
In constructing voice AI systems, independent services should be harmonized through a conversational AI framework. The advantages of such frameworks include:
- Modularity: Developers can easily interchange models used for STT, LLM, and TTS from a diverse range of open-source and proprietary options.
- Conversational Flow Management: Effective frameworks manage multi-turn conversations, allowing for human interruptions and maintaining flow through voice-activity detection (VAD).
- State Management: Many AI services operate statelessly; however, a conversation framework provides the necessary stateful processes to manage conversation context efficiently.
- Networking Simplification: Frameworks abstract the complexity of establishing WebRTC or WebSocket connections, facilitating smoother interactions.
- Front-end Implementation: Most frameworks offer browser-based interfaces, catering to various levels of interaction complexity.
Utilizing Pipecat
The open-source framework we chose is Pipecat, developed by Daily, which streamlines the integration of audio, text, and video frames for real-time interaction. Pipecat's architecture includes various processors for both real-time local data and external AI service requests.
Key features of Pipecat include:
- SmallWebRTCTransport: This peer-to-peer transport provides end-to-end encryption and low latency, tailored for direct conversations.
- Custom Service Integration: Pipecat allows for easy inclusion of remote services via the
AIServiceimplementation, facilitating the connection to STT or TTS services deployed on Modal. - Advanced VAD and Turn Detection: Integrating Silero’s VAD and Pipecat's SmartTurn enhances conversational dynamics through accurate turn detection.
- Voice-UI-Kit: A comprehensive suite of React components simplifies front-end development for voice applications.
The Synergy of Modal and Pipecat
Modal provides an ergonomic SDK that enables the execution of Python code on cloud-based GPUs or CPUs. A significant feature is the independent autoscaling of functions according to their computational requirements. This allows us to assign heavy computations to GPU services while maintaining a lighter, CPU-only process for the bot itself.
This architectural decision is crucial for managing costs and performance efficiently, especially with VAD and SmartTurn, which allow our bot to run on CPUs while offloading heavier tasks to GPUs as needed.
Achieving Minimal Voice-to-Voice Latency
The core metric for evaluating conversational AI performance is voice-to-voice latency. This parameter gauges the time taken from the moment a user ceases speaking to when the bot's response is audible. Natural conversations can sustain latencies as low as 100 milliseconds; however, typical voice AI apps aim for a latency of approximately one second.
Developing a Voice Assistant for Modal Documentation
Our goal was to create a voice assistant capable of assisting users with questions about Python applications developed using Modal. We augmented our pipeline with a Retrieval-Augmented Generation (RAG) step, querying Modal’s documentation to provide contextual responses.
The main steps in our finalized pipeline included:
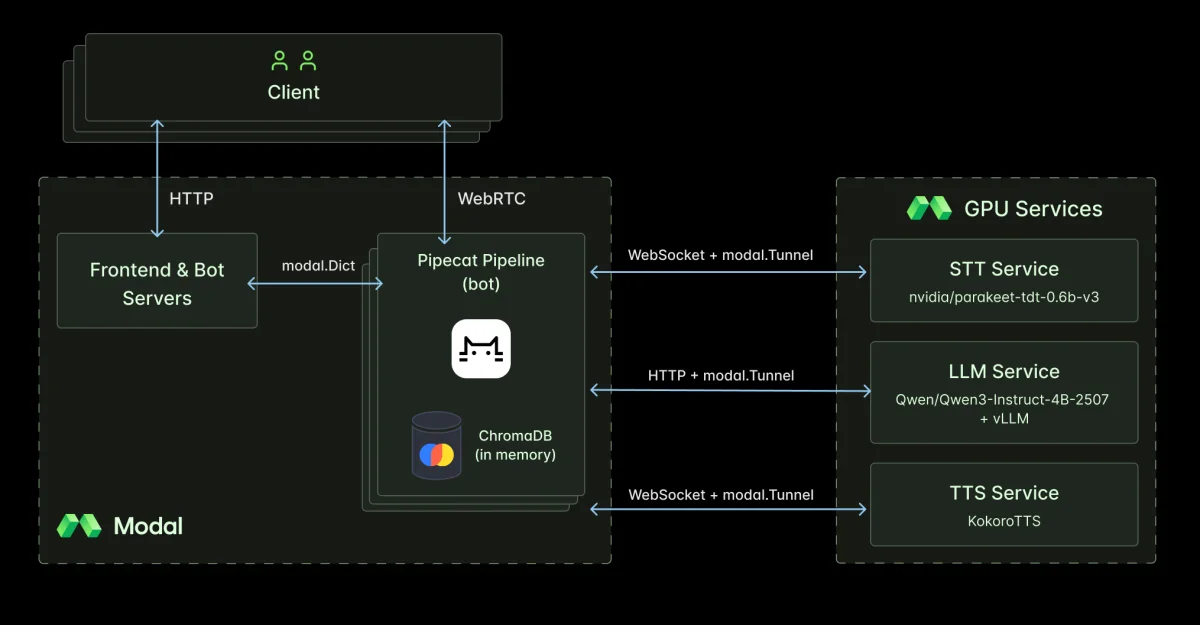
- Capturing audio data via WebRTC from the user.
- Transcribing the captured audio.
- Querying Modal’s documentation using the transcription.
- Compiling results with conversation history into a prompt.
- Generating structured response outputs from the LLM.
- Creating audio data from the spoken response.
- Transmitting audio and data back to the client using WebRTC.
Active Models and Libraries
The efficiency of open-weight models continues to evolve, making the selection of optimal models essential for application performance. Our implementation involves several models, each hosted as independent Modal services.
STT: Parakeet-tdt-v3
We selected NVIDIA’s Parakeet-tdt-v3, which exhibits superior performance in terms of accuracy and final transcription times, fitting seamlessly into the Pipecat workflow. This model excels in processing local audio segments retrieved through Pipecat's VAD system.
LLM: Qwen3-4B-Instruct-2507 and vLLM
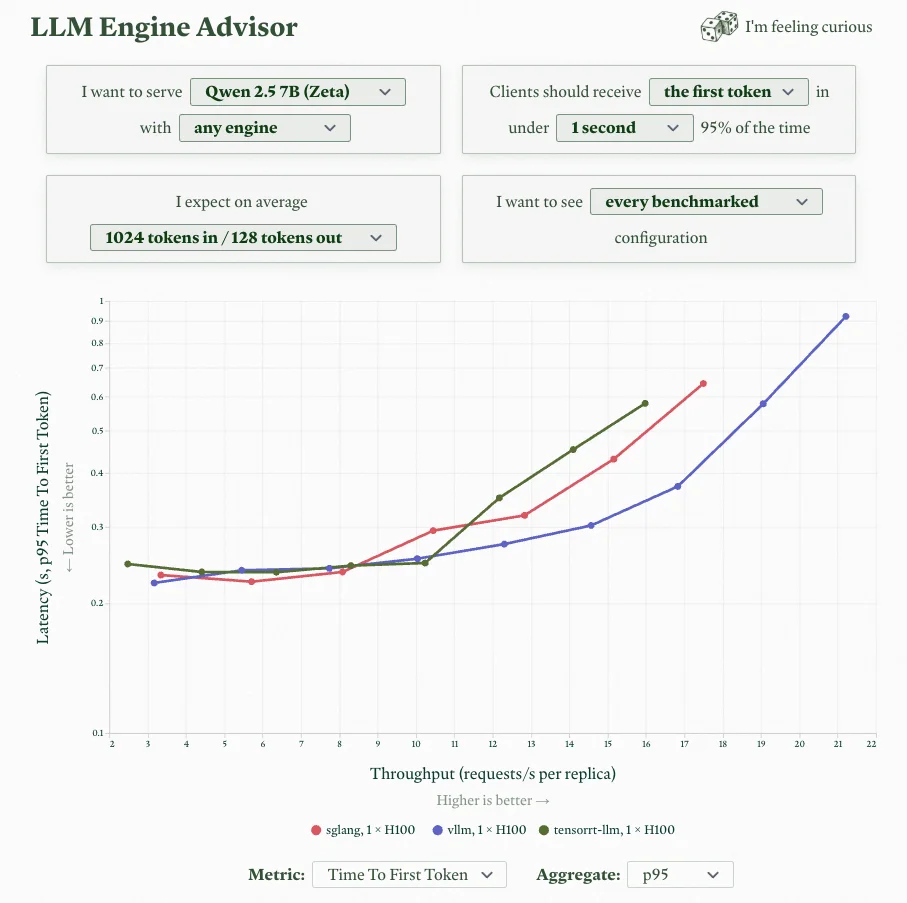
For LLM tasks, we utilized Qwen3-4B-Instruct-2507, a compact and efficient model from Hugging Face that produces quality responses. To optimize inference, we adopted vLLM, which facilitates minimal time-to-first-token output through extensive configuration and fine-tuning of the engine.
TTS: KokoroTTS
The TTS component uses Kokoro, a lightweight model that ensures swift output along with phonetic accuracy for specialized terminology, thus reinforcing the correctness of responses delivered audiophonically.
Integrating RAG Techniques with ChromaDB
For retrieval-augmented generation tasks, we employed ChromaDB, coupled with all-minilm-l6-v2, to achieve efficient query embeddings and rapid search capabilities.
Minimizing Network Latency
Passing data over the Internet introduces unavoidable latencies. To mitigate this challenge, we utilized WebRTC for direct communication between the client and the bot, as well as implemented Modal Tunnels to streamline connections with inference services.
Establishing Efficient Networking
To enhance direct communication, we use SmallWebRTC for establishing peer-to-peer connections. Modal’s tunnels allow for effective autoscaling while maintaining low-latency links to the inference services.
Performance Testing and Measurements
To assess voice-to-voice latency, we measured the time between speech input and bot response in controlled environments. We also tested configurations across various geographical data centers to identify optimal deployment scenarios.
Utilizing Pyannote for Speaker Diarization
We employed Pyannote to automate the analysis of recorded conversation segments, affording us insights into latency metrics across different conversational turns.
Data Analysis via Modal Notebooks
Using Modal Notebooks, we analyzed and visualized latency results from the audio data. The outcomes indicated that optimal geographic alignment for both user and bot locations contributed significantly to latency reduction.
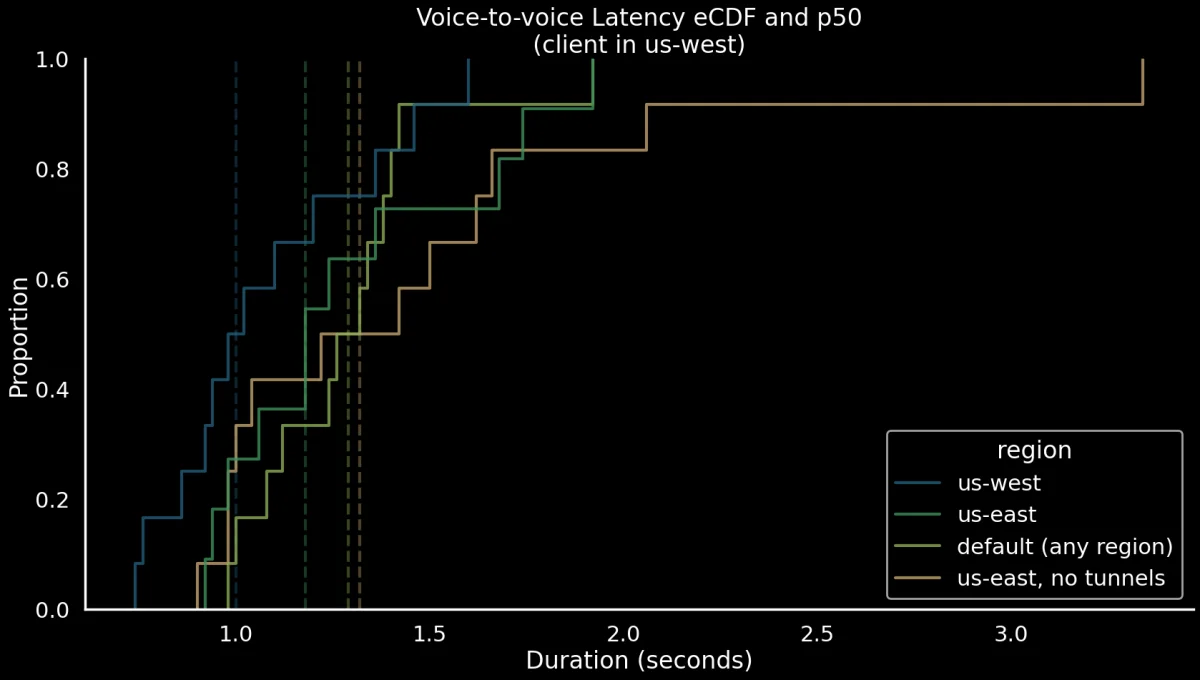
Key findings from our tests revealed:
- Latency can reach as low as one second when operations are confined to geographically proximate data centers.
- Network latency varies based on the physical distances between client devices, bots, and inference services.
- Deploying bots in regions close to Modal's input plane aids in achieving desirable latency performances.
Deploying Your Own Voice AI Using Modal
The implementation code for this conversational voice AI can be found in the GitHub repository, enabling developers to reproduce or expand upon our findings. For further assistance, join our Community Slack.
Bonus Feature: Animating Modal’s Mascots
As an engaging addition, we implemented animated avatars of Modal’s mascots, Moe and Dal, showcasing Pipecat’s capability for managing multiple voices concurrently in a parallel pipeline setup.


