Decagon Enhances Real-Time Voice AI with Modal's Infrastructure Innovations
- Gate
- Machine Learning
- Departs
- Crew
- Richard Gong
- Passengers
- 522
Decagon improves its voice AI capabilities by reducing latency by 65% and enhancing accuracy through advanced model training and optimization with Modal.
This post was written in conjunction with the Decagon team.
Decagon has launched a sophisticated platform, allowing teams to create, optimize, and scale AI-powered voice agents that offer high-quality customer interactions. With the introduction of Decagon Voice, organizations can craft intelligent voice assistants that align closely with their unique brand identities and operational requirements.
The voice domain is notoriously challenging within AI, necessitating a combination of sub-second response times, natural conversational flow, and overall quality of interaction. Achieving these goals in a production setting and at scale has driven the need for substantial advancements in both the accuracy of the models and their inference performance.
Collaborative Model Enhancement
Decagon has teamed up with Modal to tackle two critical objectives: enhancing model accuracy and enabling real-time inference. Together, they focused on creating models that not only perform well but can do so swiftly and efficiently without sacrificing quality.
Boosting Model Accuracy
To establish a fast voice interaction system, Decagon needed to implement smaller models while ensuring accuracy remained high. Initial experiments with condensed models revealed failings in generalization—models struggled to perform adequately across diverse domains. To address this, a multi-faceted approach was taken involving advanced data utilization, supervised fine-tuning (SFT), and reinforcement learning (RL).
On the data front, the team prioritized a rich and varied dataset that spanned numerous sectors and included varying conversational tones and intents, designed specifically to mitigate overfitting and enhance adaptability across different scenarios.
In terms of SFT, the methodology included curriculum learning to guide the training process and mixed-objective fine-tuning to ensure the models maintained their ability to process instructions effectively.
A significant milestone was reached when RL techniques were integrated to fine-tune model behaviors. This combination yielded a smaller model that consistently outperformed larger, leading-edge models typically utilized in the field.
Modal's powerful training framework facilitated this process by allowing engineers to run high-concurrency GPU sweeps and monitor their fine-tuning efforts without delving into cluster management. This efficiency accelerated Decagon’s model training and iteration, resulting in improved generalization across varied customer interactions.
Real-Time Performance Achievements
For voice interactions to feel authentic, it's imperative that responses are delivered in under a second. Achieving this required more than simply enhancing model accuracy; Decagon also needed an optimized inference pipeline. Modal's team tackled this challenge by creating tailored draft models and refining the serving engine.
Custom Draft Models and Inference Optimization
In a bid to enhance inference speed, Decagon implemented speculative decoding—a method that links a primary model with a smaller draft version. The draft model, or "speculator," quickly proposes potential responses, which the target model validates. This allows the system to bypass lengthy generation times when the proposals align well.
Initial evaluations using an EAGLE3 draft model demonstrated limited length acceptance when integrated with Decagon’s models. To improve performance, Modal's engineers modified SpecForge to create a custom training pipeline for EAGLE3 draft models, enhancing them first through broad conversational data pre-training and subsequently fine-tuning with Decagon's specific datasets.
The upgraded draft model reported an impressive 38% higher acceptance length than existing open-source models, significantly boosting inference efficiency.
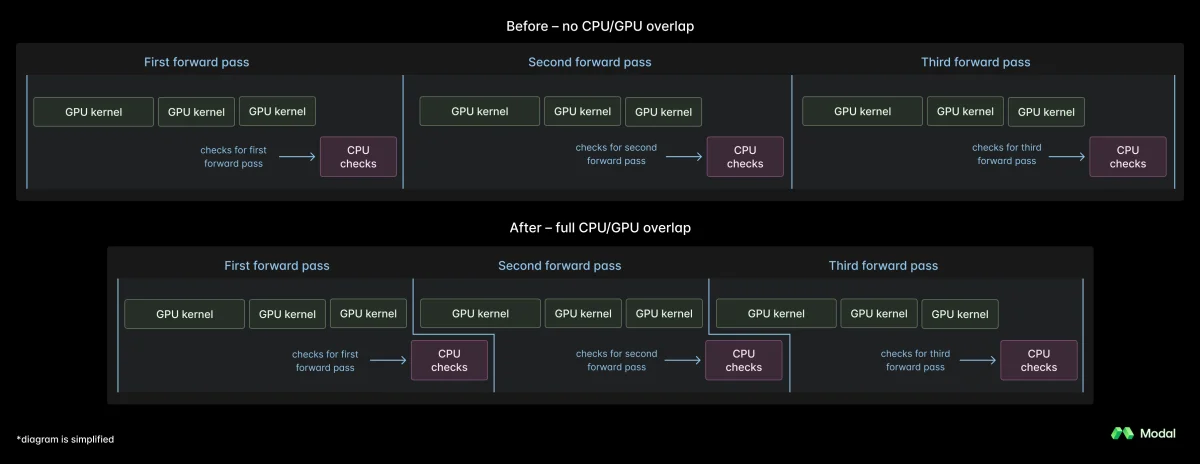
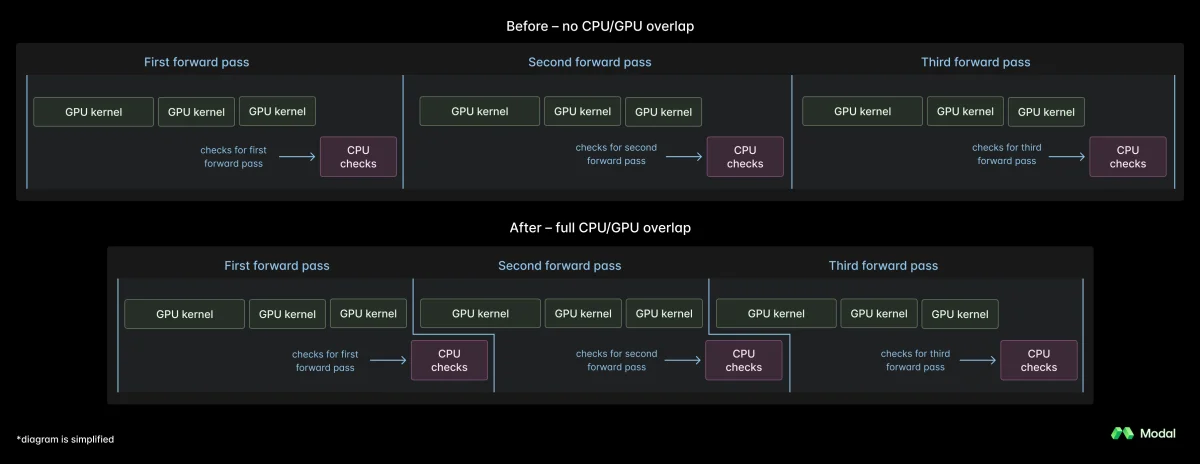
Further gains at runtime were unlocked through a detailed examination of SGLang—the open-source engine serving the models. The analysis revealed two critical performance bottlenecks: CPU stalls that limited GPU utilization and the absence of an asynchronous scheduler for faster speculative decoding.
To bypass these hurdles, Modal's team implemented a new asynchronous scheduling system for speculative decoding, eradicating host-side inefficiencies and permitting parallel GPU computation. Consequently, this iteration completely eliminated idle time on H200 GPUs and resulted in a throughput increase of up to 12%, with updates being integrated back into SGLang.
Future Directions for Decagon and Modal
Building a large-scale voice AI system remains one of the most formidable challenges in AI infrastructure. The collaboration between Decagon and Modal has pushed the limits of what's achievable by merging advanced fine-tuning techniques with substantial runtime optimizations. Modal's underlying infrastructure has facilitated Decagon’s ascent toward training and deploying even more capable AI models, effectively meeting increased user demand.
As Decagon continues to innovate, the foundational systems provided by Modal are poised to support the next generation of real-time AI experiences, advancing training methodologies, reducing response times, and contributing to the ongoing evolution of conversational intelligence.


