Building High-Availability VPN Proxies for Serverless Containers with WireGuard at Modal
- Gate
- Machine Learning
- Departs
- Crew
- Eric Zhang
- Passengers
- 860
Modal's implementation of a Go-based VPN proxy, vprox, enables static IP addresses for serverless containers, ensuring reliable connections and simplified access control.

At Modal, we’ve developed a high-availability, Go-based VPN proxy called vprox. This VPN proxy utilizes WireGuard, functioning at Layer 3 (IP) of the OSI model. It allows us to funnel outbound traffic from containers dispersed worldwide through static IPv4 addresses. In the event of a single-node failure, static IPs become associated with alternate proxy nodes, ensuring that containers can reconnect almost immediately.
This article examines the intricacies of our network infrastructure, which underpins the Static IP Proxies in our offerings.
Scenario: Serverless Cloud Deployment
Imagine you're in the year 2024, selecting a serverless cloud platform. As you discover Modal, you execute pip install modal, craft a brief Python function, and deploy it with modal deploy. It’s instant; you have a cron job and an API endpoint live in the cloud in mere seconds.
Modal functions leverage compute resources across numerous regions and cloud providers, facilitating dynamic scaling and cost optimization to satisfy developers' needs. You’ve freed yourself from infrastructure concerns—those are handled by us, the infrastructure engineers.
However, you soon realize that you need to connect your serverless function to a MongoDB cloud database, which requires an IP access list. This presents a challenge.
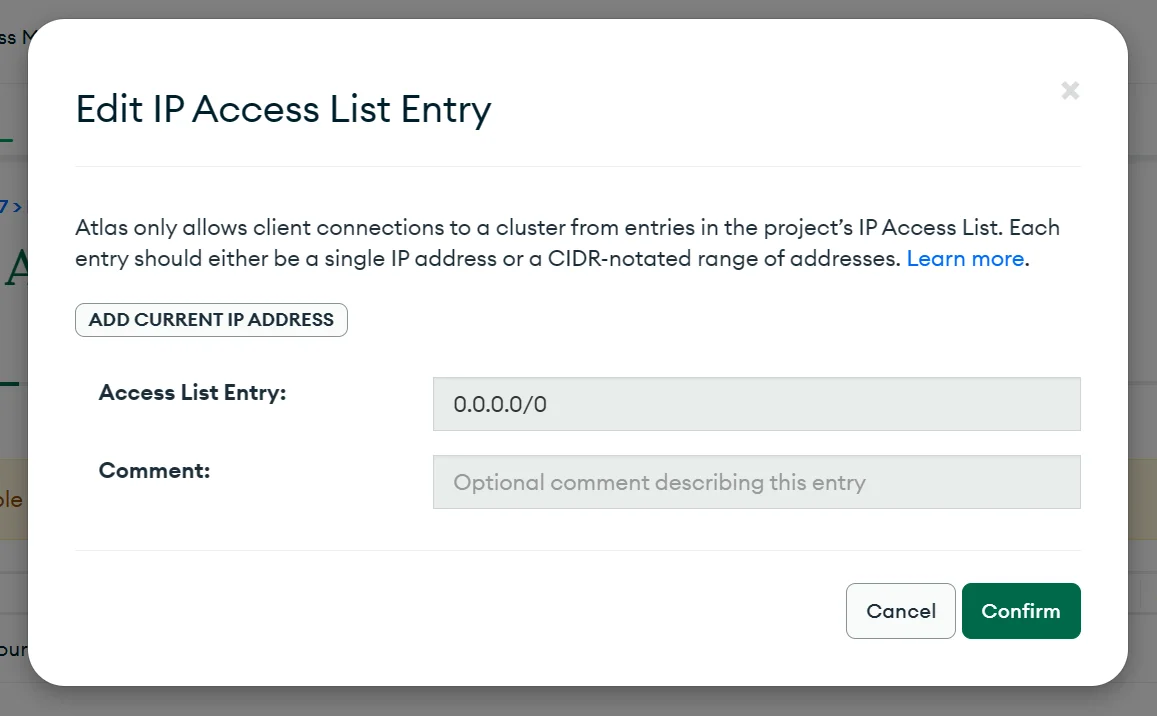
Typically, with a conventional provider, you'd deploy virtual machines (VMs), designate static IP addresses, and set those in your access list. Your application would then operate on predictable IPs, like 20.21.20.21, restricting database access to these machines. Yet, in a serverless model where workloads can run anywhere globally and scale dynamically, tracking IP addresses becomes cumbersome and impractical. Your access list could balloon to thousands of entries and become continually outdated.
Additionally, since Modal employs isolated container runtimes that share CPU and memory between workloads, encountering multiple containers with identical IPs on a host defeats the security intentions behind an access list.
Solution: Achieving Static Outbound IPs
The goal is to establish a static outbound IP address. Outbound IPs serve as identifiers for data exchanges over the Internet. When different containers communicate with a service like Google, each has a unique source IP, critical for the server to respond appropriately.

In a conventional setup, the outbound IP is tightly linked to the container itself. The challenge lies in decoupling static IPs from compute resources. The answer? Employ a proxy.
We initiated this with SOCKS5 proxies at Modal. This protocol, originating from 1996 (RFC 1928), enables traffic to route through another machine. However, using SOCKS5 directly requires application modifications, complicating integrations.
If we want containers to utilize a SOCKS5-based Modal Proxy, we define one for your workspace. Here's an illustration of how that looks in code:
import socket
import psycopg2
import socks

@app.function(
    proxy=modal.Proxy.from_name("postgres-prod"),
    secret=modal.Secret.from_name("postgres-prod-credentials"),
)
def get_user_count() -> int:
    socks.set_default_proxy(socks.SOCKS5, "localhost", 13432)
    socket.socket = socks.socksocket

    connection = psycopg2.connect(
        dbname=os.getenv("DB_NAME"),
        user=os.getenv("DB_USER"),
        password=os.getenv("DB_PASSWORD"),
        host=os.getenv("DB_HOST"),
        port=os.getenv("DB_PORT"),
    )
    cursor = connection.cursor()
    cursor.execute("SELECT COUNT(*) FROM users;")
    user_count: int = cursor.fetchone()[0]
    return user_count
Other functions can call get_user_count() seamlessly as a serverless invocation enabled by the proxy definition within that function.
@app.function(schedule=modal.Cron("2 0 * * *"))  # runs at 2 AM
def daily_schedule() -> None:
    num_users = get_user_count.remote()
    print(f"you currently have {num_users} users, posting to Slack...")
    # ...
While effective, this approach has its limitations. Overriding the standard library's socket.socket is fragile, particularly with libraries that don't rely on socket directly, such as asyncpg, datadog, aiohttp, httpx, or grpcio.
The user experience suffers as the API complexity shifts onto the developer, who must figure out how to connect their libraries with the SOCKS5 proxy. At Modal, we prioritize a developer experience where things should work intuitively. Thus, we sought a more integrated solution.
We control the entire runtime, enabling us to handle outbound Internet access more effectively. Developers should simply send a request to ifconfig.me and receive the proxy’s IP in response.
Using WireGuard to Simplify Networking
At the Internet Protocol Layer (Layer 3), all traffic appears uniform—whether navigating to Wikipedia, YouTube, or MongoDB. This means that packets traveling over the Internet lack identifiable features. To maintain a consistent source IP across numerous containers, the solution lies in routing all container traffic through a VPN. A VPN not only encrypts that traffic but also masks the source IP, achieving the desired static consistency.
WireGuard, a simplified and efficient VPN protocol, is built into the mainline Linux kernel. Establishing a WireGuard network between the proxy server and Modal workers (the machines responsible for running containers) allows for efficient traffic routing.

The setup begins with configuring an HTTPS listener on port 443 of the WireGuard server. This connection binds to the proxy node's public IP, accepting "connect" POST requests to establish WireGuard connections. The security of TLS safeguards the transition of VPN key distribution.
When the server receives a POST request containing a client’s public key, it verifies the client’s credentials, allocates an IP address within the designated subnet, and adds the client as a peer at that IP. Crucially, the server uses a looping mechanism to expunge idle peers after a few minutes of inactivity, thanks to the wgctrl library, which provides Go bindings for WireGuard’s API.
var removePeers []wgtypes.PeerConfig
var removeIps []netip.Addr

for _, peer := range device.Peers {
    var idle bool
    if peer.LastHandshakeTime.IsZero() {
        _, isNew := srv.newPeers[peer.PublicKey]
        idle = !isNew
    } else {
        idle = time.Since(peer.LastHandshakeTime) > PeerIdleTimeout
    }

    if idle {
        if len(peer.AllowedIPs) > 0 {
            ipv4 := peer.AllowedIPs[0].IP.To4()
            if ipv4 != nil {
                log.Printf("[%v] removing idle peer at %v: %v",
                    srv.BindAddr, ipv4, peer.PublicKey)
                removeIps = append(removeIps, netip.AddrFrom4([4]byte(ipv4)))
            }
        }
        removePeers = append(removePeers, wgtypes.PeerConfig{
            PublicKey: peer.PublicKey,
            Remove:    true,
        })
    }
}

if len(removePeers) > 0 {
    err := srv.WgClient.ConfigureDevice(srv.Ifname(), wgtypes.Config{Peers: removePeers})
    if err != nil {
        return err
    }
    for _, ip := range removeIps {
        srv.ipAllocator.Free(ip)
    }
}
Client-side, we ensure the WireGuard connection is regularly monitored every few seconds. The CheckConnection function manages this. If pings fail, the client presumes the connection is compromised, prompting it to reconnect to the server with a new “connect” POST request.
func (c *Client) CheckConnection(timeout time.Duration, cancelCtx context.Context) bool {
    pinger, err := probing.NewPinger(c.wgCidr.Masked().Addr().Next().String())
    if err != nil {
        log.Printf("error creating pinger: %v", err)
        return false
    }

    pinger.Timeout = timeout
    pinger.Count = 3
    pinger.Interval = 10 * time.Millisecond
    err = pinger.RunWithContext(cancelCtx)
    if err != nil {
        log.Printf("error running pinger: %v", err)
        return false
    }
    stats := pinger.Statistics()
    if stats.PacketsRecv > 0 && stats.PacketsRecv < stats.PacketsSent {
        log.Printf("warning: %v of %v packets in ping were dropped", stats.PacketsSent-stats.PacketsRecv, stats.PacketsSent)
    }
    return stats.PacketsRecv > 0
}
This capability is integral to our open-source Go library vprox, which we will further explore later.
Managing Multi-Tenant Container Traffic
The next challenge revolves around managing multi-tenant Modal workers. These workers operate using gVisor sandboxes for each function on a single host, enabling us to create a flexible priced serverless compute environment.
Here’s a brief overview of how container networking functions:
- Each worker machine executes a series of containers, with each container assigned its own network namespace.
- Within each network namespace, each container is equipped with a veth (virtual Ethernet) interface akin to a network card on a local machine.
- Veth interfaces exist in pairs; the other half pairs with a bridge device.
- When containers send outbound packets to the Internet, they traverse the veth interface and reach the bridge, which masquerades the packet's source IP before exiting the host.
Understanding the above is not crucial for general use. What matters is the masquerade. This network address translation technique ensures containers appear to have the host's public IP address when communicating externally.

This standard architecture needs adjustment to incorporate WireGuard. We need to route traffic from a designated container to its corresponding WireGuard interface while keeping interactions with other containers unaffected. This requires modifications to the Linux kernel's routing table.
However, Linux presents a challenge: the iproute2 implementation does not allow for routing table entries based on the source IP address. Instead, routing tables are organized by CIDR blocks of destination IPs. Therefore, you can route packets toward a specific destination from all containers, but not route packets originating from a specific container through a VPN.
To solve this, we wrote policy-based routing rules. 🫢
# Update routing policy to match packets from 10.11.12.13 to "table 101"
ip rule add from 10.11.12.13 lookup 101

# Add a default route for "table 101"
ip route add default dev wg1 table 101
Policy-based routing allows us to switch among multiple routing tables. Linux's routing tables are indexed from 1 to 2^31, facilitating our assignment of unique routing tables for each container requesting a proxy service. We can allocate indices to prevent duplication and update the policy database, ensuring traffic from a particular container flows through the appropriate routing table.

Implementing this was not our initial desire due to its complexity. Synchronization is critical when numerous containers boot simultaneously to decide which gets the next routing table. If a container unexpectedly shuts down early, it adds yet another kernel resource to the cleanup queue. While the dynamic policy database configuration was not our preferred option, our runtime's resilience—developed in safe Rust with thorough testing and monitoring—has mitigated many reliability concerns as advanced.
That wraps up the worker-side proxy implementation. Now, let’s focus back on the server.
Proxy Server Efficiency
Initially, we operated a separate cloud VM for each proxy server, but this approach proved cost-prohibitive and inefficient. With serverless solutions relying on shared tenancies, we restructured operations to assign multiple IPs to each proxy server. This adjustment enables one unit of shared hardware to manage many IP associations.
Every vprox server node can host multiple IPs across one or more network interfaces. For instance, utilizing AWS's latest c7gn.8xlarge instance type ($2.00 per hour), which supports up to 8 network interfaces, each interface can accommodate 30 IPv4 addresses. When fully optimized to manage 240 IPs, each ultimately costs less than $0.01 per hour while allowing individual proxies to burst up to 100 Gbps of shared bandwidth.
To minimize contention and control bandwidth among various IP proxies operating on the same server, we implement the tc traffic shaping system within Linux.
Managing IPs Across Servers
We have also developed code to query the cloud instance metadata endpoint, promptly detecting any changes to the IP configurations of the instance. If any change is identified, vprox automatically reconfigures to relocate blocks of WireGuard IPs, adjust connections, and bootstrap new WireGuard interfaces, thus allowing connections from clients at the new IP address.
This may seem excessive, but it streamlines configurations for vprox and significantly enhances server flexibility. Additionally, this implementation is inherently fault-tolerant. Reconciliation loops are vital in distributed systems, ensuring stability and operational integrity.
Since the network proxy handles every request from serverless functions, its high availability is critical. You wouldn’t want API services failing due to a single proxy instance's downtime. To combat this, we designed a global reconciliation loop that automatically creates multiple servers, reallocating IP addresses as needed when incidents arise.

Such events could occur if an instance becomes unresponsive or is scheduled for maintenance. Additionally, the vprox client is engineered to detect network partitions, regularly sending pings to ascertain connectivity. Should it identify disconnection, the client can self-recover by connecting to a new server in under 10 seconds.
Given that IP operates without reliable order, most users will likely remain oblivious to proxy disruptions. Even if an HTTP request happens precisely at that moment, it will result in a few dropped packets that the TCP layer will automatically handle and retry. Users experience no database errors—ensuring a flawless recovery process.
Understanding rp_filter
(Here, we delve into sysctl. Sysctl is a system for configuring Linux kernel attributes, similar to a global OS-level configuration file.)
While examining vprox against different Linux distributions, an inconsistency surfaced. It functioned correctly on Ubuntu 24.04, yet exhibited failures on Oracle Linux 9. Both distributions support WireGuard integration, iptables, and iproute2, which left us puzzled about the cause.
The issue traced back to the reverse path filtering feature. Specifically, the net.ipv4.conf.all.rp_filter parameter governs packet receipt on interfaces, filtering out those whose source addresses don’t align with the perceived routing path. This restriction resulted in dropped packets since we send requests to diverse public internet entities through WireGuard interfaces. Linux's kernel perceives a default interface path as more relevant, triggering the drops.
To rectify this, we needed to adjust the rp_filter setting to be more forgiving.
Interestingly, disabling the reverse path filtering variable yielded failures for vprox. It became apparent that the value needed shifting to 2, implying "loose mode" that checks incoming packets against the kernel's forwarding information base.
sysctl -w net.ipv4.conf.all.rp_filter=2While the exact mechanics remain uncertain regarding why setting the parameter to loose mode is necessary, the adjustment stabilized vprox functionality across various Linux distributions.
Utilizing vprox
For developers on Modal, access to our static IP proxies is available within the Team plan. Simply create a proxy, and you’ll receive an outbound IP without requiring SOCKS5.
import modal
import subprocess

app = modal.App()

@app.function(proxy=modal.Proxy.from_name("my-static-ip-proxy"))
def my_proxy_function():
    subprocess.run("curl ifconfig.me", shell=True)  # => "20.21.20.21"
Currently, each Proxy corresponds to a discrete static IP, but our roadmap includes developing region-specific proxies. This upgrade would enable containers to leverage IPs from the nearest geographical area to reduce latency further.
To reiterate, this article has focused on the underlying mechanics of our implementation. Our control plane, detailing how we operationalize WireGuard within the Modal serverless function environment, is open-sourced. You can explore it within the modal-labs/vprox repository on GitHub. With minimal commands, you can initiate a VPN server and an unlimited number of clients, all while enjoying full networking configurability.
A notable feature of this implementation is the automated IP discovery. On AWS, we routinely poll the instance metadata endpoint to ascertain the attached IP addresses, eliminating the need for manual updates. Just execute vprox server --cloud aws and experience the seamless integration. Although potential adaptations to other cloud providers exist, our testing has focused primarily on AWS.
We’re excited to see how you’ll leverage static IPs at Modal! This project has been a rewarding journey for many within our team. Special thanks to my colleague Luis Capelo, who implemented vprox in production, and to our intern Jeffrey Meng for executing IP discovery and client reconnections.
If you're passionate about developing resilient and secure systems at scale for the next iteration of cloud infrastructure, we're hiring at Modal.


