Modal Introduces Access to NVIDIA H100 GPUs for Enhanced Machine Learning Performance
- Gate
- Machine Learning
- Departs
- Crew
- Richard Martinez
- Passengers
- 373
Users can now access NVIDIA's H100 GPUs on Modal, promising up to 4x training and 30x inference speed improvements compared to A100s.
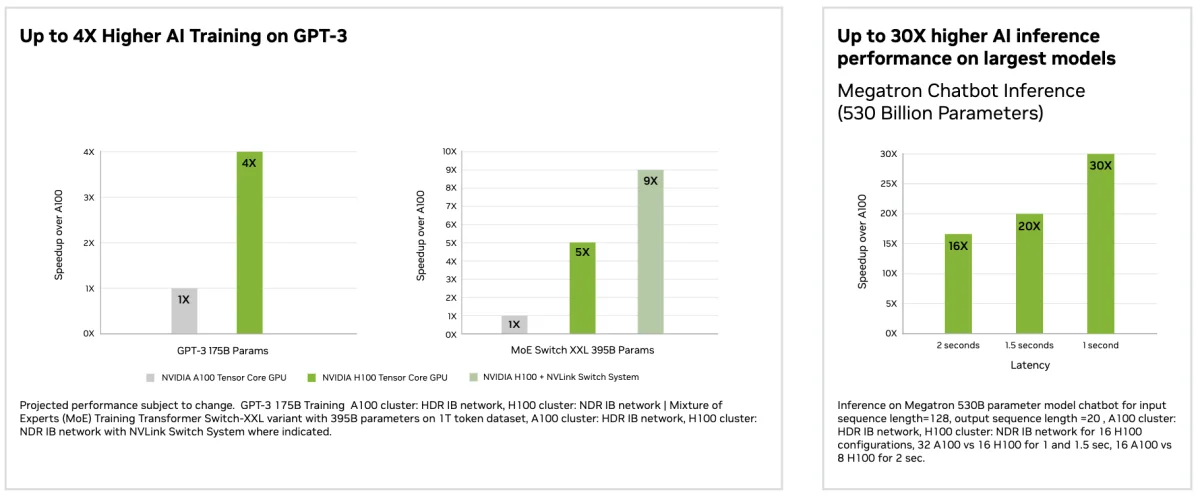
NVIDIA’s H100 GPUs are now available on Modal, providing users with unprecedented speed in machine learning tasks. Known to be the fastest accelerators presently available, the H100's capabilities markedly enhance the performance of large language models. This feature comes at a pivotal moment for developers and researchers who require significant computational power to drive their machine learning workloads. As applications in AI continue to gain traction across various sectors, the demand for faster, more efficient processing units has never been higher.
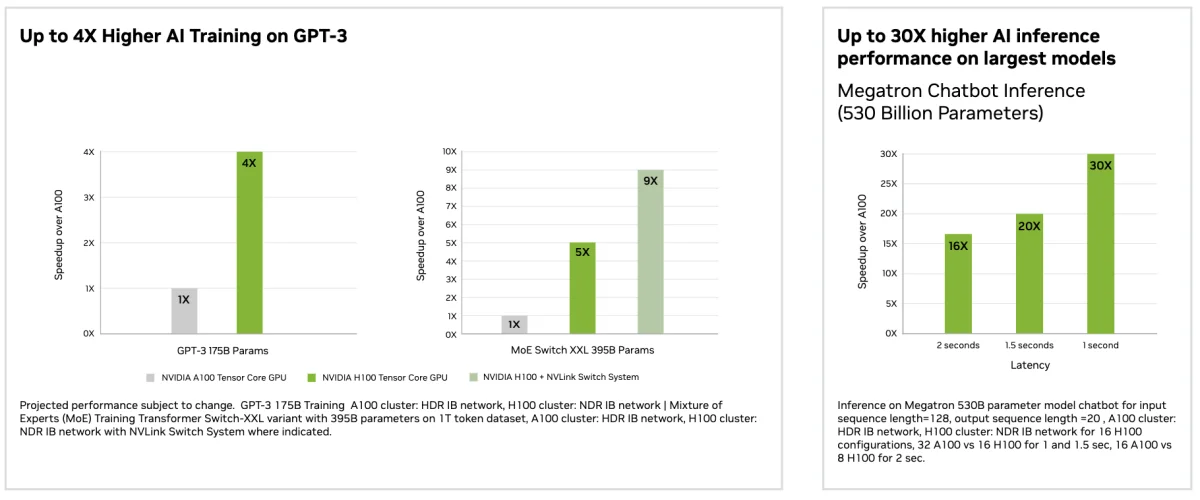
Performance Highlights
The performance benchmarks for the H100 GPUs, as reported by NVIDIA, indicate impressive capabilities with up to a 4x training speedup and up to a 30x speedup in inference tasks when compared to the previous A100 GPUs. This performance leap is particularly relevant in applications that depend on quick response times, such as interactive large language model (LLM) inference. Such improvements can yield noticeable benefits, especially in consumer-facing applications where latency can significantly impact user satisfaction. In contexts like chatbots or virtual assistants, decreased response time from faster inference can transform user engagement and retention.
Modal leverages these advancements, allowing users to take full advantage of the H100s efficiently. The GPUs feature an impressive 80 GB of on-chip DRAM, ensuring high bandwidth connectivity to compute units. Capable of achieving nearly 2,000 teraFLOPS at 16-bit precision, the H100s empower users to tackle larger models or fine-tune existing ones more effectively. For researchers working with deep learning frameworks, such performance characteristics mean fewer roadblocks in experimenting with more complex architectures or scaling models to meet specific needs.
Cost-Effectiveness and Deployment
While high-performance GPUs may come at a premium operational cost, Modal users will find that the economic model supports their needs. Running on Modal's H100 GPUs is priced at $7.65 per hour per GPU. Given that up to 8 GPUs can be used in one job, interconnected via NVIDIA NVLink with a bisectional bandwidth of 3.6 TB/s, it's possible to achieve impressive performance without incurring excessive expenses immediately. This combination of competitive pricing and the ability to pool resources efficiently makes the H100s an attractive option for startups and academic institutions racing to keep pace with AI advancements.
Moreover, Modal's autoscaling functionality means users only pay for what they need, aligning resources dynamically according to workload demands. Developers experiencing sudden surges in inference requests—like those that might occur when an application trends on platforms such as HackerNews—can access the necessary computational resources right when they need them, ensuring uninterrupted service and performance. This flexibility is a significant advantage over fixed GPU reservations that often lead to underutilization and wastage of resources, which is a common pain point in many cloud service models.
How to Get Started
Implementing the H100 on Modal is straightforward for developers. To begin using the H100 GPUs, you simply designate the type of GPU in your Modal function's decorator. Below is a concise example demonstrating how to configure a function to run on H100s:
import modal

app = modal.App()

@app.function(gpu="H100")
def run_gpt5():
    # This will run on Modal's H100s
This simplicity encourages users to integrate H100 capabilities into their workflows without facing cumbersome setup processes. In an industry where time to deployment can often be a barrier, this streamlined approach allows developers to focus on building and optimizing their applications rather than getting bogged down by configuration details.
Feedback and Community Engagement
Modal is keen to hear from users who explore the capabilities of the H100 GPUs. Whether you have questions regarding deployment or want to share projects utilizing H100 speeds, Modal encourages interaction through their community Slack. Engaging with peers and experts can enrich users' experiences while promoting a collaborative atmosphere for machine learning advancements. This community-driven interaction can lead to new ideas, techniques, and collective problem-solving — a potential source of innovation that benefits everyone involved.
Implications and Future Outlook
The availability of NVIDIA's H100 GPUs on Modal signifies a notable shift in the computational power accessible to researchers and developers. As machine learning models continue to grow in complexity and size, the need for efficient and cost-effective computing solutions will only amplify. Modal’s offering positions users to take advantage of NVIDIA's latest technology without sacrificing performance or breaking the bank.
What this means for you, especially if you’re working in AI, is that as models become larger and more sophisticated, the infrastructure supporting these innovations must keep pace. The H100s present a significant opportunity for organizations to improve their model training and deployment processes, ensuring they remain competitive. However, this is just the beginning. As the industry adopts and integrates these H100 capabilities, it will be fascinating to see how performance metrics evolve. Users can look forward to not only enhanced processing speeds but also a better understanding of how these technologies influence the advancement of AI overall.
The ongoing transition towards larger models and more intricate algorithms necessitates strong computational support, and with H100s now on Modal, users have an edge in optimizing their machine learning operations. Keep an eye on how performance metrics shift as users integrate these technologies into their projects. This isn't just about faster processing. It's about redefining what's possible in machine learning capabilities.


