Maximizing ROI: The Efficiency and Versatility of NVIDIA AI Factories
- Gate
- Machine Learning
- Departs
- Crew
- Shruti Koparkar
- Passengers
- 326
NVIDIA AI factories enhance ROI through high productivity, durability, and versatility, enabling endless demand and maximizing earnings over time.
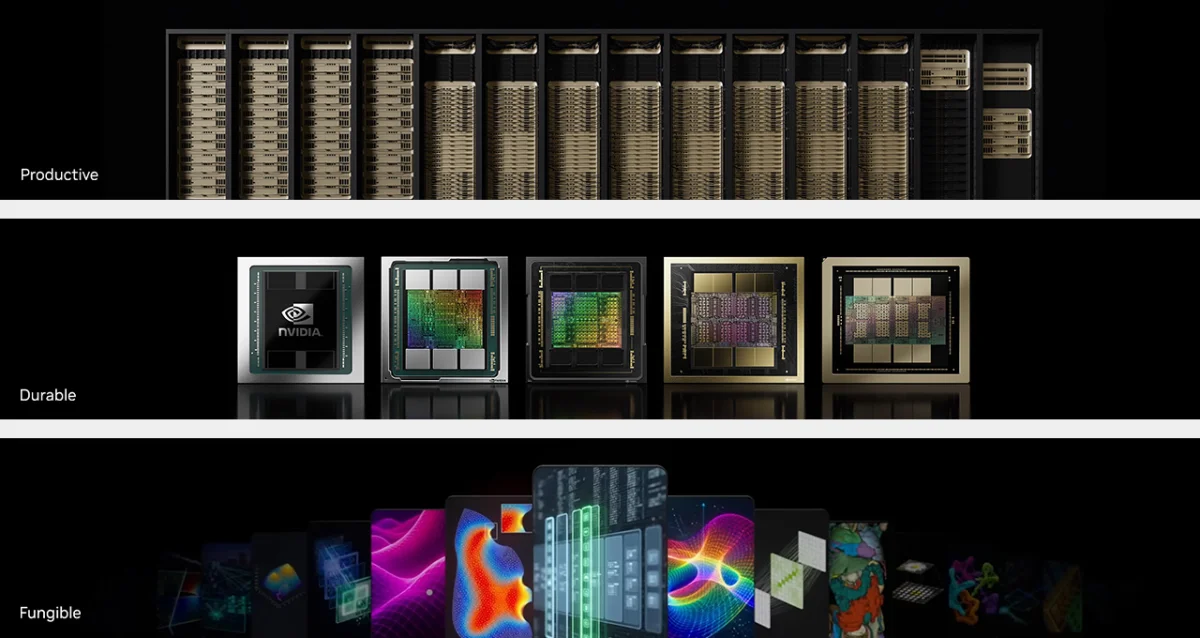
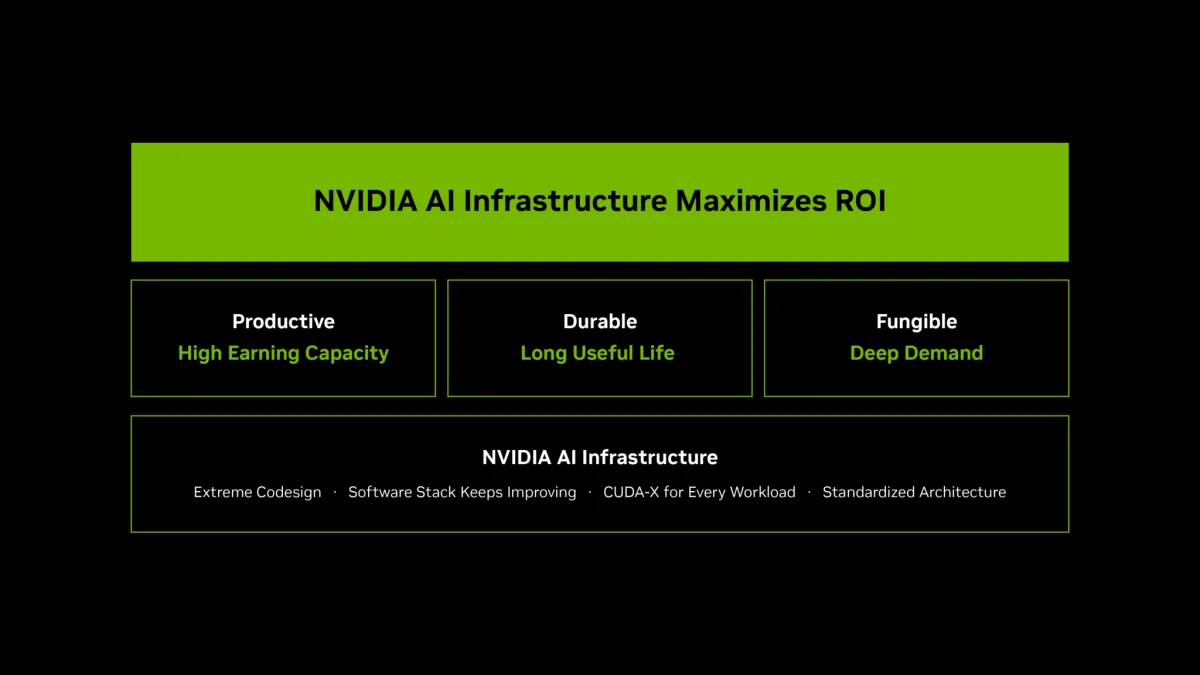
As AI technologies mature, the construction of AI factories has taken on a megawatt and gigawatt scale, with each megawatt factory requiring an investment of around $60 million. Operators only make such significant financial commitments when there’s a clear understanding of the return on investment (ROI). Three primary factors influence the returns from these AI factories:
- Earning capacity: The potential annual revenue based on the factory's production of tokens.
- Useful life: The longevity of the AI hardware in generating revenue over time.
- Demand: The market demand for the tokens produced by the factory.
Each of these metrics plays a crucial role, but no factor alone can compensate for weaknesses in another. For instance, a high-earning capacity is of little use if only a fraction of produced tokens can be sold. Similarly, substantial demand becomes irrelevant if a factory ceases production prematurely. Importantly, these three factors do not operate in isolation. A factory that supports a wide range of workloads can generate increased demand, thereby enhancing its revenue sustainability over the years.
NVIDIA has engineered its AI factories to optimize all three variables, prioritizing:
- Productivity: Achieving maximum throughput per megawatt and minimizing the cost per token.
- Durability: Ensuring that NVIDIA GPUs and systems remain productive long after their initial deployment.
- Fungibility: Allowing the factories to run a diverse set of AI applications across various stages, broadening the market they can serve.
Productivity: Maximizing Tokens and Minimizing Costs
The binding constraint within AI factories is power availability, making tokens produced per second per megawatt a critical metric for assessing earning capability. Higher token production within the available power leads to increased revenue, while lower token cost translates to greater profit margins.
Data from SemiAnalysis AgentX indicates that NVIDIA's Vera Rubin NVL72 systems achieve over 30 times the throughput per megawatt compared to the older NVIDIA GB300 NVL72 architecture, while also providing up to 45 times lower costs per million tokens produced using the DeepSeek V4 Pro model. Such improvements stem from comprehensive design efforts across the stack, including hardware and software, which are optimized holistically.
This leads to two essential considerations. First, if advancements in technology render tokens cheaper, does compute demand decline? The answer is no; it actually expands. More affordable tokens open the door to more economically viable use cases, typically resulting in token consumption that exceeds the savings gains. Second, regarding durability: With each iteration being significantly more efficient than the last, how do older models fare in the evolving marketplace?
Durability: Longevity of the Installed Base
The requirements of various workloads can dictate the necessity for the latest systems. Often, previous generations of hardware continue to generate revenue as certain workloads don’t necessitate cutting-edge technology. The NVIDIA A100 GPU, initially released in 2020, has maintained its operational efficacy, evidenced by CoreWeave extending the booking for these units through 2029.
Operators continually extend the depreciation timelines for their servers, indicating a projection of hardware longevity that often outstrips initial estimations. A recent analysis by Sprout titled The Productive Life of a Data Center GPU tracked these trends, revealing that many GPUs exceeded expected operating lifetimes. For instance, Microsoft has reported that its NVIDIA V100 fleet averaged 8.4 years of active service, contrasting with a projected lifespan of six years.
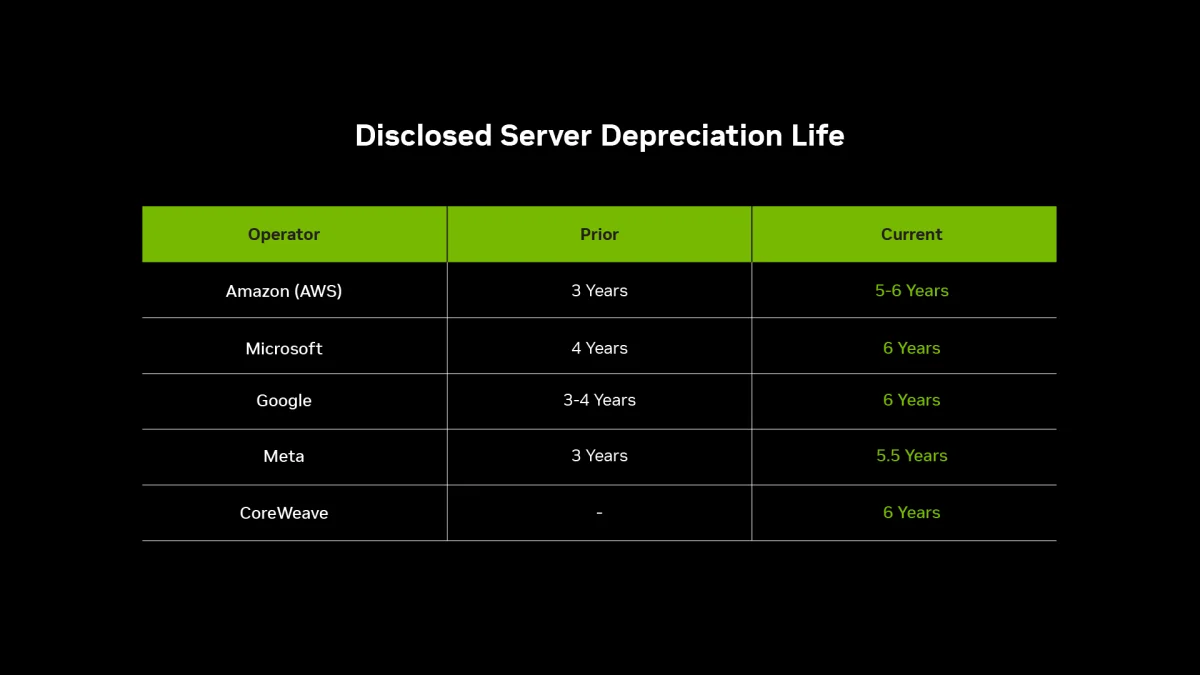
According to analysis from Barkr, an eight-GPU H100 system has a useful life estimate stretching between five to six years, while the GB300 NVL72 can perform for nine to ten years based on resale potential. Notably, a six-year-old A100 GPU is reported to retain about 25% of its original value, while previously a five-year depreciation plan would have rendered it valueless.
NVIDIA's development environment, CUDA, designed for GPU programming, ensures that operators' investments remain viable, as it is compatible across generations. This platform supports numerous applications, including machine learning, deep learning, and various types of AI, continually enhancing the capabilities of existing hardware.
Fungibility: Versatile Applications Across Diverse Workloads
A factory dedicated to a specific AI application poses a risk; its profitability hinges on the continued demand for that particular workload. In contrast, NVIDIA AI factories maintain utility and revenue potential by supporting varied AI tasks across multiple domains.
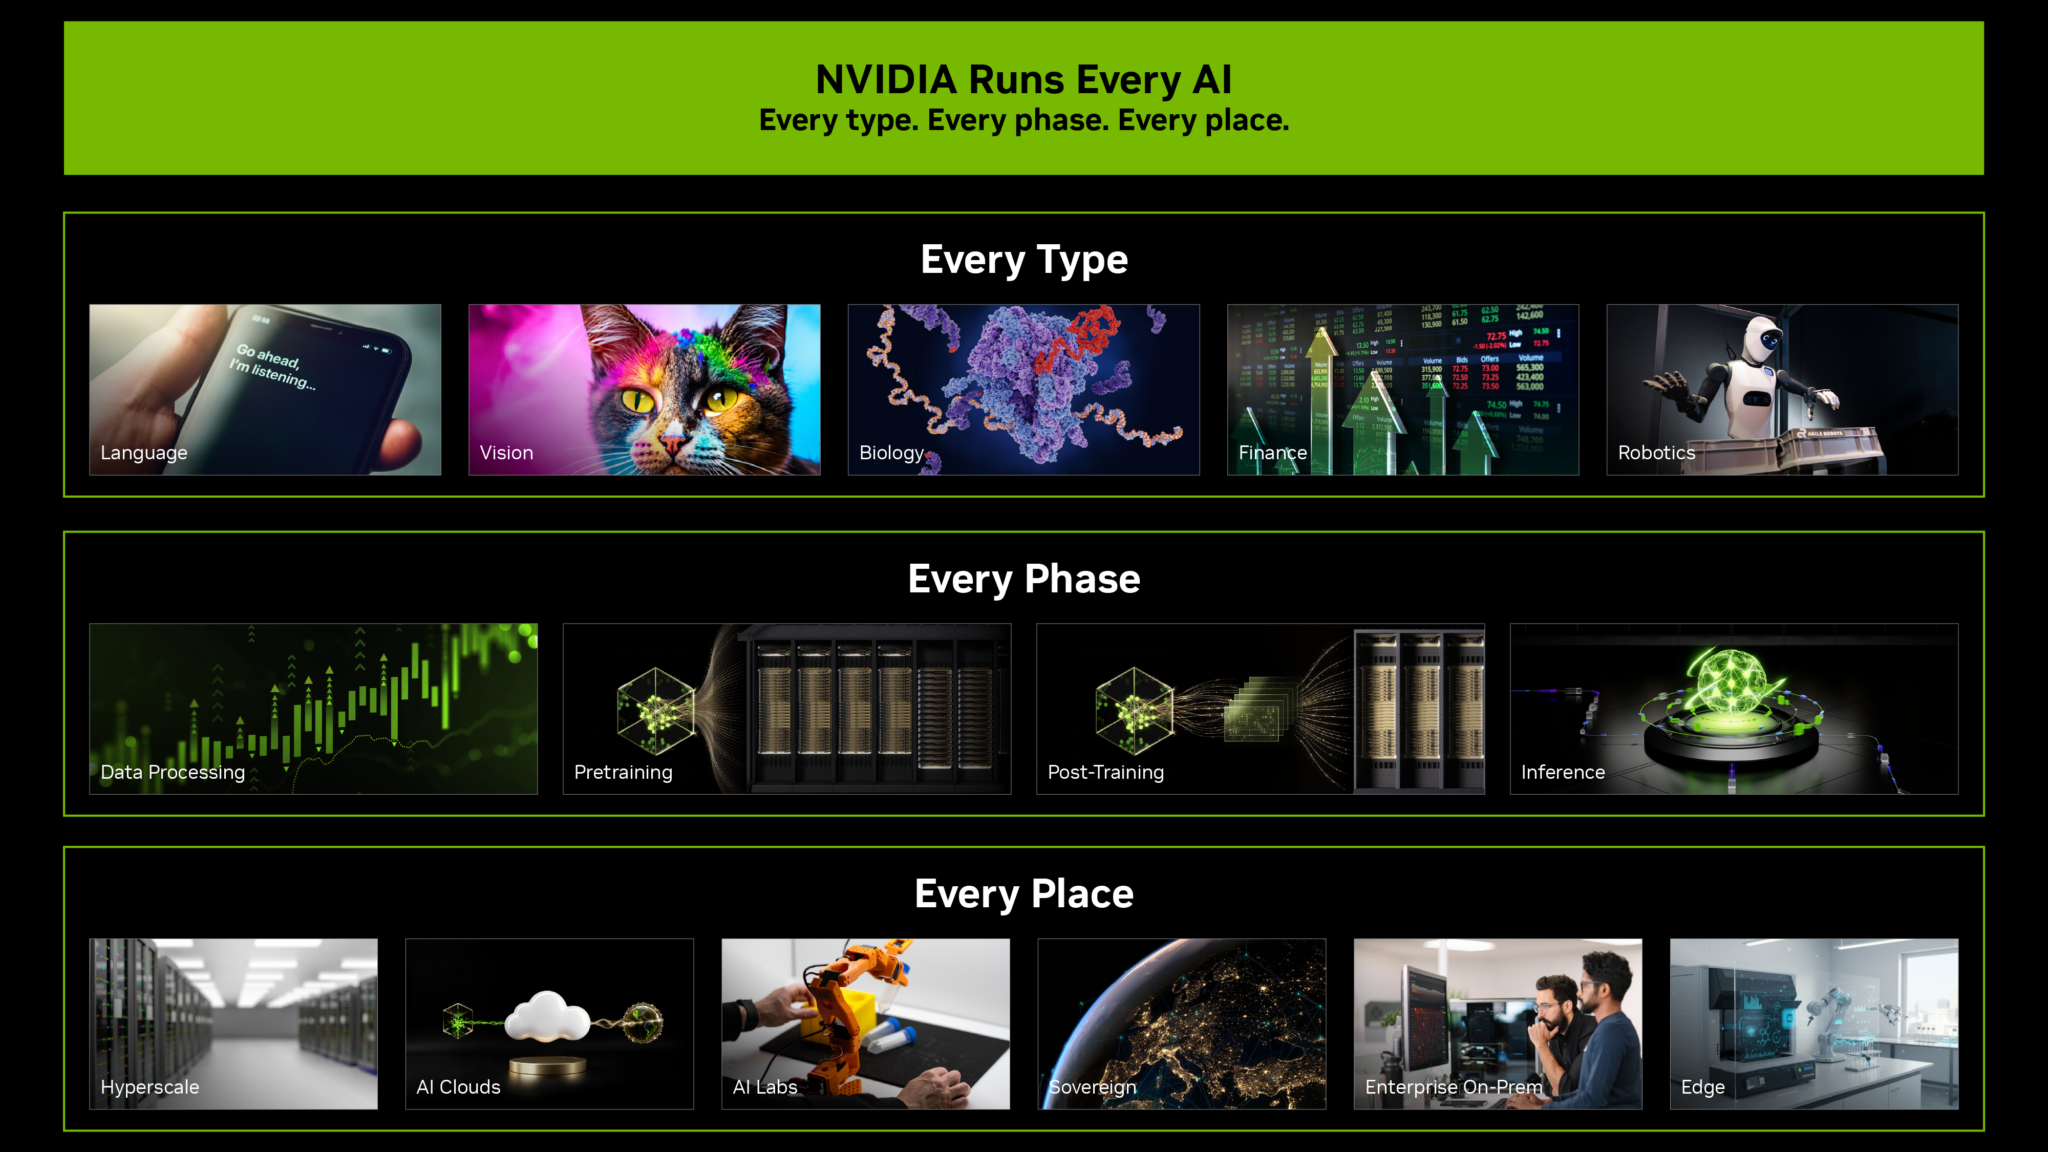
These factories can accommodate all types of AI models, whether proprietary or open-source, covering applications in language, vision, biology, physics, and robotics. They support every phase of development, from data processing to model training and inference, and can be utilized in diverse environments from hyperscale clouds to edge computing solutions.
Beyond AI, this infrastructure effectively powers scientific simulations and data processing, among other tasks. NVIDIA's GPUs are engineered to handle numerous operations in parallel, with resources including over 1,000 ready-to-use CUDA-X libraries that support various computational needs, from climate modeling to quantum circuit simulations.
Such general-purpose computing capabilities help maintain high utilization rates, thus optimizing returns. The architectural integration of specialized functions like Tensor Cores within a flexible framework exemplifies how NVIDIA balances adaptability with effectiveness.
Practical applications illustrate this versatility:
- Lilly: Developing and operating protein and genomics models in a robust 1,016-GPU on-premises cluster, alongside chatbot implementations for team collaboration.
- Pinterest: Conducting post-training and deploying vision language models across 14,000 GPUs in a hyperscale cloud setup with generational diversity.
- Revolut: Leveraging NVIDIA cuDF for processing massive data sets, followed by training and deploying foundational models in an AI cloud environment.
- Runway: Utilizing NVIDIA Hopper to train complex models, while operating via the NVIDIA Blackwell platform in a cloud setting.
- Texas A&M University: Executing molecular simulations and AI-driven drug discovery through a high-utilization supercomputer across multiple projects.
Beyond AI-centric applications, companies like Cosm showcase how NVIDIA technologies can offer flexible compute resources for high-resolution media applications, while Dassault Systèmes leverages systems for virtual twin simulations in aerospace certification tasks.
NVIDIA AI factories are meticulously engineered to ensure high productivity, prolonged durability, and remarkable fungibility. These attributes collectively drive superior returns, making them an attractive investment in the rapidly evolving AI landscape.
For additional insights on NVIDIA's AI factories, watch NVIDIA's founder and CEO Jensen Huang's GTC Berlin keynote on Wednesday, Oct. 21, at 11 a.m. CEST.


