NVIDIA RTX Spark Laptops Add Local AI Tools, GPU Controls and New Game Support
- Gate
- Generative AI
- Departs
- Crew
- Shreevar Rastogi
- Passengers
- 472
RTX Spark laptops combine up to 128GB of unified memory with new speech, agent and graphics tools, starting at $2,599.
NVIDIA’s RTX Spark laptops bring local AI development, creative work and gaming together in thin Windows systems built around a single chip. The new software updates make that hardware more useful in specific ways: a speech model handles transcription and translation, an app lets users divide GPU capacity between active programs and background agents, and game and modding tools add new graphics features.

A laptop platform for local AI and graphics
RTX Spark laptops are available from ASUS, Dell, HP, Lenovo, Microsoft and MSI. They pair an NVIDIA Blackwell RTX GPU with an NVIDIA Grace CPU in one superchip, with up to 128GB of unified memory and up to 1 petaflop of FP4 AI performance. The shared memory pool can serve both AI models and creative applications, while the system also provides access to CUDA and RTX graphics.
Configurations start at $2,599, and models with 128GB of memory are on shelves. Designs include different display sizes, touchscreens, pen support and two-in-one formats. NVIDIA says some models are as thin as 14mm and weigh as little as three pounds, with all-day battery life.
For developers, the pitch is the ability to run models and agents locally on CUDA, with a path to deploy across more than 150 million NVIDIA RTX AI PCs and NVIDIA GPUs in the cloud. Creators can edit camera-native 4:2:2 video and render 3D scenes of up to 90GB; Adobe Photoshop and Premiere have native RTX Spark support through beta releases. Gamers get access to hundreds of games, with DLSS, ray tracing, Reflex and G-SYNC among the supported features.
One model for recorded speech tasks
NVIDIA Nemotron 3.5 Transcribe is an open-weight model for transcribing recorded audio, identifying speakers, translating speech and answering questions about recordings. It supports 40 languages, including seven Indic languages. Developers can specify tasks in plain language, such as requesting a transcript with speaker labels, an English translation or a list of meeting decisions.

Prompts can also supply product vocabulary and formatting rules, which may help teams working with specialized terms in areas such as healthcare, financial services and customer service. Since the model weights are open, developers can choose where to process audio, from a desktop to cloud infrastructure.
NVIDIA says the model ranks No. 1 on the Hugging Face Open ASR leaderboard and No. 2 among open-weight models on Artificial Analysis. It has approximately 4.3 billion active parameters, which NVIDIA describes as 80% fewer than the No. 1 open-weight model. Those figures suggest a focus on bringing capable speech processing to local hardware, though actual performance will depend on the workload and system configuration.
The model is available on Hugging Face. Quantized versions are expected to run on RTX Spark and DGX Spark systems, Jetson AGX Thor devices and NVIDIA Blackwell data center GPUs. NVFP4 versions are planned for deployment through NeMo-Speech.cpp or vLLM. More technical detail is in NVIDIA’s technical blog.
GPU sharing for foreground apps and agents
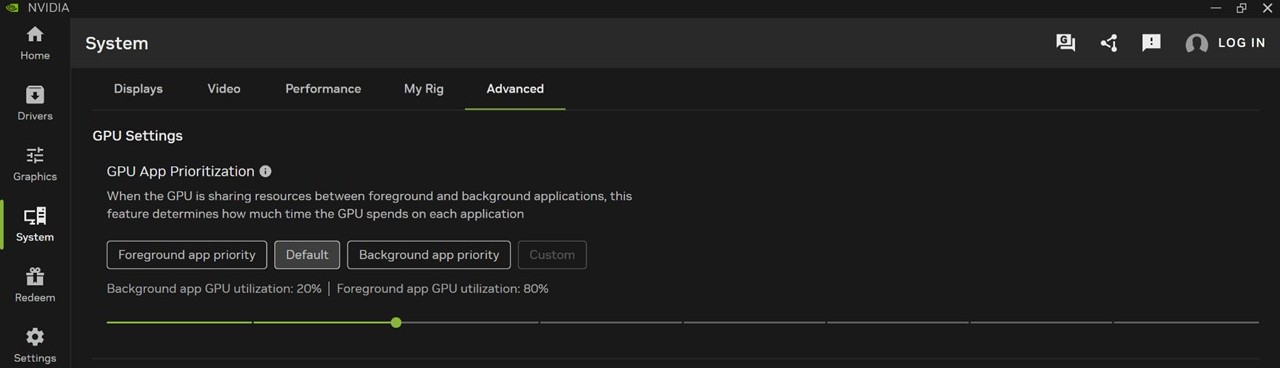
Local agents can run for extended periods while users work in other applications, but the processes compete for GPU compute. A new control in the NVIDIA App lets users choose which side gets priority: the foreground application for more responsive use, or the background agent to finish its work sooner.

The setting is under System > Advanced in the app and requires hardware-accelerated GPU scheduling to be enabled in Windows Settings.
Compact models and local agent workflows
Liquid AI’s LFM3 family spans text, vision, audio, multimodal and decision models built on a shared backbone. Base and post-trained models are available as open weights, with day-zero support announced for RTX Spark. Liquid AI says its new 1.7-billion-parameter base model outperforms its earlier 2.6-billion-parameter base model.
Potential local uses include agents in Hermes Agent, Pi and OpenClaw that sort inboxes, manage calendars, read documents and app screens, transcribe or translate speech, answer spoken questions about handwritten math, and route support tickets or voice requests. Developers can run LFM3 on RTX Spark through llama.cpp and vLLM, and fine-tune models locally.

New graphics features for games and mods
S-GAME’s Phantom Blade Zero launches Oct. 28 at 7 p.m. PT on Steam and the Epic Games Store. Players take the role of Soul, a swordsman framed for his master’s murder who sets out to uncover a conspiracy. The game includes ray-traced lighting, reflections and shadows on foliage and terrain. NVIDIA DLSS Dynamic Multi Frame Generation can generate up to six frames, or adjust its multiplier to target a selected frame rate. Details are on GeForce.com.
NVIDIA RTX Remix version 1.6 adds support for rendering Minecraft Java Edition 1.21.1 through RTX Remix, with DLSS-accelerated path tracing. The update also brings RTX Spark support to Portal with RTX and the Half-Life 2 RTX demo. Both gain DLSS 3D-Guided Neural Rendering, a Performance Mode for DLSS Frame Generation and options intended to speed up path tracing. NVIDIA’s RTX Remix blog describes the release, which also adds DLSS 5 with 3D-Guided Neural Rendering and up to six-times Multi Frame Generation.
Remix 1.6 also changes the modding workflow. A redesigned ComfyUI integration can generate physically based materials inside RTX Remix without API setup, supports batch processing across projects and includes presets for less technical creators. Compatible AI agents can use NVIDIA agent skills to assist with remastering work.
Other local AI releases
At GTC Berlin, NVIDIA founder and CEO Jensen Huang demonstrated agents on RTX Spark helping train Hugging Face’s Microduck robot. The described workflow uses Hermes Agent and Nemotron 3.5 Bolt to plan an obstacle course, Astra to create 3D assets, NVIDIA Isaac Lab to train a navigation policy, and Isaac Sim to validate it. The demo and playbook are available.
NVIDIA Nemotron 3.5 Bolt E4B 4GB supports natural conversations and multistep agent tasks with as little as 4GB of memory. It is aimed at local voice assistants, game characters and embedded interfaces, and supports llama.cpp, vLLM, Ollama, Unsloth and LM Studio, as well as Hermes and OpenClaw. For larger agent workloads, Nemotron 3.5 Bolt 74B-A9B 24GB is designed to run on RTX Spark.
Black Forest Labs’ FLUX 3 Image Klein is an open-weight image generation and editing model with 5.6 billion parameters. NVIDIA-optimized versions run on RTX GPUs with as little as 8GB of VRAM. Developers can fine-tune it on RTX Spark with an NVIDIA NeMo AutoModel recipe.
NVIDIA DGX Spark 64GB is also available from manufacturer partners. Its GB10 Grace Blackwell Superchip combines 64GB of unified memory with DGX OS and NVIDIA’s AI software stack for agent development, inference and fine-tuning. More information and purchase options are available.
The practical question for RTX Spark buyers is how much of their work benefits from running on-device. Shared memory and local model support can reduce dependence on remote processing, while the growing toolset covers speech, image generation, agents and graphics. The hardware starts at $2,599; model size, memory needs and software support will determine which workflows fit.
Follow NVIDIA RTX Spark on X, Instagram, TikTok and Facebook, or subscribe to the NVIDIA Local AI newsletter. NVIDIA Workstation is on LinkedIn and X.
See the notice regarding software product information.