Designing Scalable AI Factories with Custom XPUs and NVLink Fusion
- Gate
- Machine Learning
- Departs
- Crew
- Jesse Clayton
- Passengers
- 437
AI factories need to optimize infrastructure and networking. NVLink Fusion connects custom XPUs to high-performance NVIDIA solutions, easing development complexity.
To effectively generate intelligence at scale, AI factories must operate continuously, leveraging metrics that encompass tokens produced per second, tokens processed per watt, cost per token, and overall system uptime. Such demands necessitate a full factory approach to AI infrastructure rather than merely assembling collections of individual components.
Organizations such as hyperscalers and AI-native companies undertaking the development of custom XPUs must thoughtfully consider not only the design of the XPUs themselves but also the comprehensive development of the entire AI platform. This includes elements such as scale-up networking, rack-scale architecture, factory production software, and fostering a reliable supplier ecosystem. However, navigating these complexities can be expensive and a significant barrier to rapidly bringing XPUs to market.
To overcome these challenges, it’s critical to merge custom XPUs with existing, proven infrastructure. This enables teams to channel their innovation efforts where they’re most impactful, leveraging established technologies for the foundational aspects. NVLink Fusion, for example, effectively addresses this need by connecting XPUs with NVIDIA's advanced AI infrastructure, boosting performance, reducing time-to-market, and minimizing risk for semi-custom AI factories.
Unlocking XPU Performance Through Scalable Solutions
In modern contexts, especially when handling workloads like trillion-parameter models, mixture-of-experts architectures, and agentic AI, if the scale-up networking cannot keep pace, it will lead to decreased utilization and increased costs per token. Therefore, a networking solution designed for scale-up must excel in three key areas:
- Delivered performance: Achieving end-to-end network performance, in-network computing capabilities, and seamless software integration.
- Factory resiliency: Ensuring consistent uptime through continuous health monitoring and telemetry, along with component-level serviceability while the system remains operational.
- Platform maturity: Minimizing operational risks by utilizing a reliable technology stack with proven success in large-scale deployments and tangible returns on investment.
NVIDIA's NVLink Fusion illustrates this principle as it integrates XPUs into the NVIDIA NVLink scale-up ecosystem. The sixth generation of NVLink boasts high-bandwidth, low-latency networking across a 72-XPU domain; notably, its end-to-end latency for XPU-to-XPU transfers is three times lower compared to conventional Ethernet solutions, while achieving packet rates up to ten times higher.
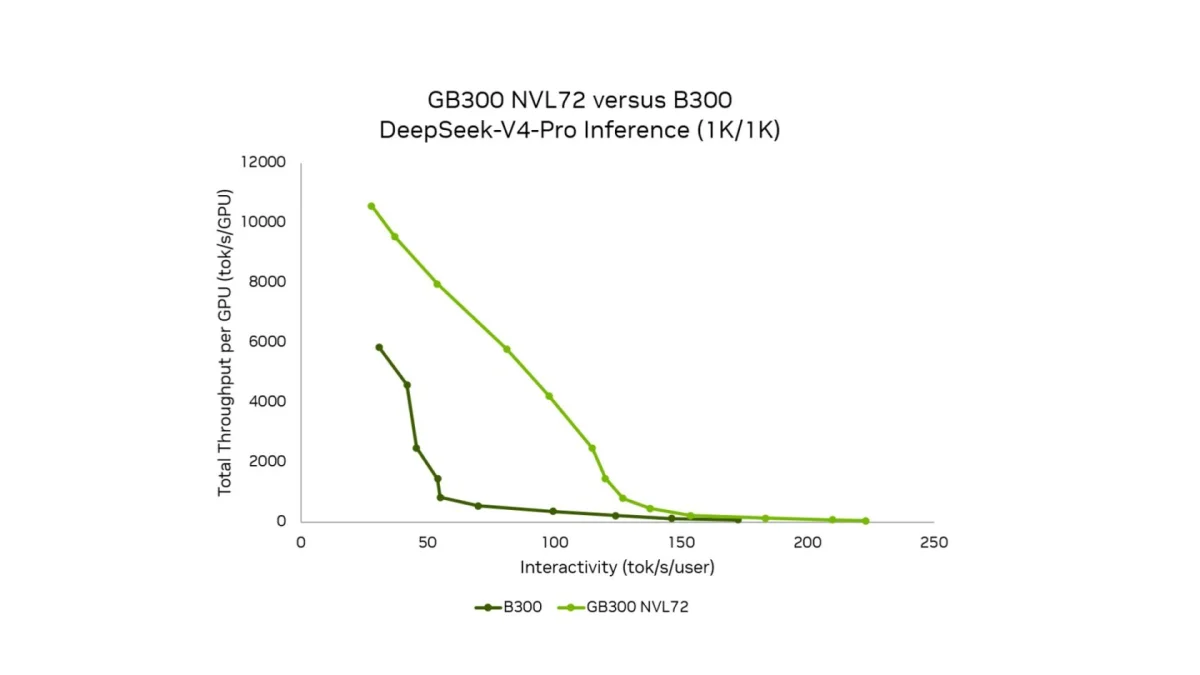
For enhanced end-to-end performance, the NVIDIA GB300 NVL72 systems offer substantially increased throughput and improved interactivity relative to configurations that do not utilize NVL72. Upcoming NVLink configurations promise scalable domains hosting up to 1,152 accelerators, alongside co-packaged optical solutions.
Moreover, NVLink Fusion incorporates NVIDIA NVLink-C2C, linking XPUs with NVIDIA Vera CPUs or other CPUs in the ecosystem while offering energy efficiency improvements up to six times greater than a PCIe interface. This feature effectively breaks down barriers between control and computation in agentic AI systems.
A Reliable Ecosystem for Development and Deployment
Development teams working on custom XPUs frequently misjudge the effort entailed in transforming XPU prototypes into operational data center systems. Key integrations required include:
- Establishing high-speed CPUs and scale-up interface connections.
- Identifying and validating a scale-up network solution.
- Designing compute and switch trays.
- Developing and validating rack architectures with necessary cooling and power specifications.
- Integrating robust security measures and storage solutions.
- Managing a complex supplier ecosystem.
The optimal platform would address all these aspects, thereby freeing teams to zero in on specific innovations while relying on proven technologies elsewhere. NVLink Fusion is designed to support a rapid development ecosystem that encompasses ASIC design, CPU, optical interconnect partners, and more.
As Tim Wilson, VP and General Manager of Data Center Silicon Engineering at Intel, stated, “NVLink Fusion gives customers the ability to choose the CPU architecture, the performance level, the software capabilities that best meet their needs for the workloads they care about.”
Additionally, adopters of NVLink Fusion can harness the NVIDIA MGX rack-scale architecture alongside the supply chain used for systems like NVIDIA Vera Rubin NVL72. Manufacturing partners facilitate design and integration, while MGX supplies essential components for racks, cooling, and powering advanced systems, including emerging 800 VDC designs.
Jack Luoh, Head of Product and Solution at QCT and Quanta Computer, noted, “With Vera Rubin [NVL72], we are looking at almost 100% automation of system builds in the manufacturing line.” This level of automation is highly beneficial, allowing manufacturers to leverage investments efficiently, particularly with XPU designs utilizing NVLink Fusion.
Standardizing Infrastructure to Manage Risk
AI factory planning initiates well ahead of silicon availability—considerations like power procurement, facility design, cooling systems, rack layout, and network structure begin at an early stage. A data center that ties itself to a singular chip design may encounter scheduling risks down the line.
Different workloads may necessitate diverse accelerators, incorporating XPUs, GPUs, CPUs, and LPUs. Often, GPU systems will operate alongside semi-custom configurations for various tasks, such as training and inference.
Vince Hu, Corporate Senior Vice President and GM of the Data Center and Computing Business Group at MediaTek, explained how the NVLink Fusion program helps, stating, “Customers can deploy their rack-level solution with the NVIDIA GPU, and then they can decouple the development of their XPU and manage the pace of development separately.”
NvLink Fusion addresses these challenges by establishing a unified architecture. Systems built on XPUs and GPUs, like Vera Rubin NVL72, can utilize the same rack space, networking infrastructure, cooling designs, and power delivery systems. This permits operators to proceed with data center buildouts while deferring exact silicon selections, ensuring adaptability as workload requirements and priorities shift.
As Lie-Szu Juang, Chair and Chief Strategy Officer at GUC, pointed out, “NVLink Fusion allows hyperscalers or custom ASIC designers to integrate their custom CPU or XPU, bridging NVIDIA technology seamlessly with third-party processes to create a cohesive rack-scale architecture.”
Operating as a Fully Integrated Factory
Building out an AI factory can be costly, with missteps resulting in significant rework. Every piece of infrastructure must be meticulously validated before construction begins. NVLink Fusion's alignment with the NVIDIA DSX reference architecture enables an integrated approach that includes co-designing building features, power, cooling, computing, and networking elements to optimize performance and efficiency. NVIDIA Omniverse provides a digital twin and reference design for large-scale AI factories.
On the rack level, NVLink Fusion prioritizes serviceability as part of performance; its reference compute trays utilize 100% liquid cooling—eliminating fans and cables while allowing for operational continuity during maintenance. NVLink Switch trays also incorporate liquid cooling, ensuring ongoing functionality during service interventions.
Annapurna Labs’ Senior Hardware Development Manager CC Lee remarked, “With NVLink Fusion, we can use proven NVL72 rack design to enhance our time-to-market, obtaining access to multiple suppliers to deliver more to our customers.” Moreover, software solutions round out the requirements of this factory environment. NVIDIA’s NCCL for distributed workloads, Dynamo and NIXL for disaggregation, and Mission Control software for cluster management further facilitate the operation of mixed AI infrastructures.
Through the capabilities offered by NVLink Fusion, XPUs are positioned to interact within a sophisticated, world-class AI platform. This integration empowers both hyperscalers and AI-native companies to construct unified, semi-custom AI factories that draw on a collective capability that no single entity could achieve independently.
Discover more about NVLink Fusion.


