TypeSafe AI's Jev Model Reaches Trillions of Tokens in Record Time on Modal
- Gate
- Machine Learning
- Departs
- Crew
- William Davis
- Passengers
- 380
TypeSafe AI’s Jev model, focused on rapid decision-making, scales to over one trillion tokens in just three days using Modal’s serverless infrastructure.
TypeSafe AI operates under a distinctive manifesto: “Build Prod, Not God.” Their flagship product, Jev, aims to facilitate rapid, structured decision-making through advanced intelligent processing. Following its launch week, demand for Jev surged dramatically, highlighting the model's capabilities in real-world applications.
A New Class of Frontier Model
Jev differs significantly from traditional large language models (LLMs). It is categorized as a System One Model, focusing on fast and intuitive responses rather than generalized language understanding. This model excels in System One tasks while prioritizing decision-making over broad intelligence. According to TypeSafe, Jev's architecture streamlines outputs, making it ideal for applications requiring structured decision support.
To develop Jev, TypeSafe created a custom operational stack that emphasizes automation. This includes a new model architecture and a parallel sampler designed for maximum efficiency. The innovative training methodology, termed Reinforcement Learning for Calibrated Decisions (RLCD), enhances Jev’s accuracy. Unlike LLMs, which are typically autoregressive, Jev processes input in a manner that allows it to output structured values and probabilities simultaneously.
For instance, consider a user query related to a customer support ticket:
{
  "state": "Hi, I've been trying to connect my Stripe account for 3 days and the integration keeps failing. Please help ASAP.",
  "model": "jev-latest",
  "questions": {
    "department": {
      "type": "choice",
      "instructions": "Which team should handle this?",
      "criteria": {
        "billing": "Payment or subscription issues",
        "technical": "Bugs or integration problems",
        "sales": "Pricing or account questions"
      }
    }
  }
}
The input allows Jev to intelligently categorize the issue into appropriate departments: technical, sales, or billing. Once the user specifies a preference, such as “technical,” Jev swiftly provides tailored answers along with associated probabilities for its choices.
{
  "model": "jev-1.13.0",
  "answers": {
    "department": {
      "type": "choice",
      "choice": "technical",
      "confidence": 0.78,
      "probabilities": {
        "technical": 0.85,
        "sales": 0.0,
        "billing": 0.15
      }
    }
  }
}
This unique structure allows Jev to generate intelligent outputs in parallel, which is crucial for high-efficiency workflows like large-scale automation and responsive user interfaces.
Scaling Exponentially Over a Weekend
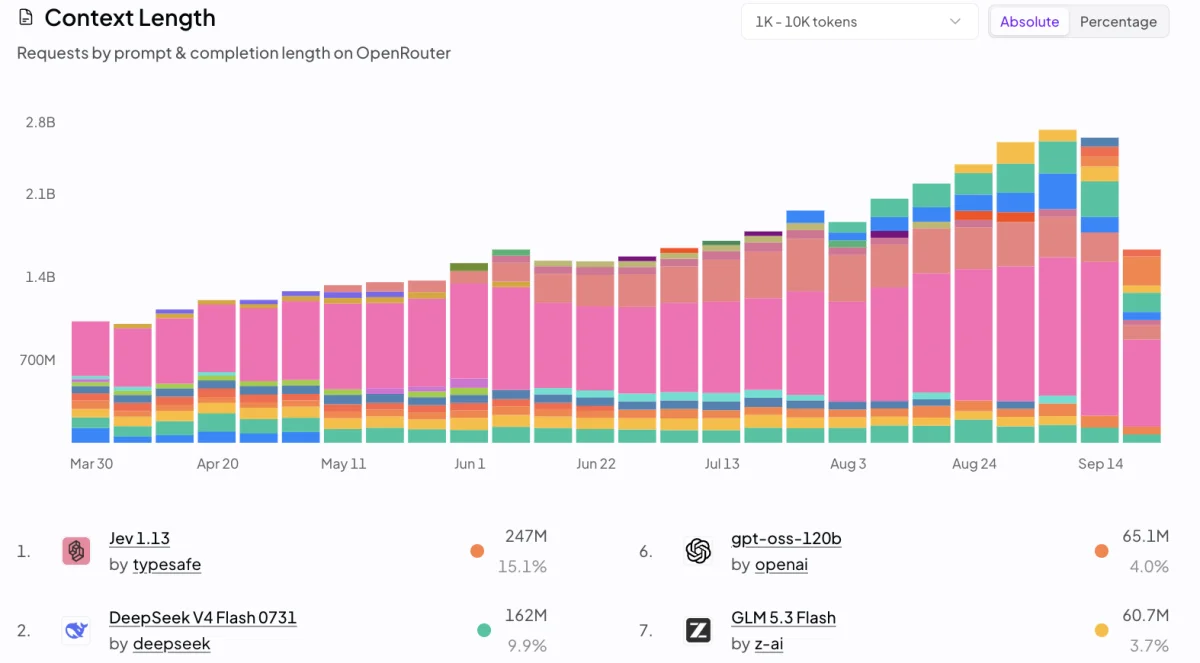
After Jev launched publicly on a Thursday, the performance was immediately validated when it ranked at the top of the OpenRouter leaderboard for contexts of 1K-10K tokens within just a week, managing 15.1% of all requests. This rapid adoption reflects the significant demand being processed, with metrics indicating that usage climbed into the trillions of tokens following the launch.
The TypeSafe team required efficient scaling solutions that provided comprehensive control over their infrastructure—from networking to autoscaling—to meet this unprecedented demand without becoming bogged down in infrastructure management. Recognizing the scale of inference requirements was vital, as efficient processing would dictate Jev’s usability across various applications.
To meet these needs, TypeSafe enlisted Modal’s serverless platform, which is designed to handle bursty, high-concurrency workloads where minimal latency is critical. This arrangement allows AI models like Jev to be quickly trained, served, and scaled without the typical complexities associated with infrastructure management. According to Erik Gafni, CTO of TypeSafe, “Modal served 1 trillion tokens for Jev within three days of launch. Their team was proactive and responsive as we scaled to meet unprecedented demand, and we could stay focused on shipping instead of managing infrastructure.”
Leveraging Modal for Enhanced Performance
Jev's rapid scaling is emblematic of what the Modal platform is tailored for. It can accommodate various types of models, from LLMs to System One Models, all while enabling high-performance delivery. AI teams can leverage this flexibility to experiment with different model architectures and serving routines without fearing over-provisioning or undershooting capacity needs. This setup mitigates typical pitfalls of deployment and allows organizations to focus on developing their applications more efficiently.
As TypeSafe continues to evolve and refine Jev, the focus on operational efficiency and responsiveness will be key indicators of success, especially as demand for intelligent decision-making systems grows. The increasing complexities of AI applications will likely keep pushing teams towards advanced infrastructures that can facilitate rapid scaling without compromising performance.


