MAC
END
Maximizing Efficiency in Large Language Models: Focusing on Latent Demand and Practical Applications
- Gate
- Machine Learning
- Departs
- Crew
- Michael Garcia
- Passengers
- 415
Explore the growing demand for efficient language models that prioritize functionality over advanced intelligence, enhancing cost-performance ratios.
Revisiting Latent Demand in Large Language Models
There's a fascinating conversation brewing around the optimal efficiency of large language models (LLMs). To put it plainly, we're at a point where significant underlying demand exists for practical, low-latency, single-token response systems. It’s a space often overshadowed by the louder pursuit of models that boast higher intelligence levels. Instead of simply chasing advanced capabilities, this latent demand signals an opportunity to invest in solutions that can deliver acceptable intelligence at lower operational costs. Take a moment to consider the ongoing development of coding agents and chatbots. Amidst all the hype, there’s an equally important evolution happening in the background. Utilizing straightforward transformations of data with LLMs can yield impressive results—if the cost-performance ratio is favorable. Just look at examples springing up on social media, showcasing innovative applications using models like Jev. This model exemplifies how creative LLM transformations can operate effectively at what is commonly referred to as the "JSON layer," managing interactions between clients and services efficiently. Interestingly, the advancements aren’t limited to just web interfaces. Platforms like AI-SQL illustrate how analytical interfaces can bridge the gap between business intelligence tools and databases. With the right query structuring, you can enhance data access without the need for excessive resources, opening doors to nuanced inquiry that traditional models might struggle to handle. Ultimately, the current trend seems to be leaning towards harnessing existing capabilities rather than endlessly advancing to higher intelligence thresholds. For those working in this field, it underscores the need for intentional investment in simpler, yet highly effective, LLM deployments that meet real-world demands. As we navigate this evolving landscape, a critical question arises: Are we ready to pivot our focus from merely pushing the boundaries of intelligence to optimizing practical functionality?Distinct Approaches to AI-Driven SQL Queries
In the current landscape, major analytical database providers each offer their unique adaptation of AI-driven SQL functionalities. Snowflake, for instance, incorporates AI-SQL into its platform. You can explore its capabilities [here](https://docs.snowflake.com/en/user-guide/snowflake-cortex/aisql). Similarly, Databricks presents AI Functions tailored for large language models, which can be found in their documentation [here](https://docs.databricks.com/aws/en/large-language-models/ai-functions). BigQuery also supports AI extensions through its AI functions, detailed [here](https://cloud.google.com/blog/products/data-analytics/sql-reimagined-for-the-ai-era-with-bigquery-ai-functions).The Role of GPUs in Analytical Queries
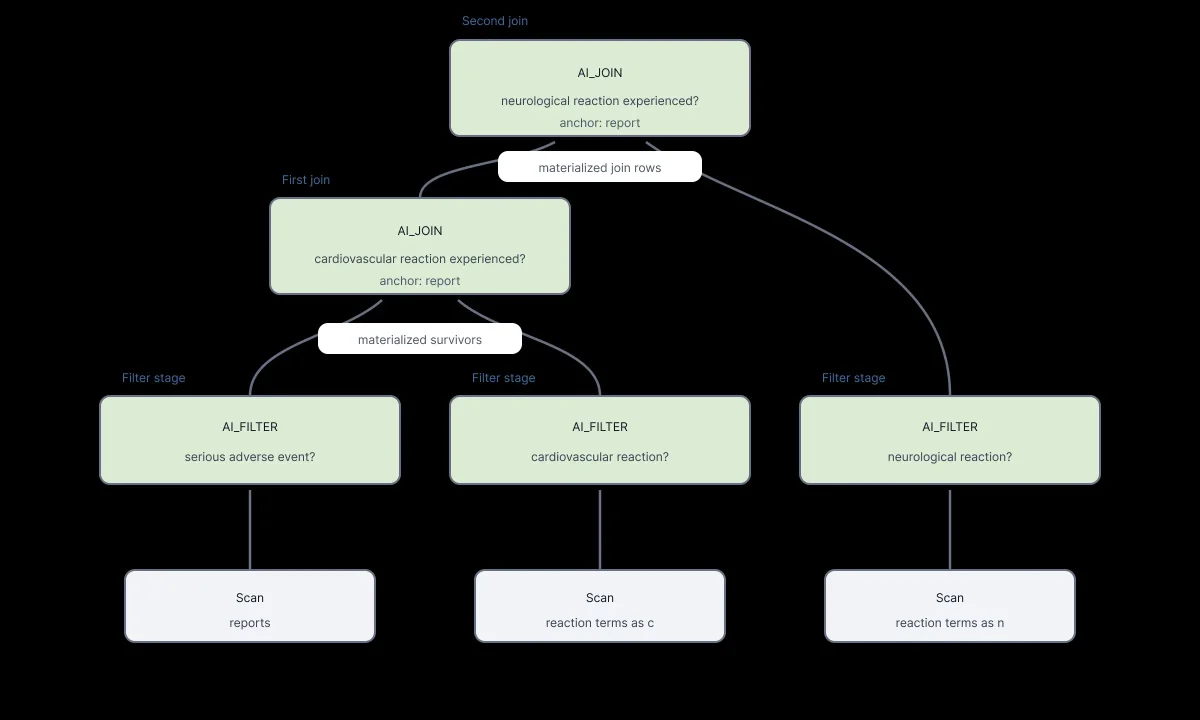
A notable aspect of modern query execution is the dynamic between GPU utilization and the nature of the operations executed. Conventional SQL queries involving standard filters and logical comparisons generally don’t necessitate the computational power that GPUs provide. The reason is straightforward: filtering and joins based on equality or string matching rely on a minimal number of arithmetic operations per byte retrieved from storage. Yet, consider a scenario where a complex query is structured, akin to those executed against the [BioDEX dataset](https://github.com/KarelDO/BioDEX). In this context, if query components interact through a large language model (LLM), the entire operation chain becomes heavily reliant on matrix multiplications. Each byte accessed is subjected to a staggering number of operations – often in the billions – before it’s returned to storage. In such cases, the GPU's architecture becomes beneficial, landing it squarely in the realm of high arithmetic intensity tasks. This trend shifts when you start using advanced AI features, such as the `AI_FILTER` and `AI_JOIN` commands, which utilize LLMs to handle complex input sequences rather than traditional SQL commands. The underlying complexity and need for extensive matrix calculations effectively justify the use of powerful GPUs in these instances.The Implications for Inference Engineers
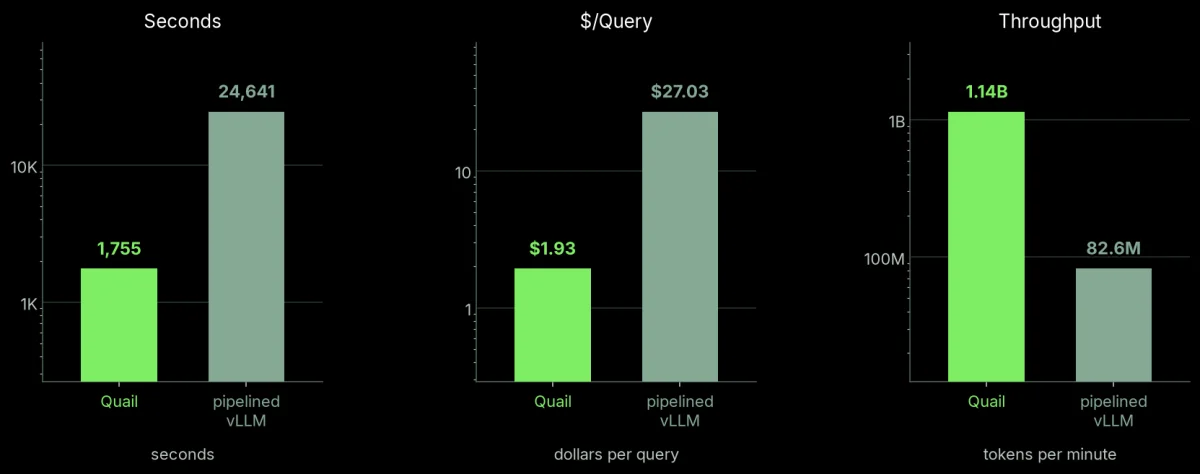
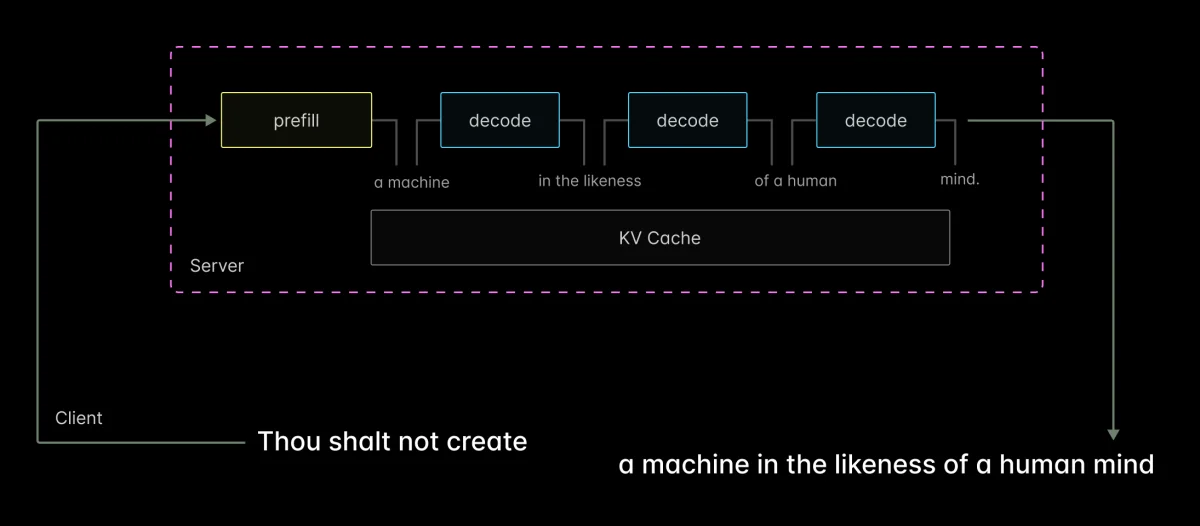
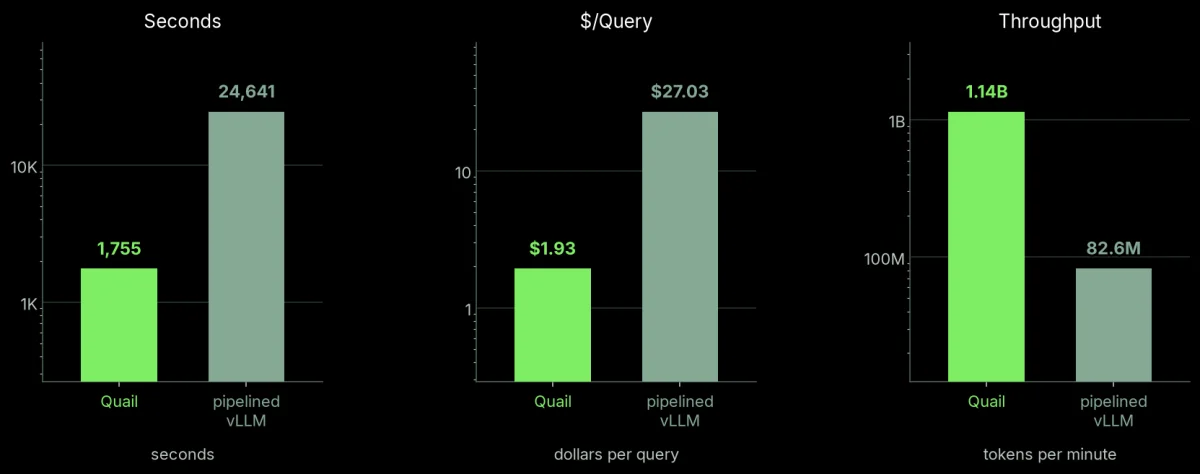
For engineers focused on inference workloads, understanding these complexities is essential. The current emphasis typically centers on constructing long input sequences iteratively—think chatbot applications and similar use cases where performance efficiency ties directly to user query activity. Here lies the crux: inference engineering is often boxed into familiar paradigms, which may overlook the potential efficiency gains from these new data-handling strategies. While conventional workloads emphasize structured outputs, AI-SQL's demand for transformers and GPU efficiency illustrates an emerging trend worth noting. AI-SQL enables effective management of key-value (KV) caches, pivotal for optimizing transformer processing. Unlike traditional workloads, where client requests can introduce unpredictability, AI-driven SQL allows for more deterministic management of query requests. This predictability is a game-changer, allowing engineers to anticipate cache demand and optimize operations preemptively. The significance of this transformation goes beyond just processing speed; it opens doors for reconsidering how various types of operations can be integrated effectively. For practical applications, techniques that simplify cache management—coupled with the ability to preemptively handle input data—yield much-needed acceleration, transforming workloads that traditionally bog down the system into streamlined processes. Improvements in performance for AI-SQL suggest that inference engineers should be attentive to these shifts. They can take advantage of controlled request environments to better manage resource utilization and minimize cache-related inefficiencies in transformer models. With the landscape of SQL-driven AI evolving rapidly, identifying and implementing these opportunities can significantly change the game for developers and engineers alike.### The Road Ahead: Optimizing Prefill-based Inference There's a growing conviction that the optimization of prefill-only inference holds transformative potential. This focus on enhancing the prefill phase could lead to significant performance improvements across various applications. Analyzing how separate processes can be effectively managed allows for striking efficiencies in computational tasks. One way forward is addressing the challenges associated with sampling, given that models presently operate on probabilities rather than generating discrete tokens. This aspect complicates the tracing of decisions made during inference, but it opens the door to innovative sampling strategies that could capitalize on this nuance—potentially increasing the accuracy of the models in real-time applications. The interest doesn't stop there—CUDA Graph capture may become a game-changing method. Prefills often last long enough that the launch overhead can be minimized, even on smaller models running on larger GPUs. By utilizing this hardware efficiently, developers can expect to push the boundaries of what’s feasible in model inference speed and latency. Moreover, speculative decoding stands to provide substantial acceleration, especially when more than one token is involved. This approach streamlines model output generation, making it not just quicker but also more resource-efficient. As we contemplate these advancements, it's clear that the focus needs to shift toward maximizing the distinct phases of inference. If you’re venturing into this space, consider how these refinements might influence the models you’re working with, and keep an eye on emerging methods that could further disrupt traditional paradigms. The future looks promising for those willing to innovate their approaches to inference optimization.