MAC
END
Empowering Engineers: Mastering Inference Performance in Software Development
- Gate
- Machine Learning
- Departs
- Crew
- William Miller
- Passengers
- 503
Discover essential insights for software engineers to optimize coding agents and enhance inference performance in the evolving technology landscape.
Understanding the Shift in Software Engineering
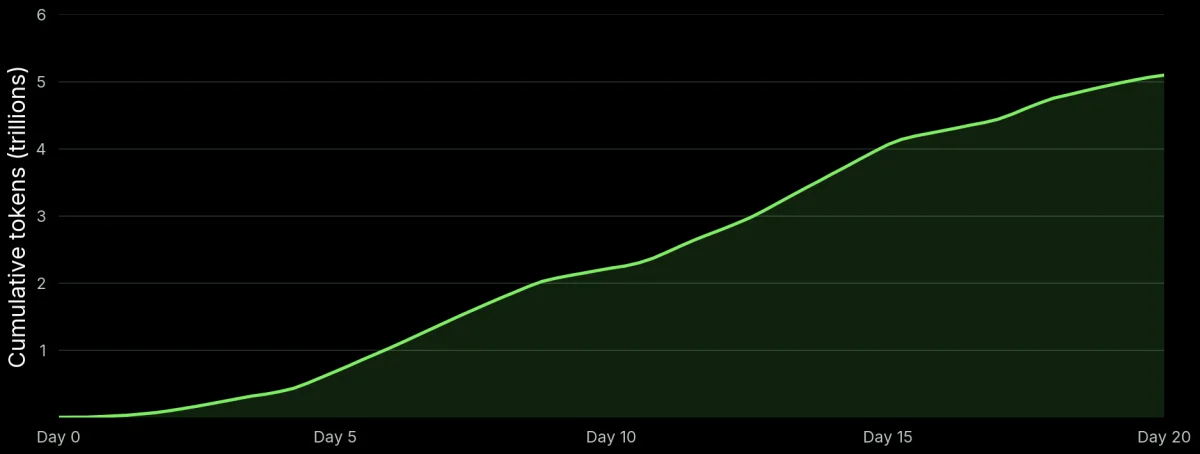
The impact of software is undeniable; it's rapidly reshaping entire sectors. With innovations in artificial intelligence and machine learning, we are witnessing a pivotal transformation in software engineering—namely, agents are beginning to take on roles traditionally reserved for human engineers. As these intelligent tools integrate deeper into workflows, software developers must grasp not only how to work with these agents but also the underlying mechanisms that drive their capabilities. This understanding is crucial, especially as computational inference is set to dominate resource allocation within the technology landscape. It's concerning that many engineers overlook how agent software utilizes inference powered by large generative language models. These engines require staggering amounts of processing power. In fact, inference services must operate with exceptional relative and absolute performance to be effective. Relative performance measures how much of a system's peak computing rate can be utilized efficiently. Absolute performance, on the other hand, refers to the sheer volume of tasks a system completes based on that processing capability. Any coding agent striving to function effectively will encounter the pressing need for extensive computational resources—potentially trillions of operations for a single input/output cycle. What’s intriguing here is the hardware landscape that underpins these inference services. Current high-performance hardware, specifically matrix math accelerators like Tensor Cores, can run at the petaFLOP level. Large-scale generative models possess an immense number of parameters, often measured in the trillions, which need to be accessed frequently even for individual queries. The nexus of these demands leads to a stark realization: economically viable coding inference services must process at scale, necessitating the handling of trillions of input-output tokens to justify infrastructure and engineering investments. At Modal, we’re operating at this exact scale, cultivating inference services that manage vast daily workloads. In our upcoming post, we aim to distill our experiences optimizing inference performance with models like Moonshot AI’s Kimi K2.6. Despite being several hundred days old in this fast-paced field, the principles guiding these systems retain relevance, with insights applicable even to newer models like Kimi K3. In sharing our journey, we hope to empower fellow engineers to effectively navigate this evolving landscape, sharpening their skills and optimizing their approaches to coding agents. We’ve refined our services to achieve marked performance improvements, offering significant gains for users. As we break down our strategies, you’ll witness how we processed hundreds of billions of tokens per day, aiming not only to enhance your understanding but also to support your efforts as you explore deploying similar high-performance inference services. In understanding these cutting-edge dynamics, developers are better equipped to adapt and thrive in an environment where intelligent agents and inference services swiftly reshape the realm of software engineering. If you’re working on integrating such systems, this is not just a technical shift; it’s a fundamental change in how we perceive the role of engineers in the software development process.Key Operations in Sequence Modeling
When handling requests in systems like Kimi, the process of executing multiple forward passes is critical. Every forward pass carries a significant computational cost, compelling us to optimize resource usage. To mitigate expenses, we batch several sequences together during these passes. This batching effectively spreads the computational load across multiple tokens, allowing for a more efficient processing pipeline. In addition, cross-token computations can be optimized by employing caching mechanisms, often referred to as **key-value caches** (KV caches). Despite the terminology, modern models such as Kimi don’t strictly use separate keys and values, yet the caching approach remains relevant to enhance performance. For a thorough breakdown of the numerical efficiency associated with these methods, you can refer to Kipply’s insightful [“Transformer Inference Arithmetic” blog post](https://kipp.ly/p/transformer-inference-arithmetic).Prefill vs. Decode: Understanding Their Roles
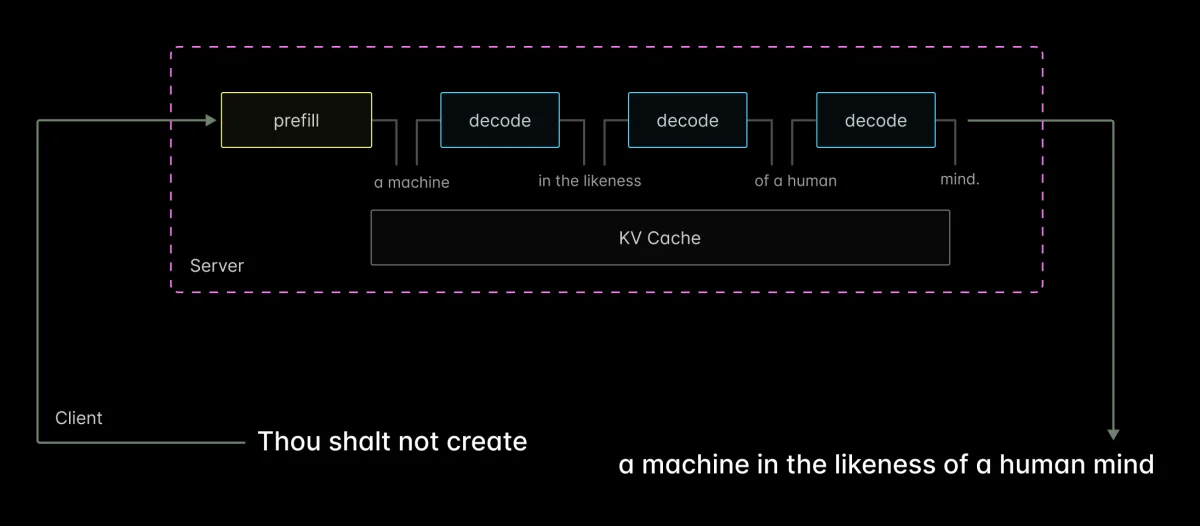
As we dive deeper into how these systems operate, it becomes essential to distinguish between two major functions during a forward pass. When we process input tokens, this is termed a **prefill**, as it populates the KV cache for future reference. Conversely, the output tokens generated in response to a user's query fall under the **decode** phase. This indicates a transition from processing the cached context to predicting new information based on past interactions. The performance of these stages is usually measured by latency and throughput metrics. **Time-to-first-token (TTFT)** gauges the latency incurred during prefilling, while **output tokens per second (TPS)** quantifies the rate of output generation. Both of these performance indicators can be tracked from the client’s perspective or server-side, which often leads to misinterpretations in the data.Examining Session Interactions
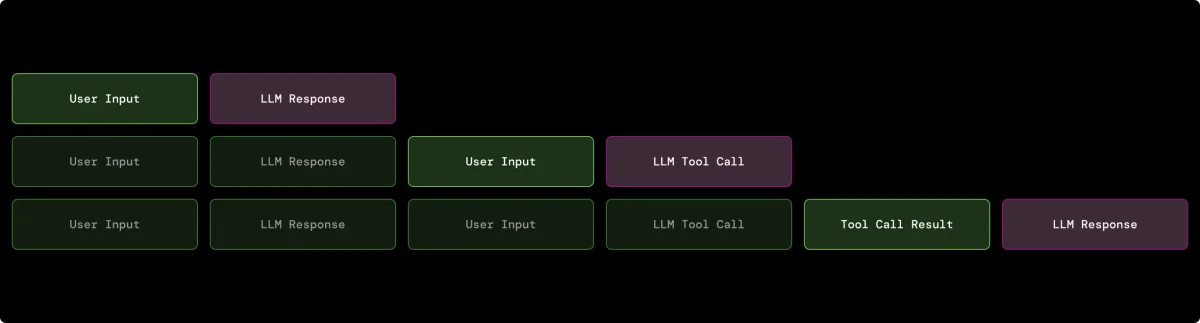
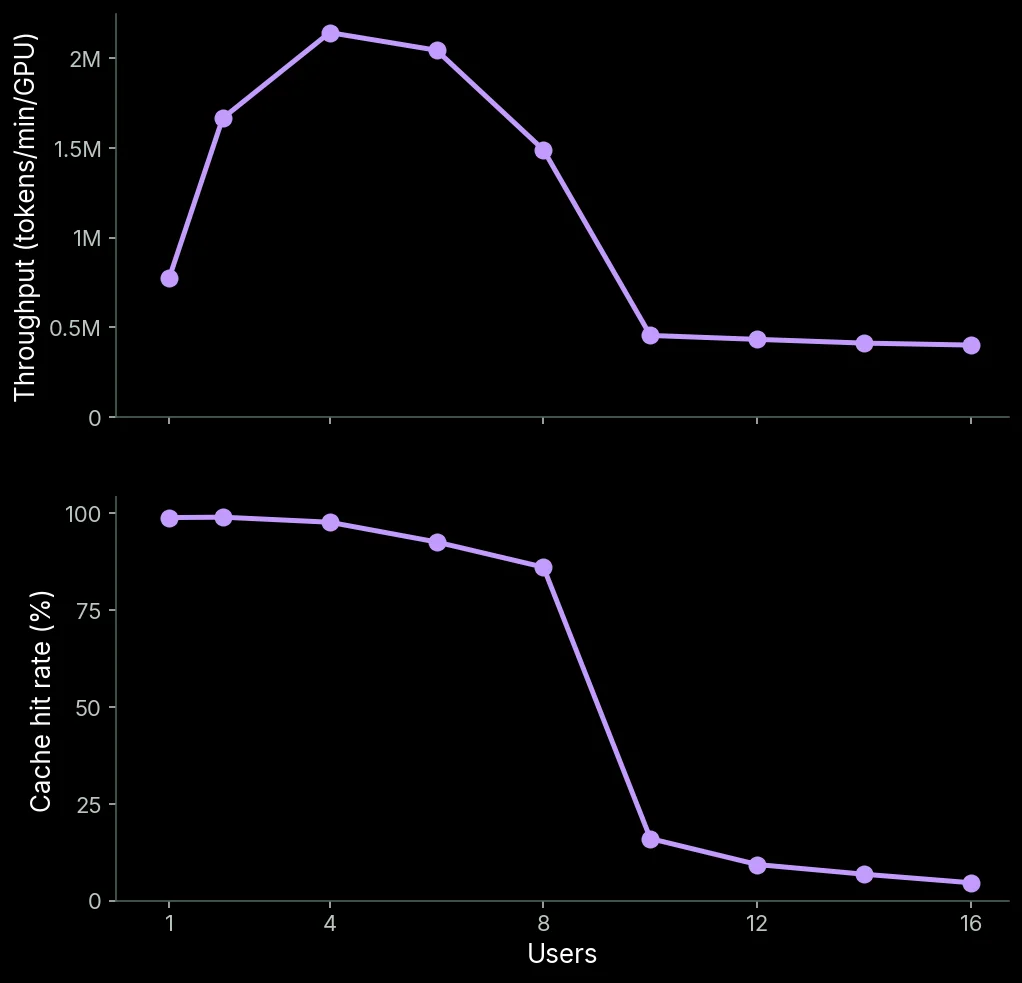
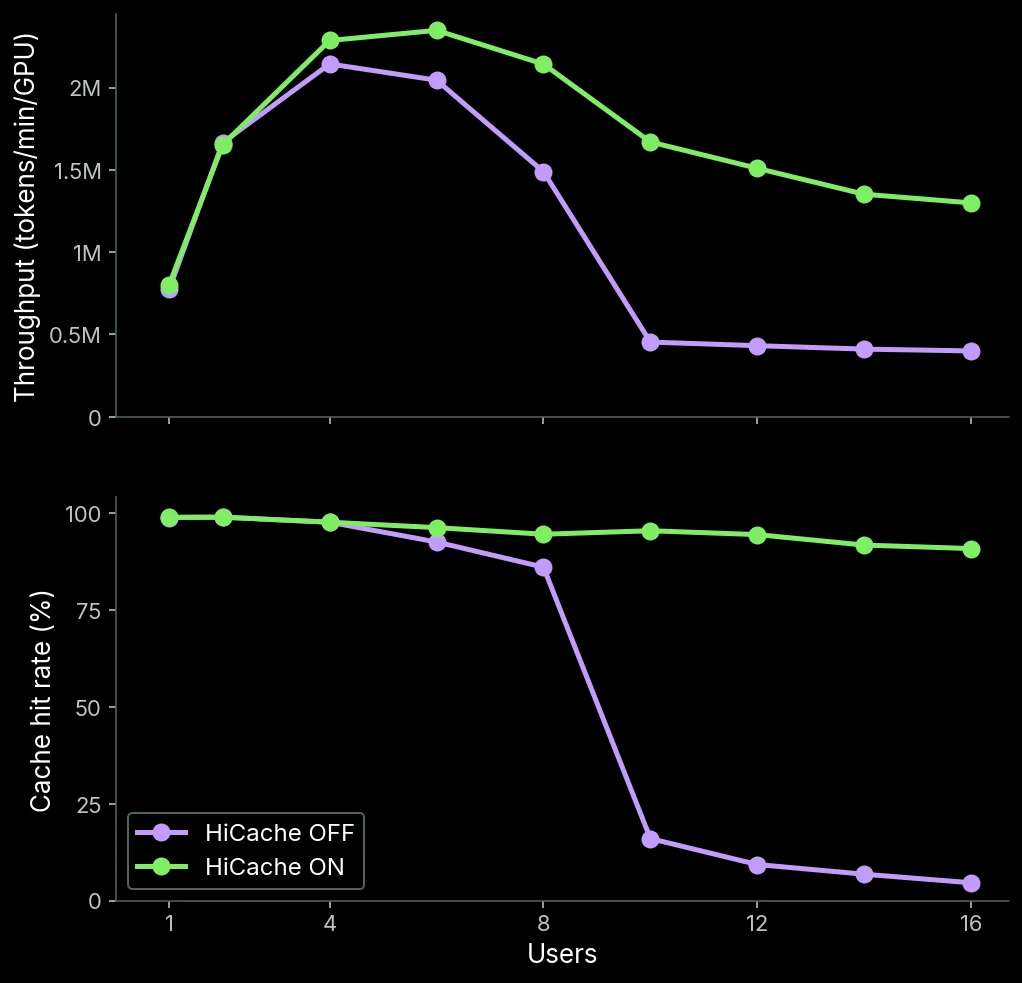
Individual processing requests often unfold within user defined **sessions**, where the interplay between users, generative models, and tool sequence calls creates a compounding effect on the system's input. This means that as more context accumulates throughout a session, both the meaning and value derived from each interaction become increasingly complex. A typical session's input includes not just the current turn’s content but also a history of prior exchanges. The implications are significant. Most requests consist of far longer input sequences compared to their resulting output. In a standard working model, this can lead to staggering ratios, with as much as 200 input tokens processed for every output token generated. Notably, for every turn in the interaction, previous tokens are repeatedly utilized, necessitating robust caching strategies to prevent unnecessary recomputation. Navigating these intricacies is essential for optimizing performance and addressing the core computational challenges models face in real-time applications.The Path Ahead: Maximizing Interactivity and Throughput
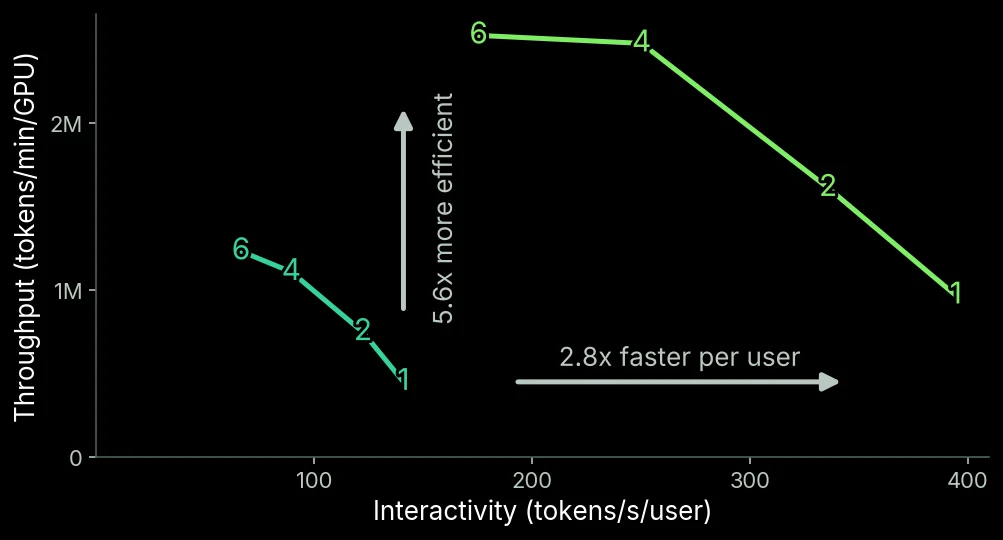
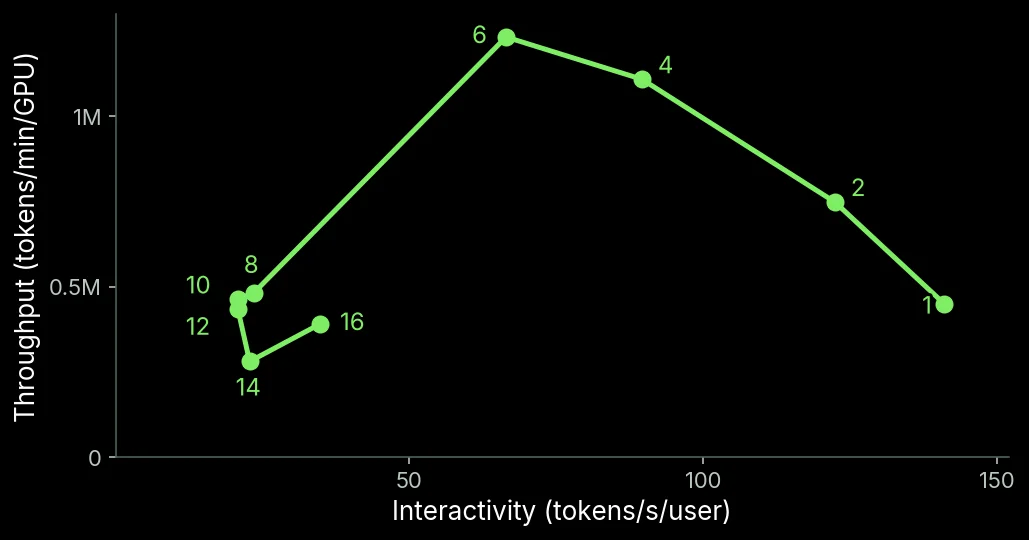
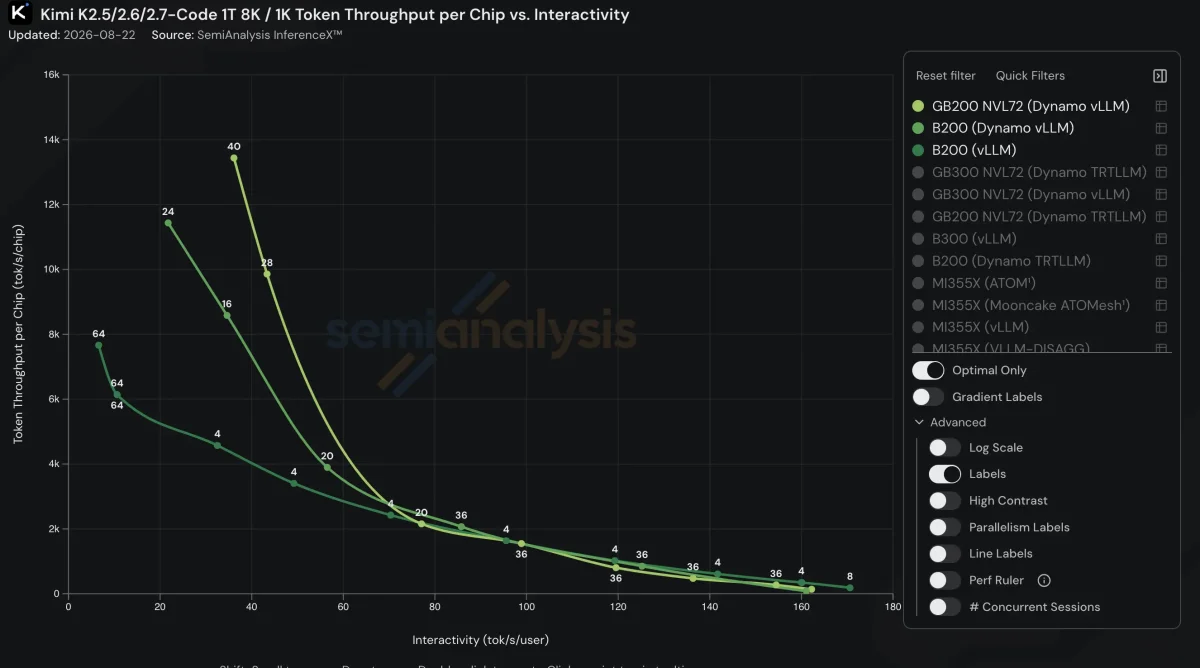
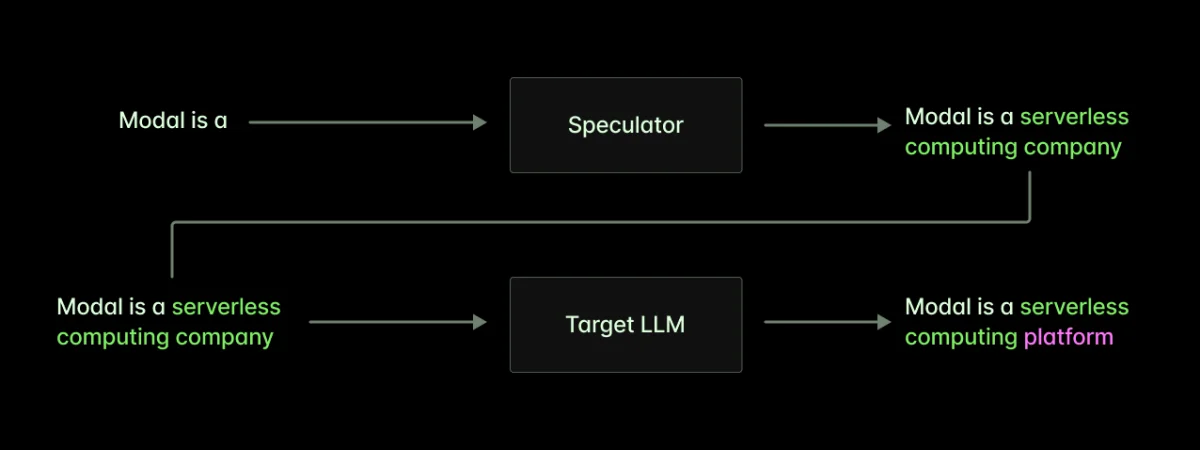
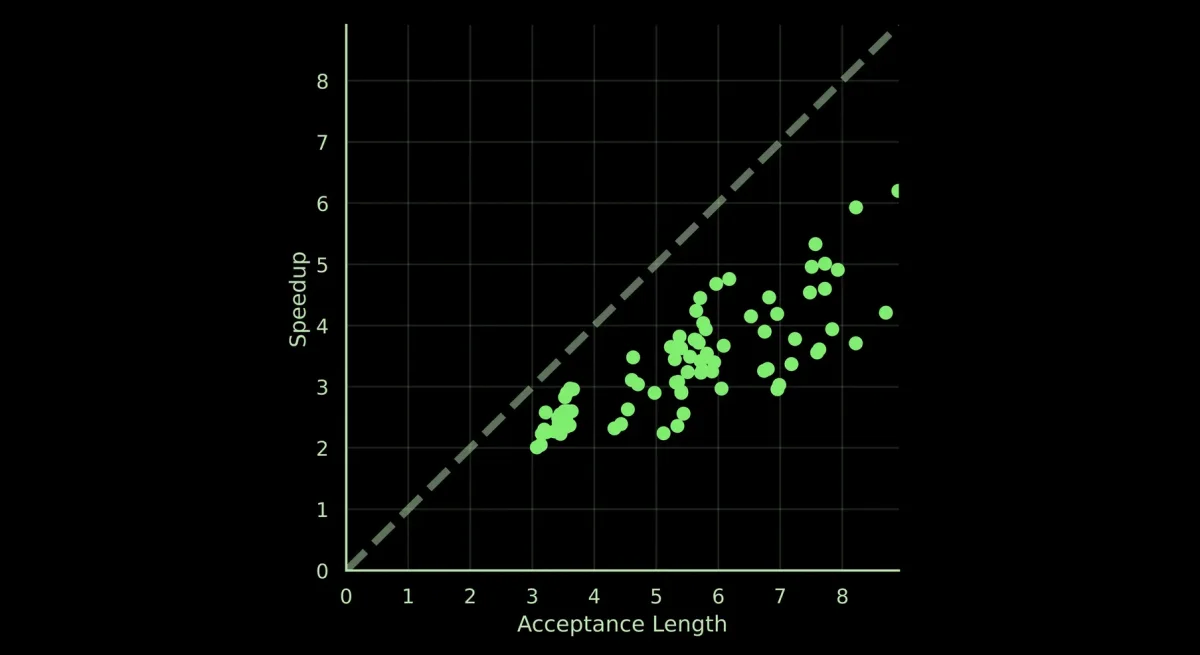
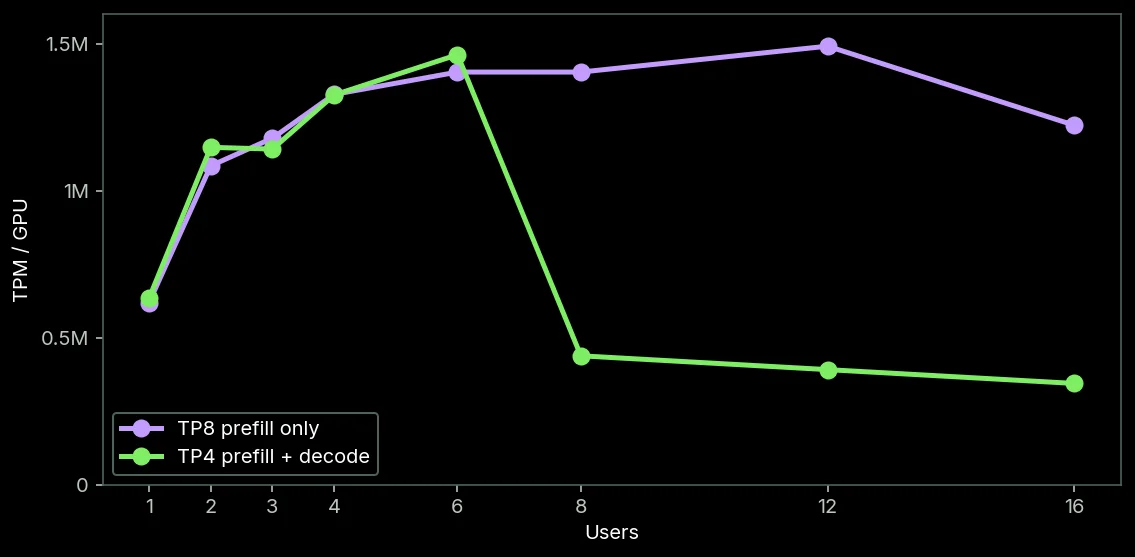
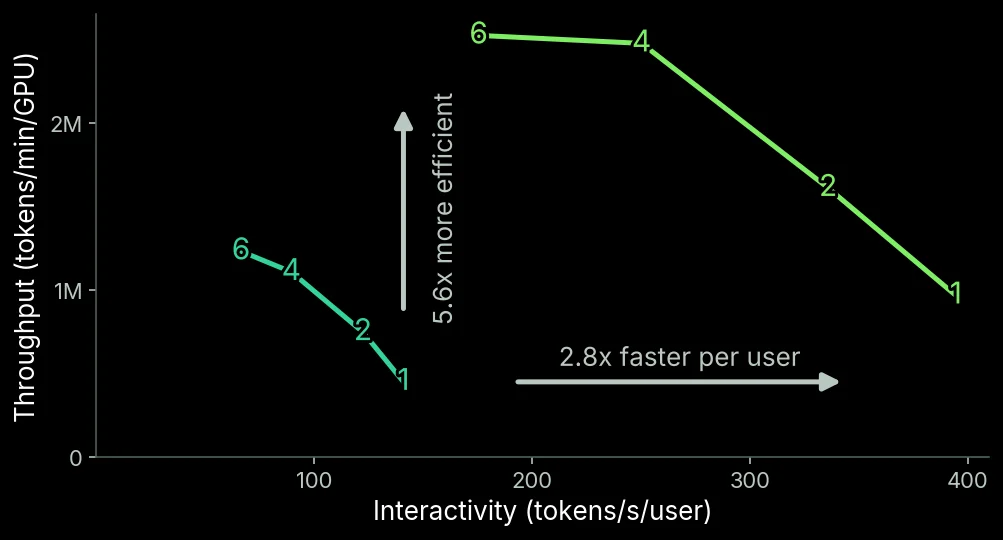
As we draw to a close, it’s clear that interactivity remains the cornerstone of user engagement in coding agent platforms. Improving response times not only enhances user satisfaction but also opens the door to better system performance across the board. If you're involved in the development or deployment of AI systems, you must understand that timely responses can dramatically shape user experiences and ultimately drive revenue. By focusing on interactivity early on, we made a critical choice that paid off: users value faster token responses and are willing to invest more for that speed. Prioritizing this aspect meant we could create a more appealing product without sacrificing performance. However, it’s not just about moving faster; it’s also about being smarter with computational resources. Our approach involved parallelizing computations and refining data handling processes like memory caching, which are both accessible and beneficial strategies. Here’s the interesting bit: implementing speculative decoding lets us accomplish more with each compute operation, essentially doing double duty when we encounter latency bottlenecks. That math adds up when you consider that interactivity can be optimized not just for individual requests, but also to maintain a steady flow of work across multiple nodes. This is where our autoscaling infrastructure shines—allowing us to respond flexibly to varying workloads while keeping operational costs manageable. However, it’s essential to recognize that achieving the right balance is tricky. While deploying larger configurations may seem appealing for peak performance, the drawbacks of communication overhead in multi-GPU setups often outweigh the benefits. We’ve seen that the ideal scenario often involves smaller clusters—eight GPUs or even fewer—where latency can be minimized without compromising throughput. As we look forward, the state of demand for compute resources remains fluid, and we’re ready to adapt our strategies accordingly. Should the landscape shift, whether in user expectations or technological capabilities, our commitment to delivering high interactivity while scaling effectively will guide us. Embracing these optimizations not only positions us for current success but also ensures we remain agile in a market that’s anything but static. In the end, the interplay of reduced latency and increased throughput isn't just a technical victory; it's a profound operational advantage that could define how responsibly we harness our computational abilities moving forward.