Optimizing Sandbox Startup Times: Understanding Latency Beyond Container Booting
- Gate
- Machine Learning
- Departs
- Crew
- Robert Johnson
- Passengers
- 832
Achieving faster sandbox user experiences requires addressing the entire startup lifecycle, from initial container booting to application readiness.
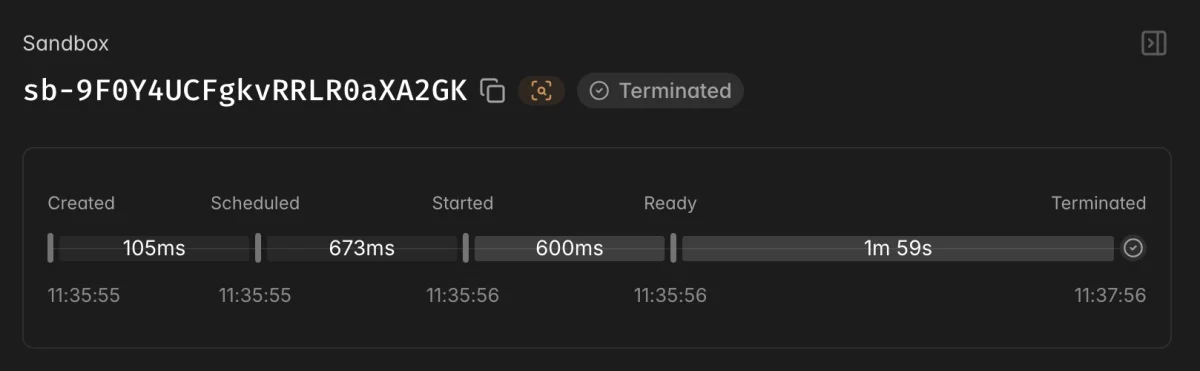
When discussing sandbox startup times, the most commonly quoted metrics are container scheduling and boot time. However, these figures often underestimate the true user experience, as the processes occurring after a container boots—such as cloning repositories or installing dependencies—often contribute significantly to wait times.
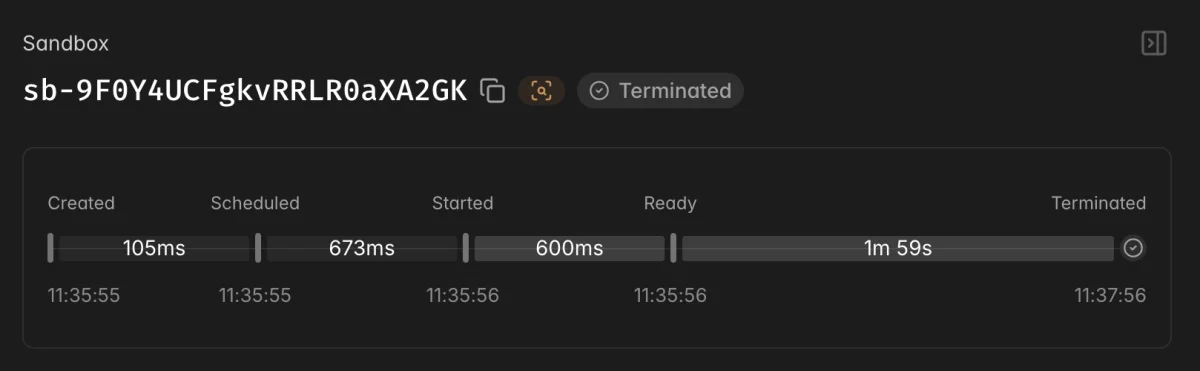
Efforts are being made to optimize the entire startup chain, focusing on both the components controlled by the service provider and the elements within user control. This involves understanding the full startup lifecycle, identifying areas for improvement, and offering tools that allow users to maintain healthy production systems. One such tool is Readiness Probes, which is now available to help users determine precisely when a sandbox has finished initializing.
The Full Startup Lifecycle
It's a common misconception that a sandbox is considered "running" as soon as its container is scheduled and booted. Various benchmarks, like those from ComputeSDK's sandbox leaderboard, often measure the time to interactive (TTI) from the creation of the sandbox to when the first command runs inside the container. Though this benchmark indicates the minimal performance a provider can achieve, it essentially represents just the beginning of the entire startup process.
At Modal, we categorize the startup process into several distinctive stages:
- Created: The sandbox has been requested, but resources are not yet allocated. On Modal, calling
Sandbox.createis asynchronous and returns immediately, adding negligible latency. - Scheduled: The sandbox is assigned to a worker, which provisions the necessary resources (CPU, memory, GPU, volumes) and prepares the container environment. Latency at this point depends on how quickly the provider can find the necessary capacity.
- Started: The container is live, the entrypoint process is running, and network tunnels and volume mounts are active. Users can now execute commands inside the container, and the latency here is primarily determined by actual container boot time.
- Ready: Application-level initialization is complete, and the sandbox can now perform work as intended. This step can often take several seconds, depending on the specific use case.
- In use: The sandbox is actively handling tasks.
The significant delay between the "Started" and "Ready" states is frequently overlooked in benchmarks, despite the fact that crucial application-level setup often precedes actual usability. During this interval, actions such as executing git pull to update code, performing bun install for dependencies, or starting an HTTP server can incur long wait times. Thus, the initial startup latency is often the smallest variable in the equation, while application-level setup times are more drawn out and the responsibility of the developer once the container is running.
This pattern holds for nearly all practical sandbox workloads. Whether for background coding agents requiring repository setups, or for computational training environments needing servers up and running, the core latency often comes from application setup, not container scheduling.
Decreasing Perceived Latency
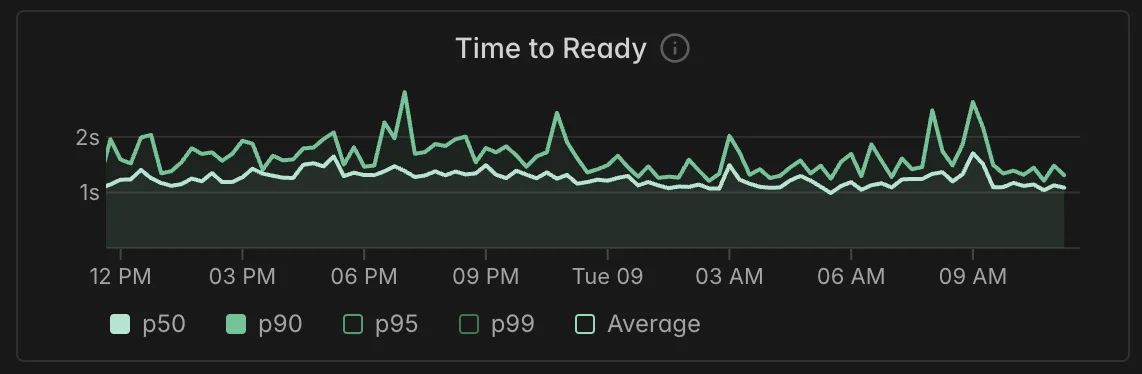
In practice, the application startup time far influences perceived user latency. For instance, when a sandbox is started on demand, if the total setup time spans 30 seconds, users directly experience a 30-second wait. Improving container boot time by a few hundred milliseconds may not make a meaningful impact; instead, effectively reducing the perceived wait time is critical. The solution to achieving this reduction lies in eliminating the delays associated with the startup lifecycle altogether.
Optimizing for Production Systems: Sandbox Pools
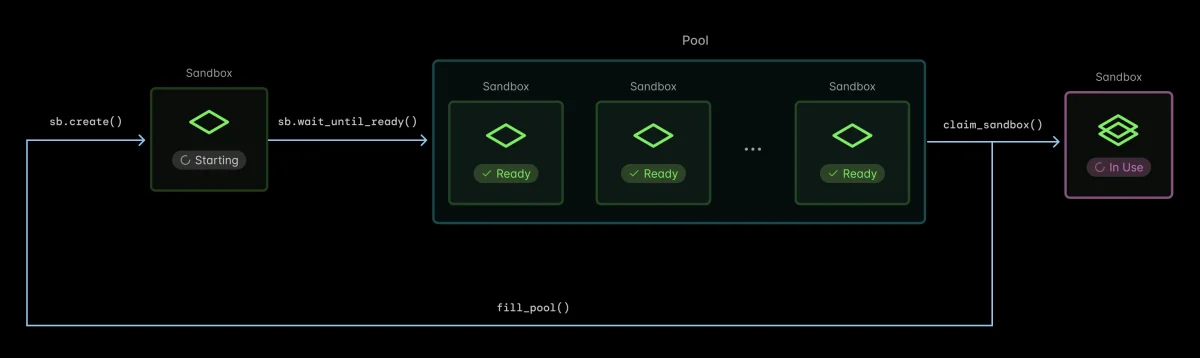
A practical strategy involves employing a warm pool of pre-initialized sandboxes. In this setup, sandboxes are pre-warmed in anticipation of requests, so when a user asks for one, they receive a sandbox that has already been through the startup logic, dramatically reducing perceived wait time to the act of merely fetching a sandbox from the pool.
Although some may dismiss warm pools as a workaround, our experience shows that latency-sensitive applications nearly always require one to address the initialization delays effectively. Since there will always be inherent setup costs that cannot be eliminated—such as executing git pull commands or dependency installations—paying these upfront helps keep them from affecting the user's experience during crucial transactions.
In practice, Modal uses a Sandbox pool that leverages a modal.Queue to hold references to pre-warmed sandboxes. A background producer is responsible for creating these sandboxes, executing application setup, and pushing completed sandboxes into the queue. When an application requests one, it retrieves a pre-warmed sandbox and immediately starts creating a replacement to ensure the pool's continued availability.
However, it's important to note that pre-warming sandboxes is inherently generic, as they are created without knowing which user or project will utilize them. To account for project-specific requirements, Modal implements Directory Snapshots, allowing for the mounting of a project's specific state into a running sandbox without rebuilding the environment, thus combining the advantages of warm pools with the necessary project customizations.
Readiness Probes
Another consideration with warm pools is determining the readiness of a sandbox before distribution. One could guess the duration of initialization based on previous experiences and add arbitrary sleep times, but this method is unreliable due to varying setup times. Instead, Modal introduces Readiness Probes, which can be defined when a sandbox is created. Users can specify a TCP port expected to accept connections or a command that should return a success exit code. The sandbox.wait_until_ready() method blocks execution until readiness conditions are satisfied.
This simplicity also aids in immediate usage; using wait_until_ready() ensures that application logic remains clean and streamlined throughout the startup process.
Observability for Production Systems
Modal has incorporated various metrics and observability tools for users to overview their sandbox operations, including readiness tracking. When setting up a probe, Modal visualizes the readiness timeline within the dashboard, providing insights into when the sandbox crossed the readiness threshold in relation to when it was scheduled and started. This comprehensive view aids in understanding delays as developers can analyze application-specific latencies more effectively.
Overall, the introduction of readiness probes and warm pools is available today. By leveraging wait_until_ready() and tracking readiness events on the dashboard, users can optimize their sandboxes while decreasing perceived latency significantly. For a full implementation with tracking and maintenance, users are encouraged to check out the warm pool examples.


