MAC
END
Unlocking AI Efficiency: How Speculative Decoding Enhances Model Performance
- Gate
- Machine Learning
- Departs
- Crew
- Robert Garcia
- Passengers
- 614
Speculative decoding boosts AI model performance, delivering significant speed improvements and better handling of long-context tasks for practical applications.
Why We’re Committed to Speculative Decoding
At the forefront of our AI advancements is our unwavering belief in speculative decoding. This approach is not just a tactical choice but a fundamental strategy for optimizing model performance. The rationale behind this commitment is rooted in our recent partnership with Z Lab, which has amplified our capabilities, particularly in the development of sophisticated draft models. Among these innovations is our DFlash speculator, designed to significantly enhance inference processes. This week, we are excited to announce the release of new models within the Qwen series, optimized for performance on the Hugging Face platform. Our collaboration with SGLang has been pivotal in ensuring that these speculators push the envelope in terms of speed and efficiency. The models set for release include: - [Qwen 3.6 35B-A3B-DFlash](https://huggingface.co/modal-labs/Qwen3.6-35B-A3B-DFlash) - [Qwen 3.5 4B-DFlash](https://huggingface.co/modal-labs/Qwen3.5-4B-DFlash) - [Qwen 3.5 9B-DFlash](https://huggingface.co/modal-labs/Qwen3.5-9B-DFlash) - [Qwen 3.5 27B-DFlash](https://huggingface.co/modal-labs/Qwen3.5-27B-DFlash) - [Qwen 3.5 35B-A3B-DFlash](https://huggingface.co/modal-labs/Qwen3.5-35B-A3B-DFlash) - [Qwen 3.5 122B-A10B-DFlash](https://huggingface.co/modal-labs/Qwen3.5-122B-A10B-DFlash) These models build on the already impressive capabilities of earlier DFlash speculators, achieving a substantial speed improvement of 5 to 20% across a variety of workloads. For instance, the Qwen 3.5 122B-A10B model now boasts a performance of over 1000 tokens per second at concurrency 1 on a B200 node, a dramatic increase from the 250 tokens per second when inference was conducted without speculation. You can explore the specifics of these performance metrics further through our [token timing simulator](https://modal.com/llm-almanac/token-timing-simulator). Moreover, these newly trained draft models excel in long-context tasks, such as software engineering tasks that require advanced reasoning over extended dialogues. They not only process information more quickly but also maintain accuracy and coherence over longer stretches of output. Our enthusiasm for speculative decoding stems from its potential to transform LLM inference – it's not merely an enhancement but rather a vital component that informs our continuous improvement strategy for AI applications. While there’s an abundance of optimization techniques out there, speculative decoding stands out as the key player in boosting operational efficiency and responsiveness in AI systems. When executed correctly, speculative decoding proves to be far more effective than traditional optimization techniques, yielding exponential speed-ups instead of marginal percentage gains. As we dive deeper into the myriad benefits of incorporating this technique, we invite you to keep reading to discover why it’s such a pivotal element in the future of AI model performance.Understanding Speculative Decoding Mechanics
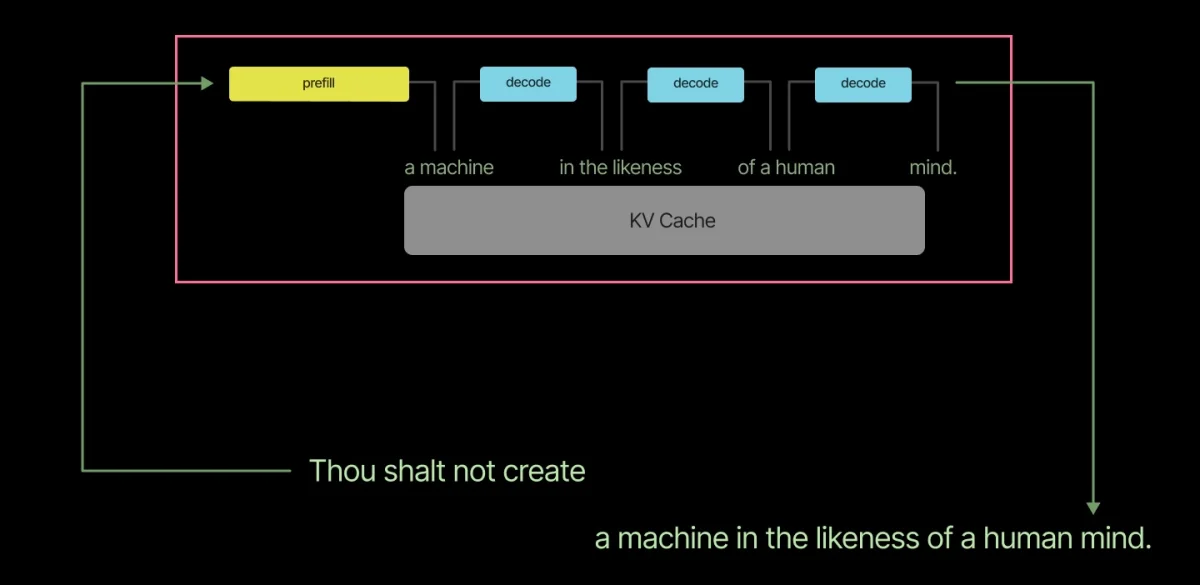
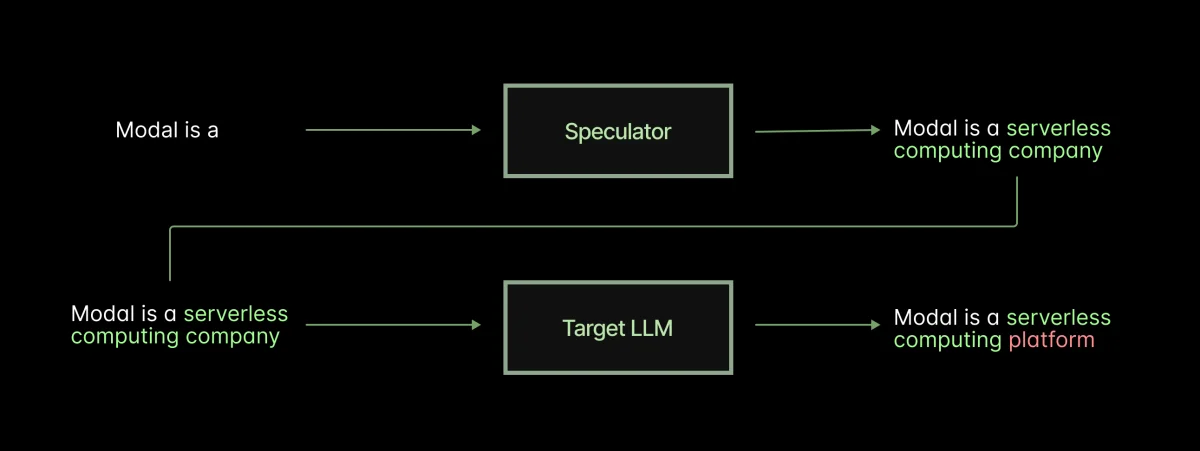
Speculative decoding offers a revolutionary approach driven by a straightforward principle: when sequential execution proves inefficient, parallel processing of potentially discarded computations becomes advantageous. This concept draws a parallel to speculative execution in microprocessors, where the costs of linear execution can mitigate the benefits of performing additional operations that may ultimately not be needed. During the decoding process, each pass mirrors a database’s sequential scan. You engage with substantial data—often gigabytes of active weights—from the GPU memory, similar to retrieving an entire table during a database query. The essence of speculative decoding then resonates with the eager construction of materialized views in databases. While this involves preparatory work that might go unused, data bandwidth limitations mean that expended efforts often have negligible marginal costs. However, a pivotal challenge arises in the formation of the speculator model. Initial attempts, such as using traditional machine learning frameworks like an n-gram model, resulted in low acceptance rates of token predictions. Conversely, utilizing another neural network for this purpose escalated drafting costs. Both strategies stifled the anticipated acceleration from speculation. Modern architectures, such as MTP and EAGLE-3, accordingly harness speculators that capitalize on prior computations from the main model, effectively leveraging its historical inference efforts. These newly devised speculator models are not just lightweight; they achieve high acceptance lengths with relative ease during training. But let's not underestimate the implications of the term "relative." In the realm of machine learning, managing these projects can prove to be a substantial challenge, often fraught with obstacles that lead to project failures. Fortunately, the majority of these complications don’t stem from the speculator’s training itself, rendering it more manageable compared to the broader ML landscape.The Advantages of Speculator Training
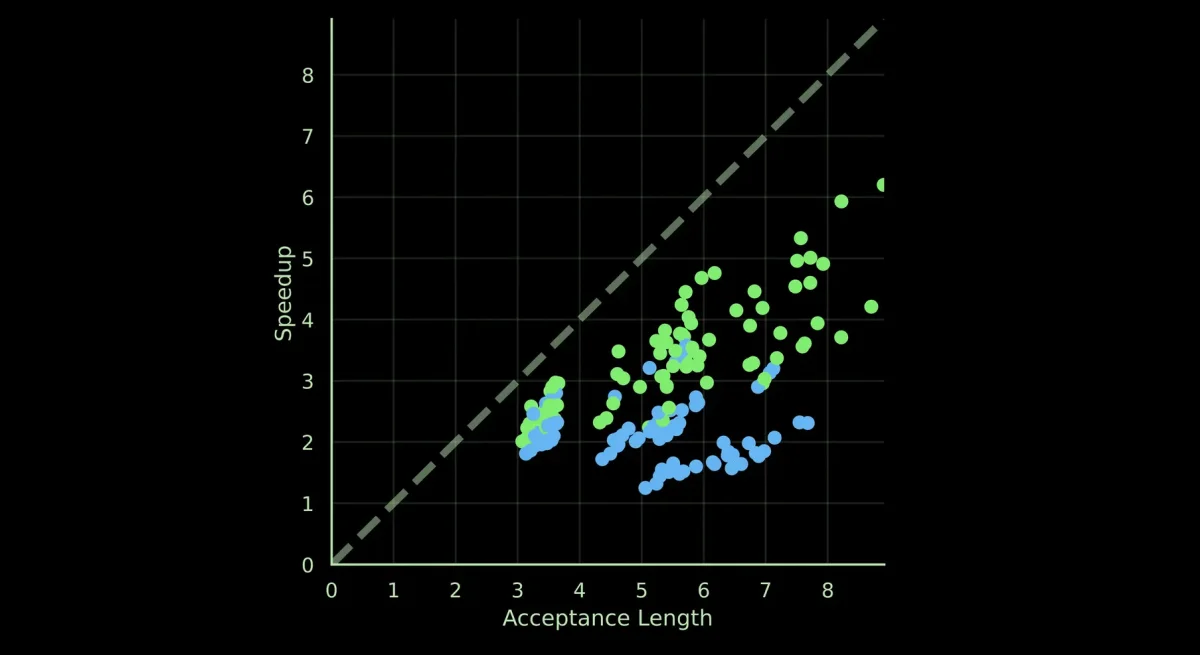
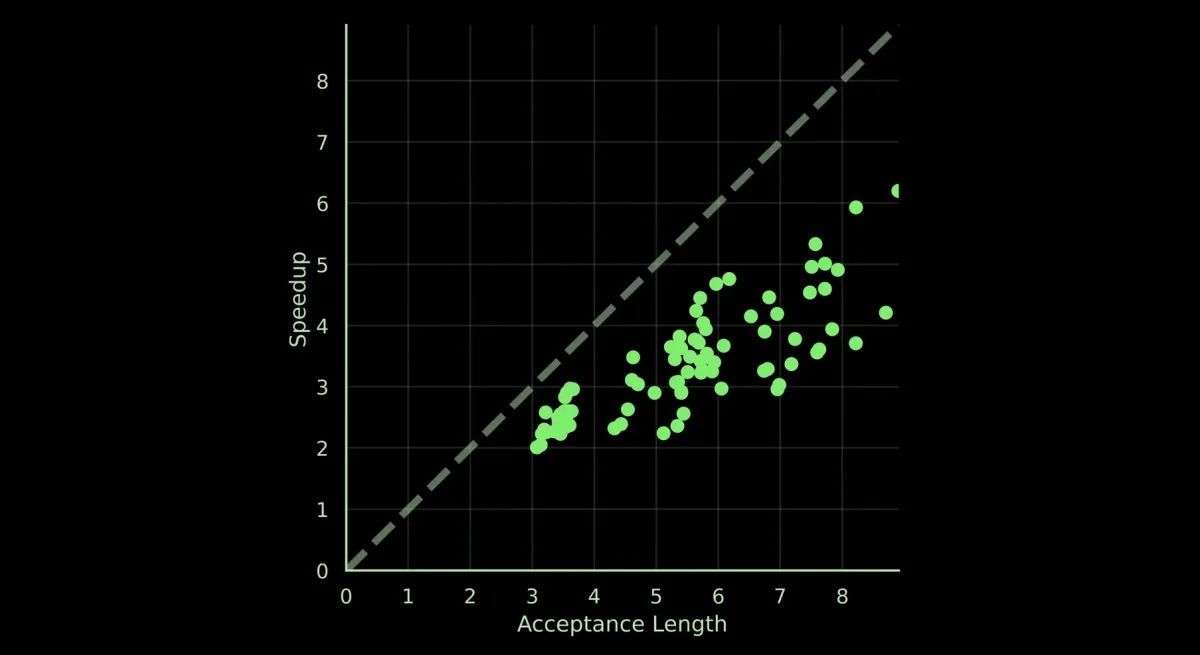
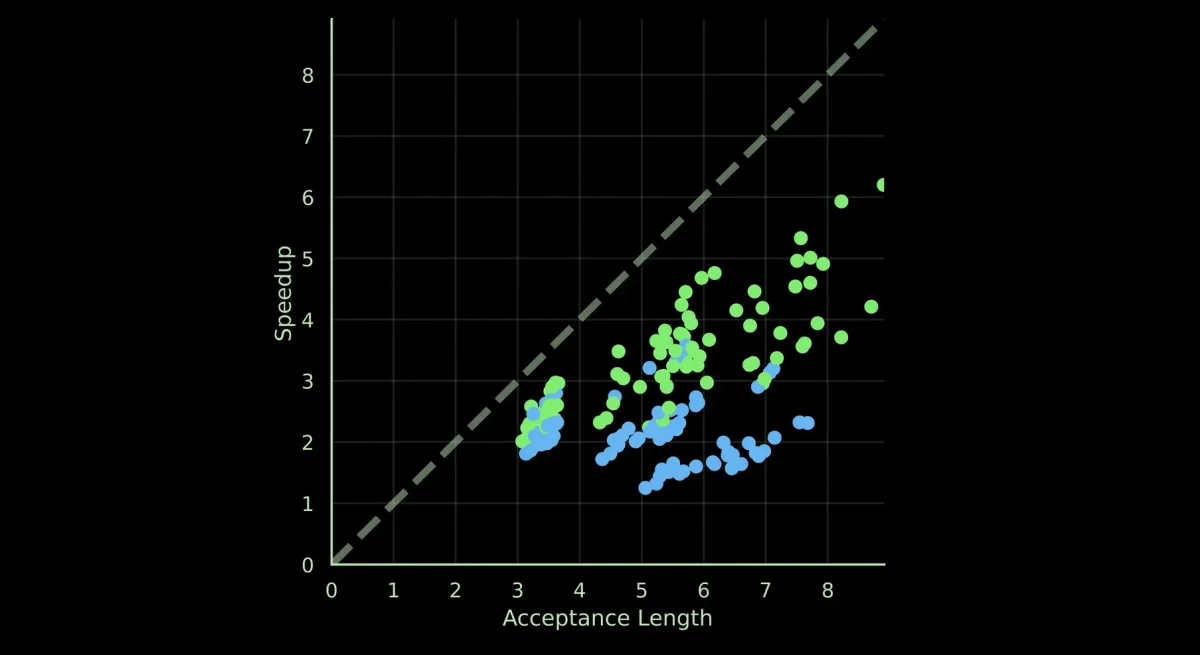
Training these speculators can be likened to ML on simplified settings. Essentially, we’re creating a machine designed to imitate a process generating data from another ML model. Since you're replicating a known source, data generation becomes straightforward, allowing for immediate reshaping and usage without needing extensive reassignments or re-engineering efforts. This streamlined data availability removes the common hurdles that plague many machine learning endeavors, especially those related to data scarcity or collection logistics. Because the target model also serves as the data generator, you have a direct measure of the training's effectiveness—namely, the acceptance rate and the corresponding inference speedups. While establishing the necessary infrastructure for machine learning is notoriously tough, the silver lining here is that leveraging existing knowledge allows for quicker development cycles. For instance, utilizing Modal’s autoscaling functionality can boost training speeds dramatically, facilitating that much-desired leap in performance. A customized speculator can notably enhance acceptance lengths and thus impact overall speedup on large datasets drawn from real-world application scenarios, typically generating tens of thousands to hundreds of thousands of tokens. Observations indicate that fine-tuned models can elevate acceptance lengths from a mere 3 to an impressive 9. Such an improvement translates to more than just an incremental performance boost; it could mean transitioning from a 25% speed increase to potential threefold performance gains. These outcomes highlight why focusing on acceptance length is paramount when optimizing speculative decoding frameworks.Insights on Speedup from Speculative Decoding
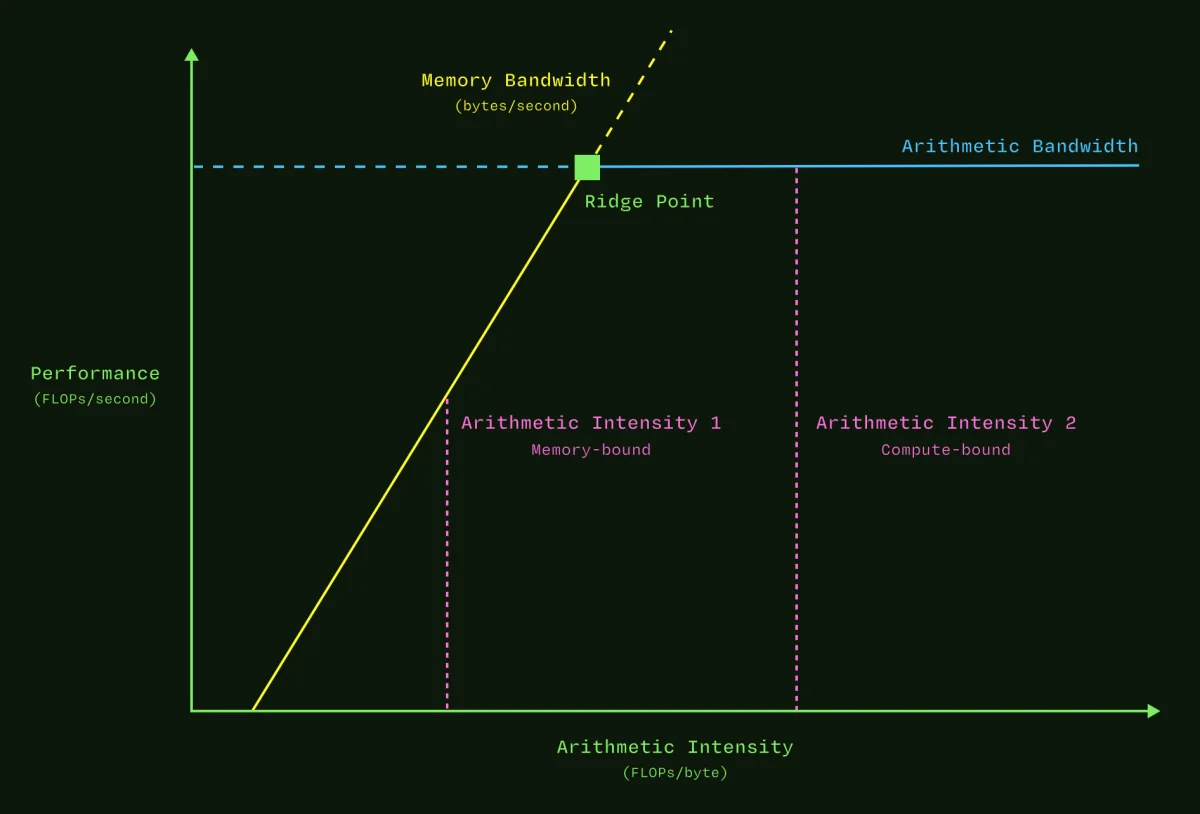
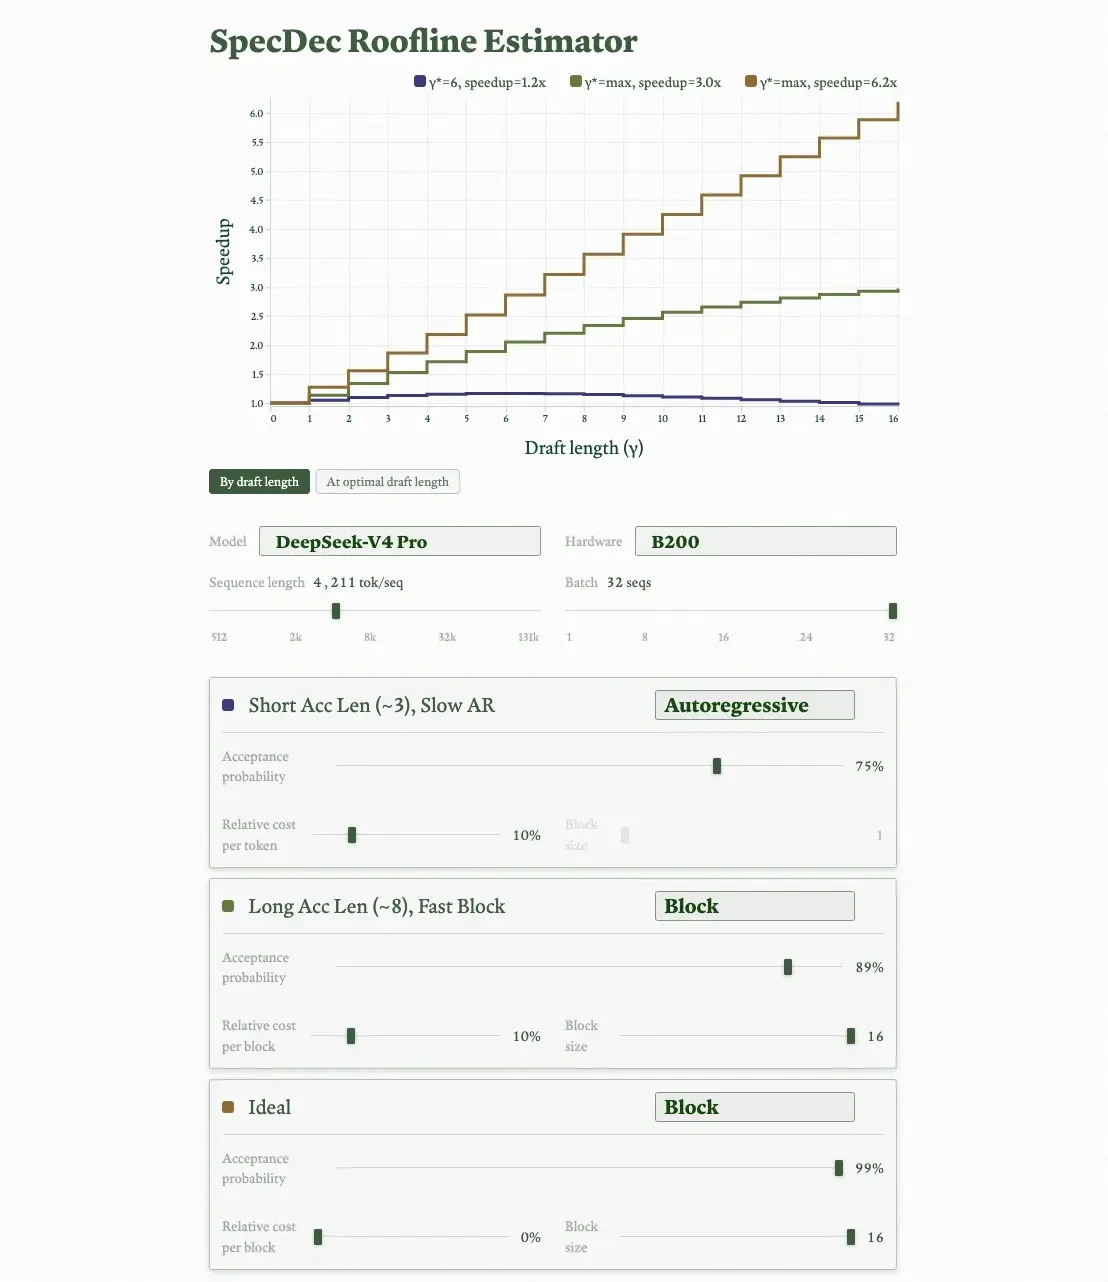
Understanding the parameters influencing performance in speculative decoding is essential, especially as we look ahead into more complex models and applications. The data presented earlier indicated a fascinating relationship between acceptance length and decoding speed—substantial speedups were observed as the acceptance length increased. This trend, however, does not necessarily translate into a straightforward method for predicting performance gains across all use cases. A simple model reveals that the speed of decoding appears to align closely with the acceptance length. In fact, we can boil it down to a basic formula: the expected speedup is directly proportional to the number of accepted tokens. This might sound overly simplistic, but it provides a useful rule of thumb to gauge potential efficiency gains as indicated in our findings. Yet here's where the complexity kicks in: while our estimates show a commendable trend, they often overstate the actual performance improvements. This discrepancy arises from several assumptions we've made. For example, we initially assumed that draft tokens impose no additional latency, and equally that the speculative decoding passes operate without adding any overhead. These are favorable assumptions, and the reality may not hold true across all scenarios. To move towards a more accurate assessment, we must refine our model with respect to latency—and consider factors such as the balance between computation and memory transfers. Speculative decoding gains are likely to diminish under real-world constraints where these ideal conditions don’t hold.The Path Forward
As we refine our approach, it’s crucial to adopt a more nuanced perspective. The models we discussed are not just academic exercises; they have significant implications for any organization looking to integrate these techniques into their product offerings. If you're immersed in the research or development of adaptive systems, consider these insights as a roadmap. While speculative decoding has the potential to revolutionize how rapid inference is conducted, your implementations will need to account for the nuances and limitations we’ve outlined. The journey doesn't end with understanding speedup metrics. Future work will involve dismantling our oversimplified assumptions and incorporating more granular performance modeling—this will enable us to paint a clearer picture of the practical benefits and constraints of employing speculative decoding in real-world applications. In essence, as much as the prospect of speedup from acceptance length excites the imagination, the road forward is paved with the need for rigorous testing and more sophisticated modeling to ensure we harness the true potential of these developing techniques.