Challenges of Reinforcement Learning Infrastructure and Optimal Solutions
- Gate
- Machine Learning
- Departs
- Crew
- Joseph Garcia
- Passengers
- 701
This article examines the critical infrastructure challenges faced in reinforcement learning (RL) training and presents strategic solutions to optimize performance.
Reinforcement Learning (RL) in the context of post-training large language models (LLMs) has surged in popularity, particularly within the Modal framework. Modal has effectively assisted both research teams and established enterprises in developing training systems that optimize cost-performance measures on foundation models. A significant realization from this widespread application is that the prevailing bottleneck in RL is largely attributed to infrastructural limitations.
In this piece, we share insights gained from executing RL post-training at scale, highlighting the technical and infrastructural facets critical for effective implementation.
The Shape of the Problem
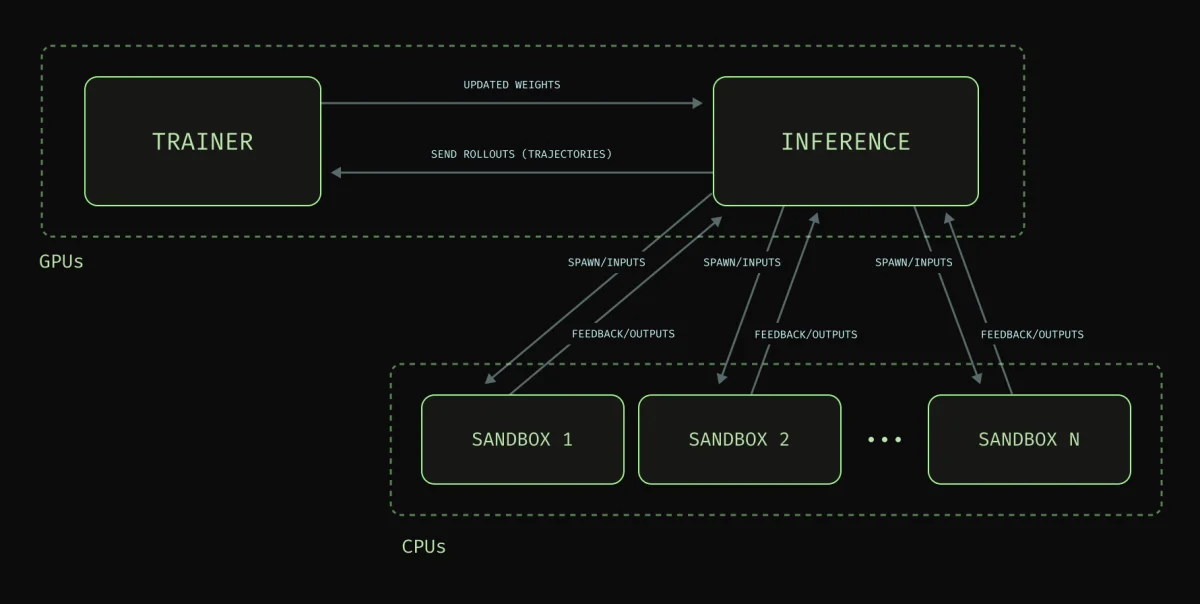
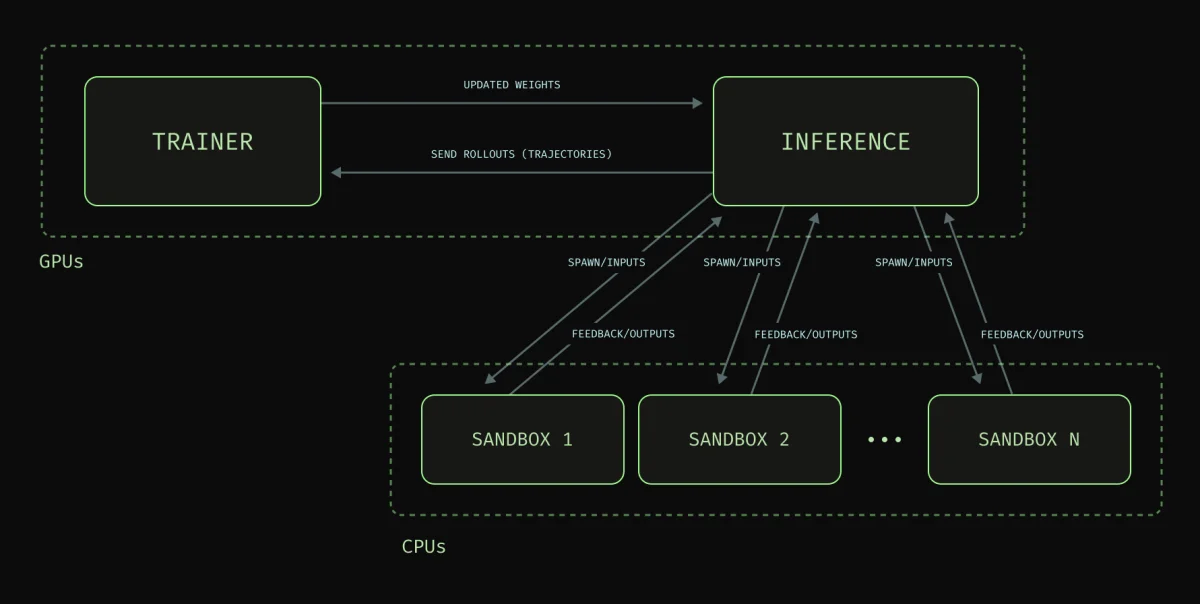
The RL training loop can be segmented into three essential components, each representing distinct and independently challenging infrastructural issues:
- Training: This component requires an engine capable of executing forward passes, backward passes, and weight updates reliably at the massive scale of advanced foundation models, which range from billions to trillions of parameters.
- Rollouts: High-performance inference engines are needed to conduct rollouts quickly, serving large models at near-light speeds, whether it's on a single GPU card or across many.
- Isolated Environments: The model policies must transform into actions simultaneously at a steady rate that aligns with the rollouts, requiring thousands to millions of containers working in parallel.
Recent Developments: Going Multi-Node
Adoption of fine-tuning open-weight models has reached a new phase where teams are deploying AI solutions to production instead of merely creating demonstrations for executive presentations. This transition comes as many products are maturing quickly. However, it's noteworthy that the total token costs for proprietary models are either flat or increasing, mainly due to growing test-time compute requirements.
Organizations from NVIDIA to Google have been releasing effective models under permissive licenses, pushing the envelope even further. While smaller models maintain significant fine-tuning potential, larger models are better suited for complex tasks, offering enhanced capability ceilings and improved data efficiency alongside reduced instances of catastrophic forgetting. Nevertheless, the price for their advantages includes increased VRAM requirements for allocating weights, gradients, optimizer states, and KV caches.
As training shifts to multiple GPU nodes, the synchronization of weights between the trainer and the rollout engine emerges as the primary bottleneck. Techniques like Low-Rank Adaptation (LoRA), asynchronous RL implementations, and colocated trainer-rollout systems significantly reduce pressure but introduce their own trade-offs. In many scenarios, maintaining a training cluster incurs substantial costs, as per idling computational resources, teams often face the dilemma of paying considerable amounts for every second wasted.
Efficiency Gains through RDMA
Utilizing Remote Direct Memory Access (RDMA) can drastically improve transfer speeds within a cluster by up to 100 times. The following table illustrates the disparities between transfer speeds using TCP versus RDMA:
| Model | Size of Weight Update | Transfer Speed (NCCL over TCP) | Transfer Speed (NCCL over RDMA) | Reference GPU Count | Estimated Cost Savings per Training Step |
|---|---|---|---|---|---|
| Qwen3 8B | 16.3 GB (BF16) | 2.62 s | 41 ms | 1x8 H100 | $0.21 |
| Qwen3-30B-A3B | 61.1 GB (BF16) | 9.78 s | 153 ms | 1x8 H100 | $0.77 |
| Qwen3-30B-A3B LoRA (r=32, shared-outer) | 1.0 GB (BF16) | 160 ms | 2.5 ms | 1x8 H100 | $0.013 |
| GLM 4.7 | 716.7 GB (BF16) | 114.67 s | 1.79 s | 4x8 B200 | $36.12 |
| GLM 4.7 LoRA (r=32, shared-outer) | 4.7 GB (BF16) | 752 ms | 11.75 ms | 4x8 B200 | $0.24 |
| Kimi K2.6 | 595.2 GB (INT4 MoE / BF16 attn) | 95.23 s | 1.49 s | 16x8 H200 | $119.99 |
| Kimi K2.6 LoRA (r=32, shared-outer) | 9.4 GB (BF16) | 1.50 s | 23.5 ms | 16x8 H200 | $1.90 |
| Kimi K2.6 LoRA (r=32, per-expert) | 41.0 GB (BF16) | 6.56 s | 102.5 ms | 16x8 H200 | $8.27 |
Note: This data assumes a bandwidth of 50 Gbps over TCP and 3.2 Tbps over RDMA. Such improvements can significantly enhance the efficiency of rollouts and synchronized updates.
Using delta compression can further streamline the process, allowing weight updates over RDMA to take less time. For instance, consider the time it takes to transfer full weights versus using delta compression:
| Model | Size | Full Weights Transfer Time | Delta Compression |
|---|---|---|---|
| Qwen3 8B | 16 GB (BF16) | 12.8 s | 0.26 s |
| Qwen3 30B-A3B | 60 GB (BF16) | 48 s | 0.96 s |
| GLM 4.7 (~355B) | 357 GB (BF16) | 285.6 s | 5.73 s |
| Kimi K2.6 (~1T) | 595.2 GB (INT4, MoE / BF16 attn) | 480 s | 9.6 s |
This assumes a transfer speed of 10 Gbps over a WAN internet, with delta compression significantly reducing the weight update magnitude by up to 98%.
Common Roadblocks for Teams
Throughout our analysis, several common issues have emerged that hinder teams in deploying RL methodologies:
- Maintaining Glue Code: Setting up an effective training environment necessitates intricate management of infrastructure, leading to an increasing amount of training code devolving into mere glue code or YAML configuration files.
- Queueing for Cluster Time: Shortages in available computational resources result in prolonged waits for job execution, which can compound inefficiencies when mistakes occur during configurations.
- Under-utilizing GPUs: A properly sized sandbox buffer and environment configuration is crucial; otherwise, many GPUs can remain idle, leading to inefficiencies.
These complexities are less frequently discussed in standard RL literature but are critical for any team striving to leverage advanced RL techniques effectively. All of these roadblocks can be alleviated by enhancing infrastructural capabilities.
Maintaining Glue
Constructing a reliable training setup requires substantial infrastructure management. As a result, a considerable portion of your code could transform into glue code, complicating maintenance. Teams face questions regarding the sourcing and preparation of trainer nodes, the establishment of training frameworks, and their interactions within the overall architecture of the RL training setup—all while managing crashes in rollout environments.
Modal provides solutions that bundle both code and infrastructure. It allows users to set up an RDMA-connected and GPU-accelerated training cluster with built-in observability and fault tolerance, streamlining the process considerably. A simple snippet of code accomplishes this:
import modal.experimental

@app.function(
    gpu="H100:8",
    timeout=60 * 60 * 24,
    retries=modal.Retries(initial_delay=0.0, max_retries=10),
)
@modal.experimental.clustered(size=4, rdma=True)
def train_model():
    cluster_info = modal.experimental.get_cluster_info()
    container_rank = cluster_info.rank
    world_size = len(cluster_info.container_ips)
    main_addr = cluster_info.container_ips[0]
    is_main = "(main)" if container_rank == 0 else ""
    print(f"{container_rank=} {is_main} {world_size=} {main_addr=}")
    ...
By invoking just the rdma=True option, you abstract away a substantial amount of infrastructural complexity. As Edsger W. Dijkstra aptly stated, the purpose of abstractions is not to create vague formulas but to empower precise operations in complex systems.
Queueing for Cluster Time
Having an adequate infrastructure code is just the beginning of executing training runs. The current environment operates under a compute shortage that is widely recognized in the industry. The need to ensure every training job is queued efficiently without wasting time is paramount to maintaining engineering velocity. Troubles with configuring the environment correctly can lead to immediate failures when attempting to execute a job.
Modal’s infrastructure is designed to handle these issues efficiently. Users can benefit from highly optimized resource allocation methods, enabling them to scale training effectively.
Underutilizing GPUs
Even with the right infrastructure in place, teams can encounter delays if the training environments are not properly configured to feed GPUs adequately. Each GPU must operate to its fullest capacity. This entails accurately sizing the sandbox buffer to ensure a seamless connection. Too many idle resources or too few active environments can catastrophically impact training performance. The Modal platform’s sandboxes are capable of rapid startup times, enabling optimal resource utilization.
Open Source Commitment
Many successful RL implementations originate from open-source training frameworks like Slime, Miles, and OpenRLHF. These platforms are validated at large scales through rigorous testing and analysis. They streamline the subtleties of RL, such as managing advantage estimation and distributed weight synchronization.
Modal supports its users in leveraging well-tested frameworks while also continually improving and upstreaming enhancements that benefit open-source communities. While proprietary solutions may be appealing, the rapid evolution of the RL landscape makes open-source frameworks ideal for adaptability and rapid iteration.
Introducing Modal Dojo
To further enhance the user experience, Modal has developed Modal Dojo, an experimental library designed with user-friendly abstractions and common functions necessary for training jobs. The Dojo is accessible via GitHub, allowing teams to define and configure training jobs with minimal code.
To explore Modal Dojo and its potential in simplifying reinforcement learning job setups, users can download and integrate it effortlessly into their existing workflows. This innovative approach highlights Modal's ongoing commitment to creating streamlined solutions for modern training requirements, emphasizing efficiency and flexibility in RL applications.
As Modal continues to add features and enhance the library, collaboration with partners and the community will shape the future of RL training.
What’s Next?
Modal users can expect substantial improvements in the training job experience as new functionalities are introduced. They are equipped to orchestrate environments and manage distributed weights with confidence, freeing them from the complexities of infrastructure management and allowing for a sharper focus on enhancing their RL algorithms and overall performance.
Overall, embracing the infrastructure challenges inherent in Reinforcement Learning and leveraging meaningful solutions can enhance efficiency, decrease costs, and ultimately lead to more robust and effective AI training environments. Through Modal's innovative tools and commitment to open-source development, teams can achieve their ML objectives with greater ease.


