Leveraging Autoscaling in AI Research with Modal's Autoresearch Framework
- Gate
- Machine Learning
- Departs
- Crew
- James Smith
- Passengers
- 602
Modal enhances AI research efficiency by integrating elastic GPU provisioning, enabling dynamic resource allocation for research workloads.
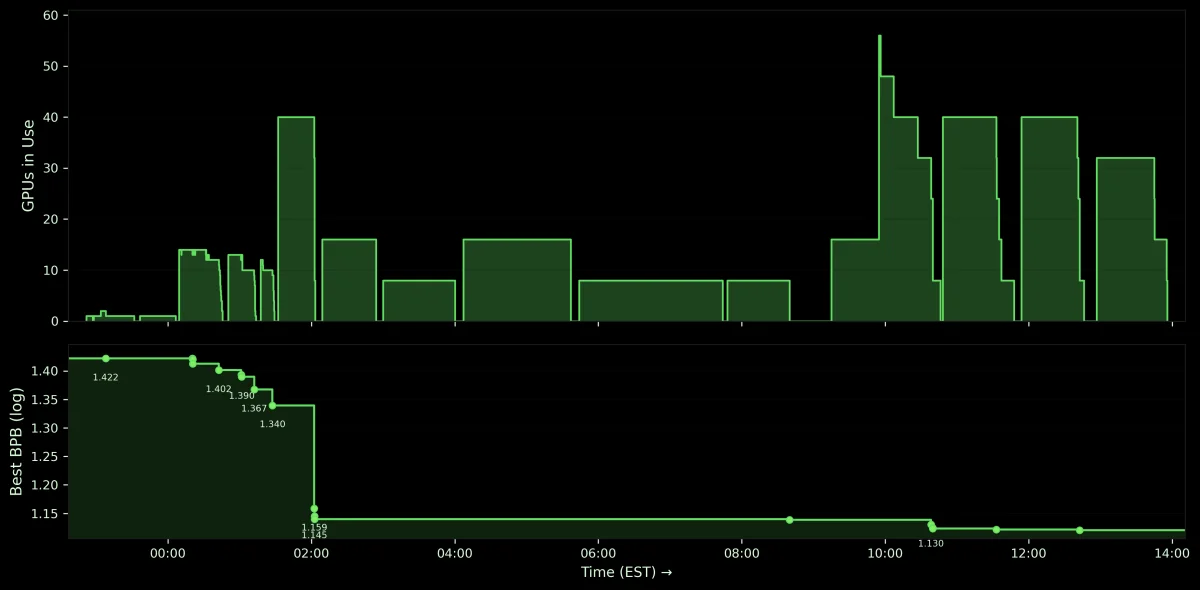
The rise of AI has spurred innovative approaches to accelerate AI research. With tools like Karpathy’s autoresearch, researchers face a familiar challenge: how to provide the necessary computational resources without incurring costs for excess capacity. Modal aims to solve this dilemma by offering autoscaling capabilities that intelligently adjust GPU resources based on workload demand.
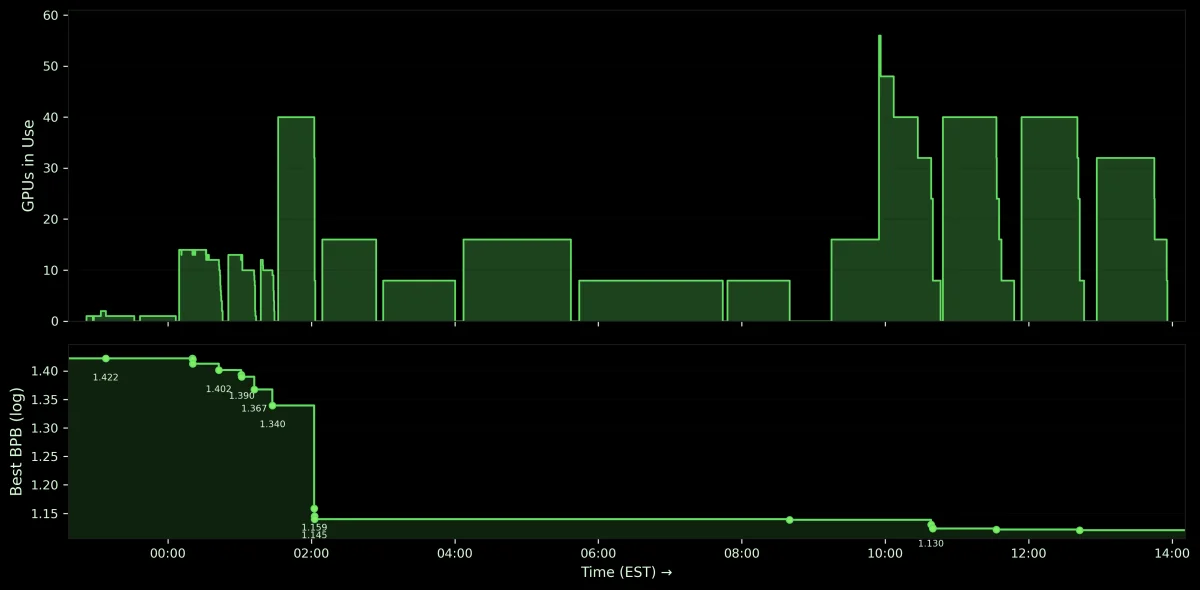
Autoresearch exemplifies the need for flexible computing in research environments. As demonstrated by Tony's recent experiment, a well-structured system can yield impressive results. He initiated a series of tests aimed at optimizing the performance of his model. Initially, he set a single agent to handle various research tasks while he addressed the computational needs effectively. After setting the environment, he let the system run overnight, which resulted in 113 experiments across 238 GPU-hours. Remarkably, the training runs were completed five times faster than using a standalone workstation, all while consuming a fraction of what a dedicated cluster would require.
Understanding Research Workloads
A major challenge in research is the variability of computational needs. Researchers often find themselves seamlessly shifting between utilizing dozens of GPUs for hyperparameter tuning and scaling down to just one GPU for debugging. Traditional configurations often compel them to choose between a constantly available but costly cluster or a cheaper yet inefficient workstation setup that limits experimentation speed.
The goal is to harness the advantages of both environments: cost-effective computing with the ability to scale up on demand. This kind of flexibility ensures that researchers maximize resource efficiency without compromising on performance. However, existing cloud infrastructures typically require researchers or their agents to pre-select a resource type, restricting the adaptive capabilities vital for research progress.
Modal addresses this challenge by allowing research agents to dynamically decide not only how much computational power to draw on at any given moment but also what type of computations to execute, driven by real-time demands.
Modal’s system provides a user-friendly experience, providing developers with a streamlined interface that facilitates operational fluidity. Researchers can write training scripts and define their GPU needs with straightforward coding functions, reducing the complexity often associated with managing computational resources.
Agent Framework and Deployment
In practice, users can define training parameters and invoke them easily — for instance, through an API command like modal.run. If debugging becomes necessary, the agent can switch to an interactive mode using modal.Sandbox.create(), making the debugging process more effective. This remarkable elasticity in resource provisioning allows researchers to escalate from utilizing a single GPU to deploying dozens within moments, depending on their experimental requirements.
After resource consumption, Modal automates resource deallocation, preventing unexpected costs from idle resources. The operational simplicity combined with powerful autoscaling capabilities results in improved productivity and reduces cost pressures.
Moreover, there is significant focus on user experience: Modal's command-line interface and accompanying documentation make it easier for researchers to utilize Modal’s compute capabilities without extensive training, paving the way for efficient research workflows.
Benchmarking Efficiency: The Parameter Golf Challenge
One notable test was OpenAI's Parameter Golf challenge, which required compressing a language model into a compact form, running efficiently on powerful hardware setups. Modal’s infrastructure allowed the agent to scale computational requirements to optimize its operations seamlessly—from initiating exploratory runs with single-GPU setups to executing extensive validation tests across multiple high-performance GPUs, dynamically adjusting as needed.
Throughout the process, benchmark results demonstrated tangible speedups and efficiency increases. For example, when exploring configurations across various hyperparameters, the efficiency of using single-GPU systems allowed for an aggregate optimization of resources, accumulating to noticeable reductions in benchmarking performance per byte (BPB) metrics.
| Speedup vs Workstation | Efficiency vs Cluster | BPB |
|---|---|---|
| 1x | 40x | 1.42 |
This validation phase illustrated that while there may not be a dramatic speedup due to limited GPU usage, the substantial cost savings against sustaining an idle cluster were notable.
Iterative Experimentation and Optimization
Following the initial exploratory runs, agents were tasked with refining configurations through iterative experiments. This included narrowing down model parameters and honing in on preferred architectures, resulting in a framework where agents could pivot effortlessly between single and multi-GPU resources.
The research agent utilized up to 40 independent computations to test divergent model sizes and training strategies, completing in just 36 minutes. Subsequent phases saw continuous improvements in efficiency and benchmarking metrics.
| Speedup vs Workstation | Efficiency vs Cluster | ∆BPB |
|---|---|---|
| 1.25x | 4x | 0.08 |
As configurations were validated, research agents could effectively identify optimal setups by scaling up to 8xH100 units for validation experiments, achieving a significant reduction in benchmarking metrics alongside promising speedups.
Tackling Bottlenecks and Debugging
However, challenges did arise. A significant bottleneck was identified in the quantization phase of the pipeline, highlighting the need for pointed debugging measures. This phase saw reduced throughput due to a reliance on CPU processing which vastly limited performance throughput. Adapting effectively to this, the agent transitioned to a GPU-based quantization process, thereby reducing the processing time significantly and allowing for a quick resolution to the bottlenecks encountered.
The ability for agents to fluidly pivot between operational modes offers distinct advantages — from experimental settings to debugging requirements, ensuring that the overall research velocity is maintained.
Realizing the Full Potential of Autoscaling
Modal’s integration of autoscaled infrastructure represents a significant leap forward in research methodologies within the AI domain. By enabling dynamic resource allocation, it allows researchers to optimize operational efficiencies and experiment across many environments without constraints. This essential feature distinguishes Modal as a forward-thinking solution aimed at addressing the intricacies faced by AI researchers.
In a field where the debates about the balance between innovation and scaling continue, Modal's solution reiterates that researchers can effectively enjoy efficiencies while also pursuing novel, research-intensive innovations. The recommendation for interested developers is to test Modal’s autoresearch Skills framework and explore its benefits in streamlining AI research endeavors.


