Reducto Enhances Document Processing Speed by 3x with Modal's Elastic Infrastructure
- Gate
- Machine Learning
- Departs
- Crew
- Thomas Jones
- Passengers
- 995
Reducto achieves a significant reduction in document processing latency using Modal's infrastructure, improving customer experience and operational efficiency.
Reducto aims to convert unstructured real-world documents into structured data, processing millions of PDFs, spreadsheets, and slide decks daily. With customers spanning from AI startups to large enterprises in critical sectors such as finance, legal, insurance, and healthcare, Reducto faces high demands for processing capability and speed.
The company must manage exceptional workloads, including millions of pages processed simultaneously, fluctuating traffic, and exacting latency standards for real-time interaction. To ensure a smooth customer experience, Reducto required elastic infrastructure to support its multi-model pipelines, which led them to adopt Modal.
The Challenge: Managing High-Volume Workloads
Initially, Reducto utilized manually provisioned EC2 instances for their product. As demand increased, they transitioned to Kubernetes for better compute management. This approach, however, soon revealed several shortcomings as usage expanded:
- Scaling a monolithic architecture: With numerous models in operation, Reducto had to scale all models simultaneously, despite varied usage patterns across them. This approach resulted in expensive GPU over-provisioning and complex operations when managing Kubernetes workers to accommodate traffic spikes.
- Latency inconsistencies: Uploading large batches of documents caused significant load surges, complicating the maintenance of consistent P90 latency for all clients.
- Infrastructure challenges during peak loads: Sustaining operations under heavy traffic bursts proved difficult. The team needed an approach allowing them to isolate model workloads and scale independently without affecting other customers.
In search of solutions, Reducto examined various alternatives. Some options lacked the necessary autoscaling speed; others, particularly API-centric solutions, didn't offer the level of code control required for their model inference needs. Ultimately, they selected Modal, which provides the customization and accessible GPU resources essential for their operations.
“We were fighting, like tearing our hair out trying to use Ray within our Kubernetes cluster, but the tooling was just not working. The ability to just `modal deploy` was really nice. Modal gives us a lot of flexibility to do pretty complex stuff that we wouldn’t get with an LLM inference service.”
— Raunak Chowdhuri, Founder
Deploying on Modal for Improved Latency
After transitioning their inference workloads for over 30 models to Modal, Reducto reported a 3x reduction in their P90 latency. Key factors contributing to this enhancement include:
- GPU memory snapshotting: This technique significantly reduces cold boot times, achieving an 83% decrease, from approximately 70 seconds to 12 seconds.
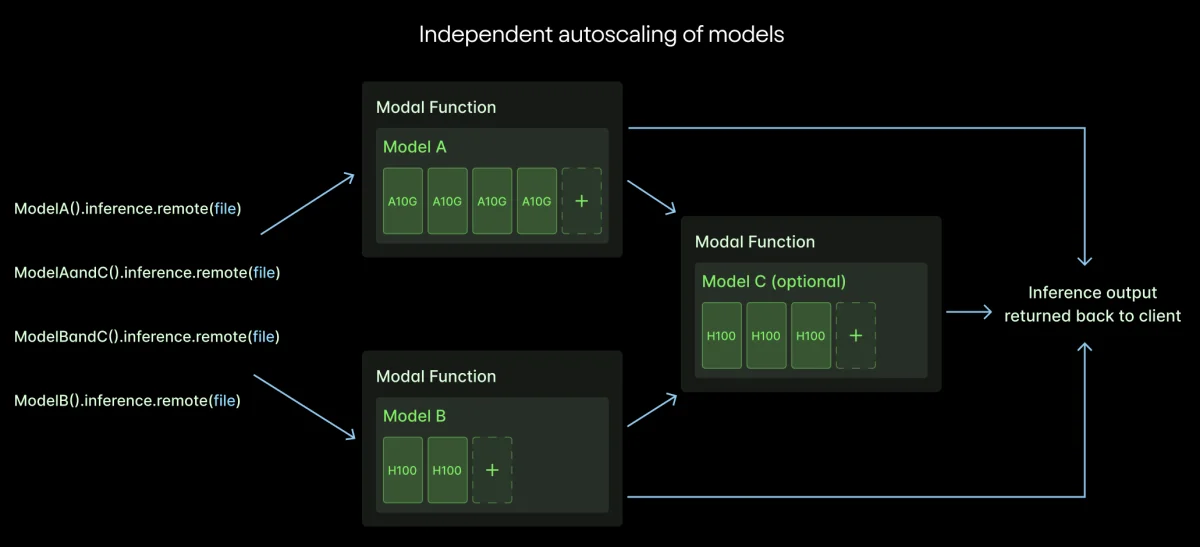
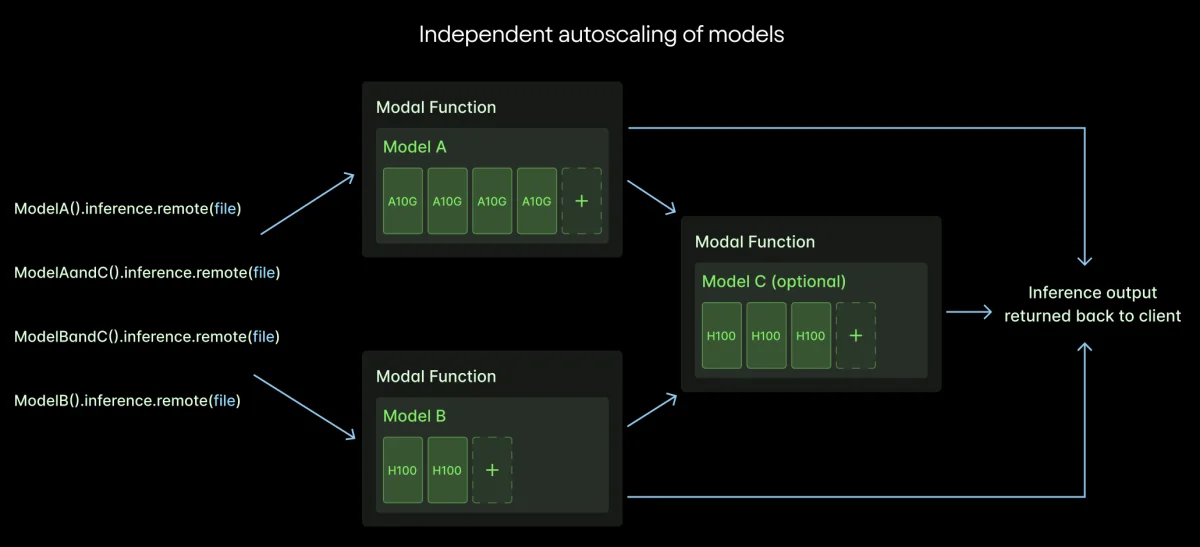
- Model-independent scaling: By grouping some models into combined Modal Functions while maintaining others separately, Reducto can optimize model autoscaling. This results in better resource allocation and diminished contention.
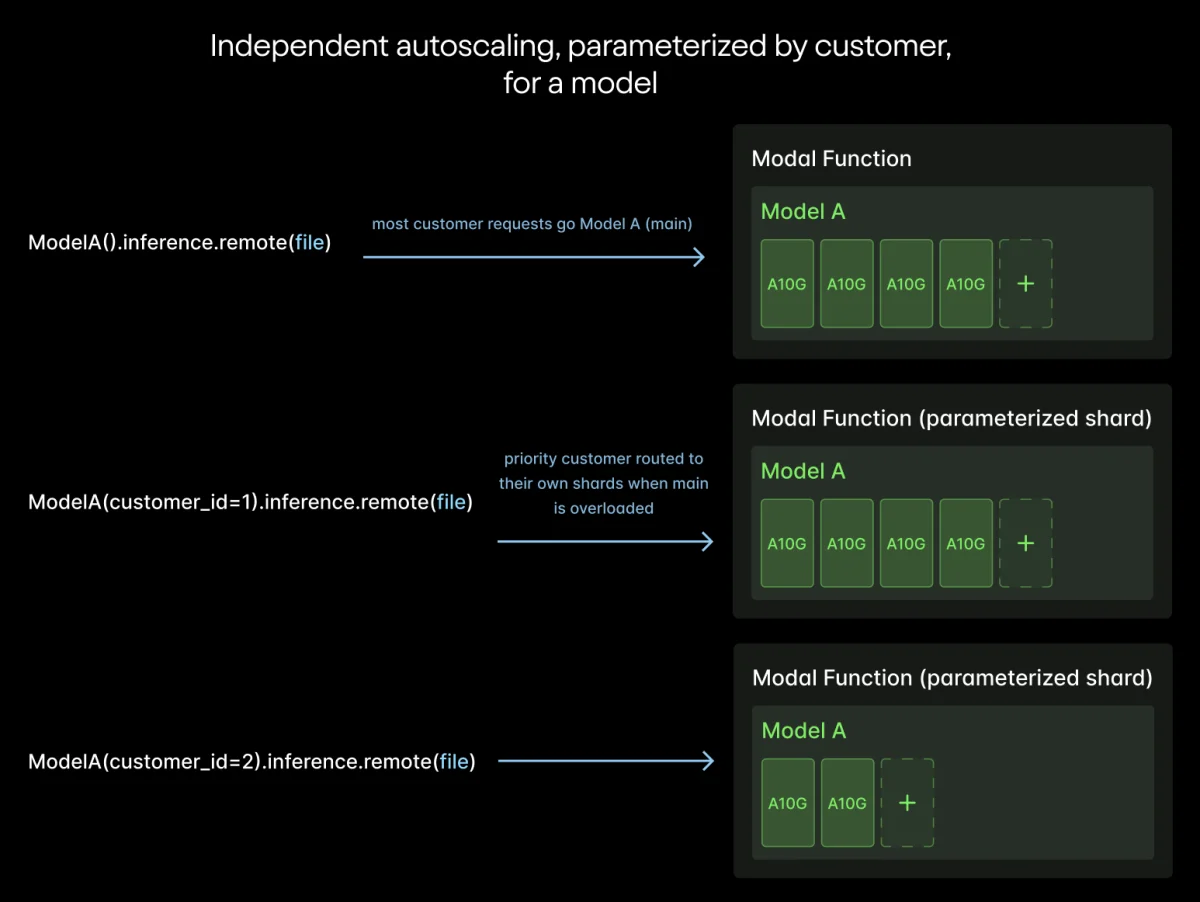
- Tailored customer scaling: Reducto employs parameterized Functions that allow for specific autoscaling compute pools per client. This customized approach prevents one client's load spikes from adversely affecting others' service levels.
- Regional latency optimization: To enhance network latency, Reducto positions critical Functions close to their servers in US West. Other workloads utilize Modal’s diverse global compute resources to manage peak demands.
Testing Modal Under Extreme Conditions
When tasked by a major enterprise client to demonstrate throughput capabilities of up to 100,000 pages per minute, Reducto seized the opportunity to rigorously test their architecture. On Modal, they successfully scaled their ingestion pipeline to over 1,000 GPUs within an hour and subsequently reduced it seamlessly. This performance not only validated their technical capabilities but also instilled confidence in the prospective client, leading to a successful contract.
Enhancing Developer Productivity
Reducto's engineers previously faced hurdles with infrastructure management that required grappling with Kubernetes complexities, extensive networking setups, and writing significant boilerplate code. The adoption of Modal transformed this landscape.
Utilizing Modal’s user-friendly SDK and powerful networking tools allowed engineers to devote more time to developing advanced OCR models rather than managing operational intricacies.
“If you look at lines of code on Modal to set up an endpoint that’s deployed to a URL, it’s literally just 2 lines of code. The equivalent on Kubernetes or Ray would be on the order of 150 lines of code, plus some configuration file, plus going into your CNS and clicking a bunch of buttons in Cloudflare.”
— Raunak Chowdhuri
Future Directions
As Reducto continues to develop AI-based document intelligence pipelines that classify, extract, and analyze dense enterprise documents, Modal serves as a reliable and cost-effective backbone for scaling their operations. The team is set to expand its use of Modal further by deploying additional large language and vision-language models.
Additionally, Reducto is harnessing Modal Notebooks for initial fine-tuning and rapid experimentation, which facilitates quick iterations on new product features. With Modal’s infrastructure backing their efforts, Reducto is positioned to deliver high-performance, production-ready document intelligence solutions well-suited for their largest customer engagements.


