Skip to departures
Generative AI
 NVIDIA's Acquisition of Hugging Face: A Move to Enhance Open AI Development
NVIDIA's $12.9 billion acquisition of Hugging Face aims to bolster AI development while preserving the platform's commitment to openness and community...
GateMachine Learning
Departs
 Botika Leverages Modal for Scalable Full-Stack Generative AI in E-Commerce
Botika's innovative approach automates the visual production pipeline for fashion brands, utilizing a custom-built full-stack AI on Modal for enhanced...
GateMachine Learning
Departs
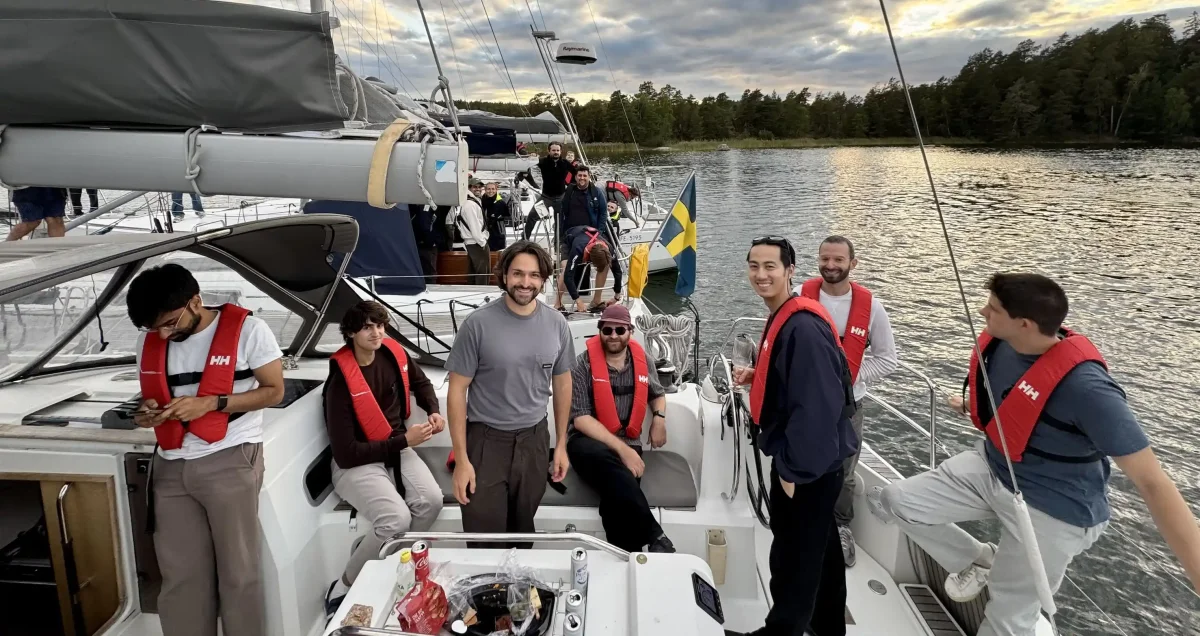 Modal Expands Its European Footprint with a New London Office
Modal announces its new London office, marking a significant expansion in Europe aimed at serving the growing AI market.
GateMachine Learning
Departs
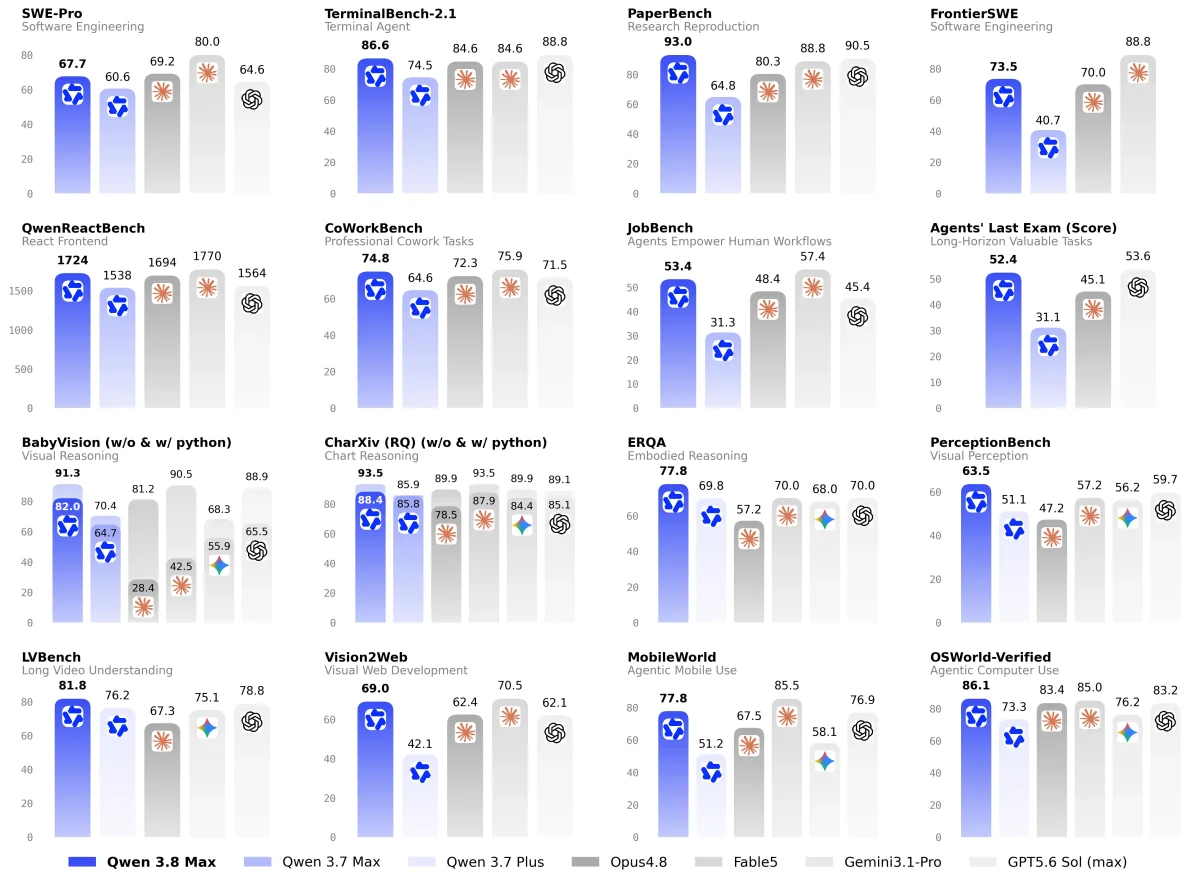 Qwen 3.8-2.4T-A95B Model Launch: Enhancements in Coding and Research Capabilities
The Qwen 3.8-2.4T-A95B model is now available on Modal, offering notable advancements in coding, research, and tool-based tasks.
GateMachine Learning
Departs
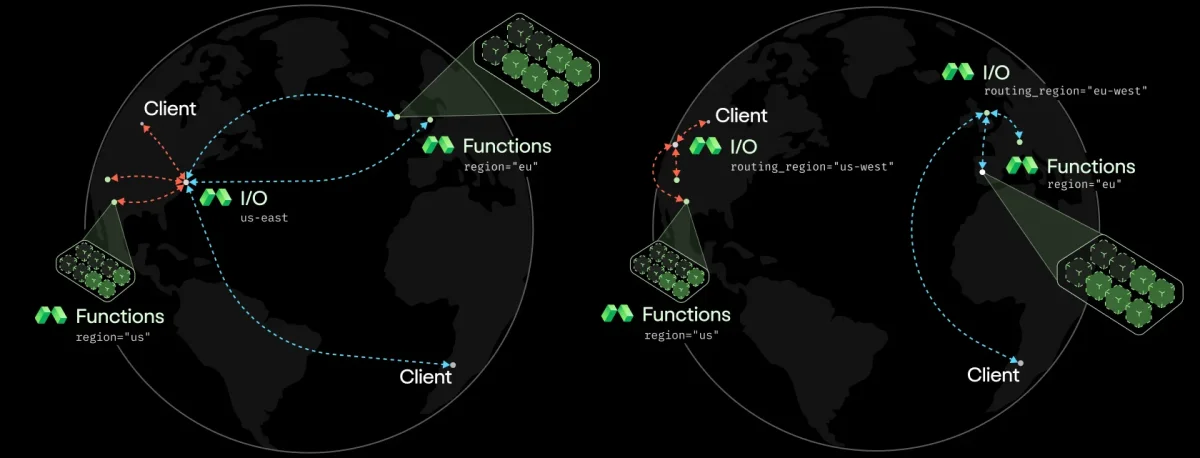 Enhancing Serverless Function Performance with a Geographically Distributed I/O Plane
Modal's new I/O plane significantly reduces latencies for serverless functions by offering regional routing options, improving overall speed and effic...
GateMachine Learning
Departs
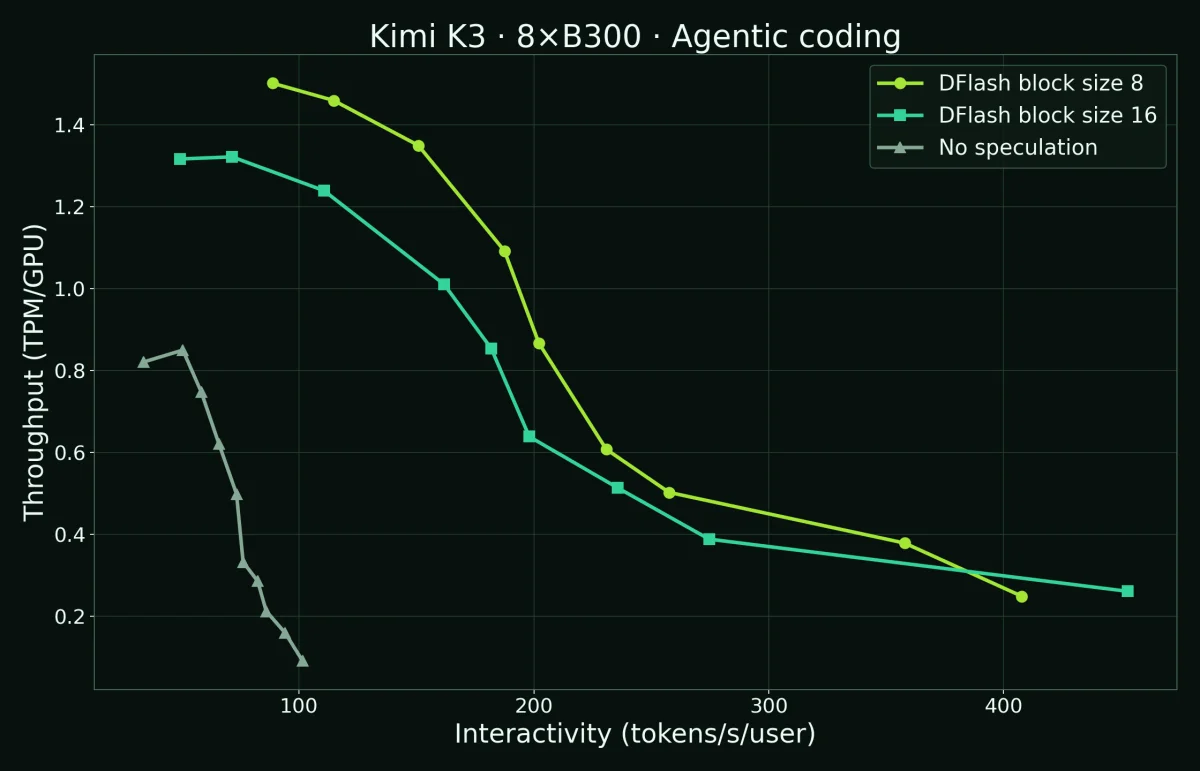 Moonshot Unveils Kimi K3: A 2.8 Trillion Parameter Multimodal Model with Substantial Performance Gains
Moonshot's Kimi K3, a 2.8 trillion parameter model, excels in multimodal tasks with remarkable speed and efficiency, setting a new benchmark in open A...
GateMachine Learning
Departs
 Thinking Machines Launches Inkling: A Multimodal Transformer Model
Thinking Machines' Inkling, a multimodal transformer model, integrates text, audio, and visual inputs, prioritizing efficiency and speed in processing...
GateMachine Learning
Departs
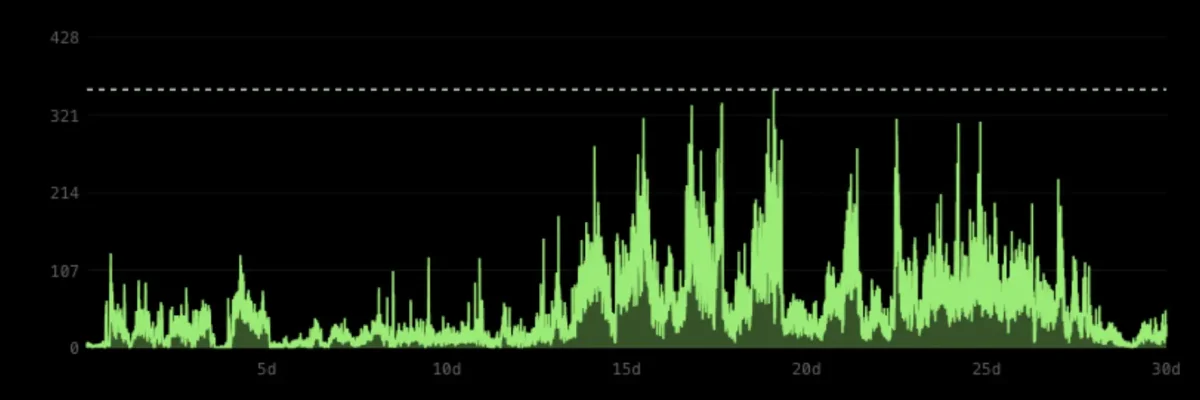 Understanding the Cost Dynamics of Serverless vs. Reserved GPUs
Explore the economic implications of using serverless versus reserved GPUs, including cost models, demand prediction challenges, and practical benefit...
GateMachine Learning
Departs
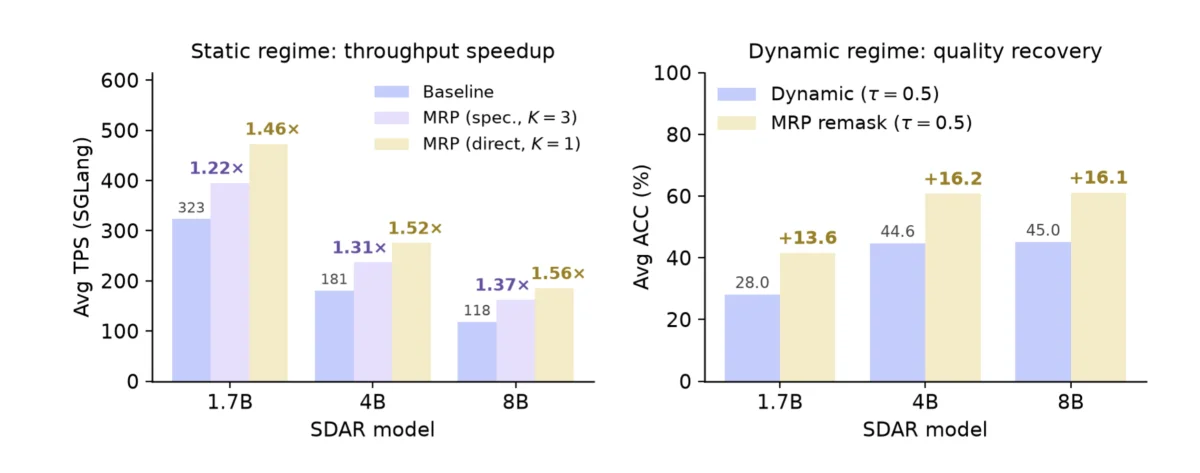 Enhancing Language Model Inference through Multi-Token Residual Prediction
The innovative Multi-Token Residual Prediction framework boosts language model efficiency, enhancing throughput and accuracy across various decoding r...
GateMachine Learning
Departs
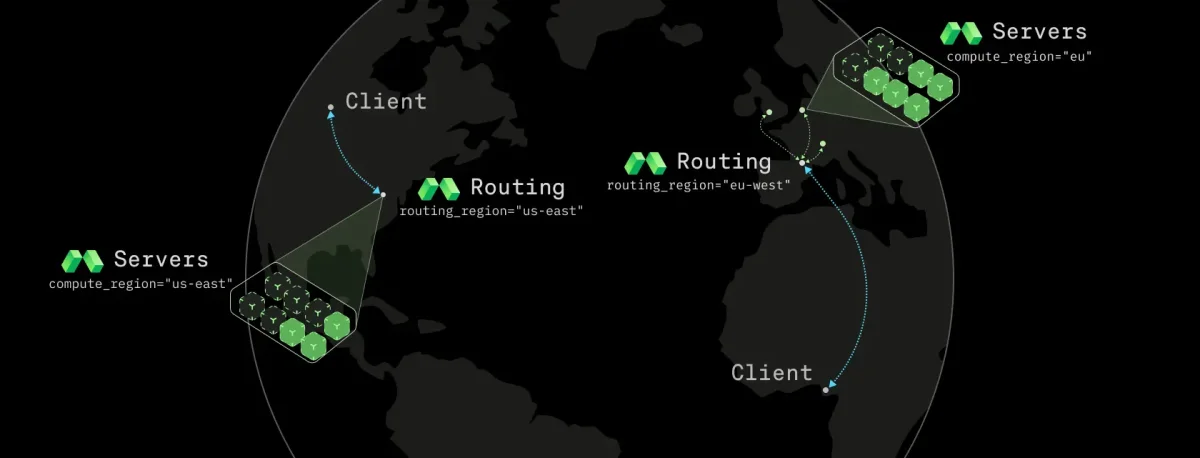 Modal Introduces Serverless Servers for Ultra-Low-Latency Applications
Modal's new serverless server capabilities significantly enhance low-latency performance for applications, reducing p50 latency to 6ms while maintaini...
GateMachine Learning
Departs
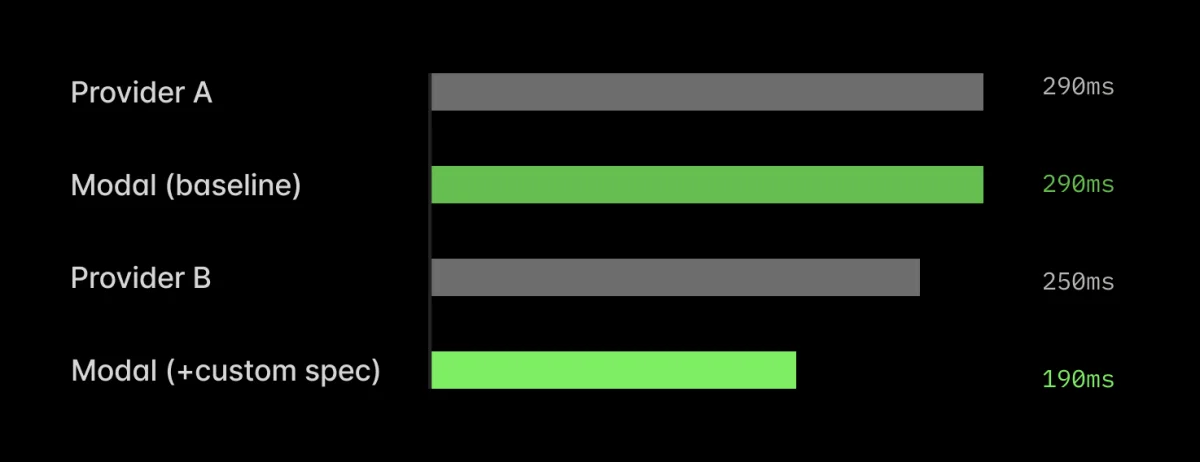 Speculative Decoding: Achieving Superior Inference Latencies with Advanced Techniques
Modal’s new speculative decoding approach enhances inference speed, beating proprietary systems by over 60ms, showcasing the power of optimized AI inf...
GateMachine Learning
Departs
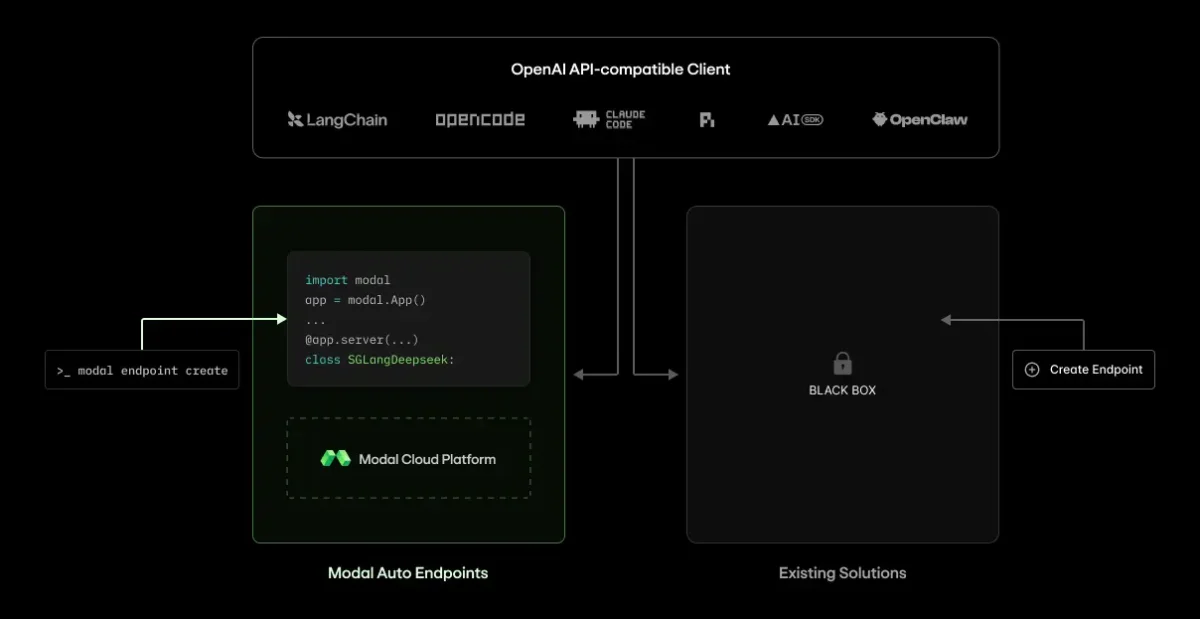 Modal Auto Endpoints: Empowering Teams to Own Inference Infrastructure
Modal's Auto Endpoints give teams the ability to manage and optimize their own inference setups, emphasizing cost-effective solutions without sacrific...
GateMachine Learning
Departs
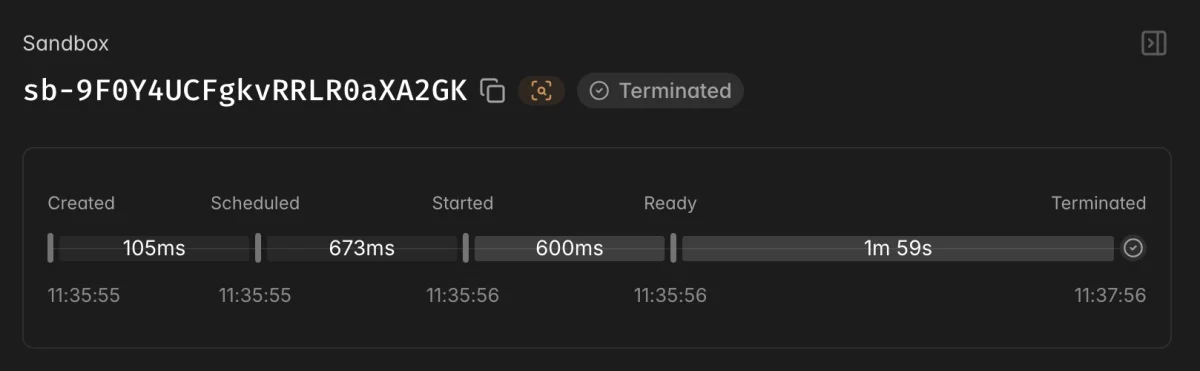 Optimizing Sandbox Startup Times: Understanding Latency Beyond Container Booting
Achieving faster sandbox user experiences requires addressing the entire startup lifecycle, from initial container booting to application readiness.
GateMachine Learning
Departs
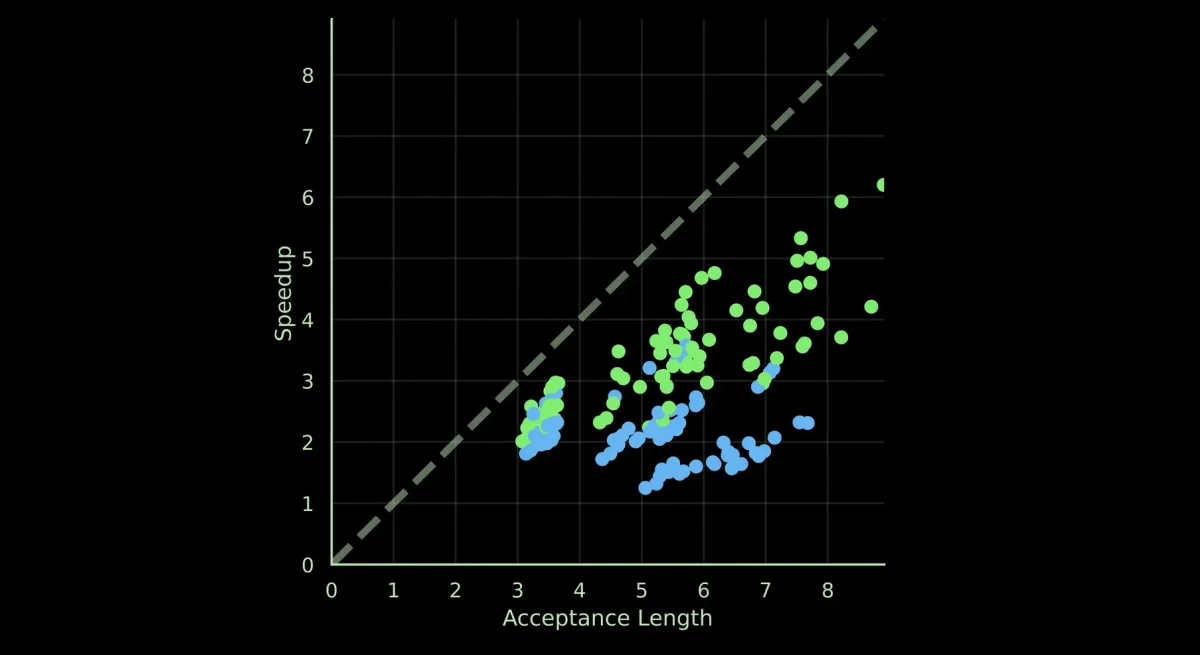 Unlocking AI Efficiency: How Speculative Decoding Enhances Model Performance
Speculative decoding boosts AI model performance, delivering significant speed improvements and better handling of long-context tasks for practical ap...
GateMachine Learning
Departs
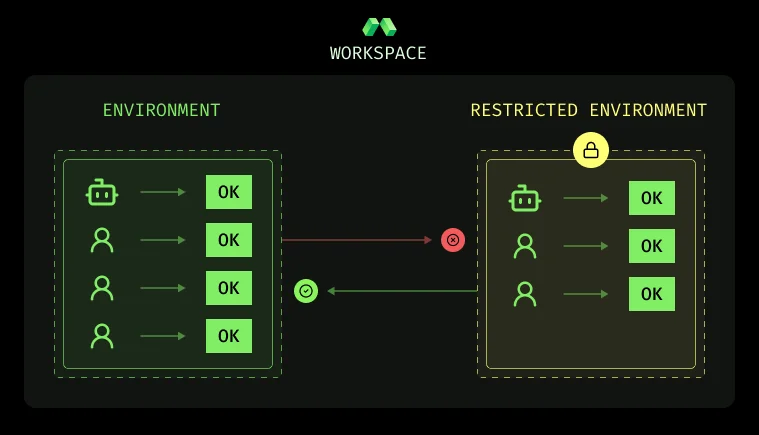 Modal Enhancements: Regional Routing, VM Sandboxes, Domain Allowlisting, and More
Modal introduces significant enhancements including regional routing for reduced latency, VM sandboxes for advanced workloads, and domain allowlisting...
GateMachine Learning
Departs
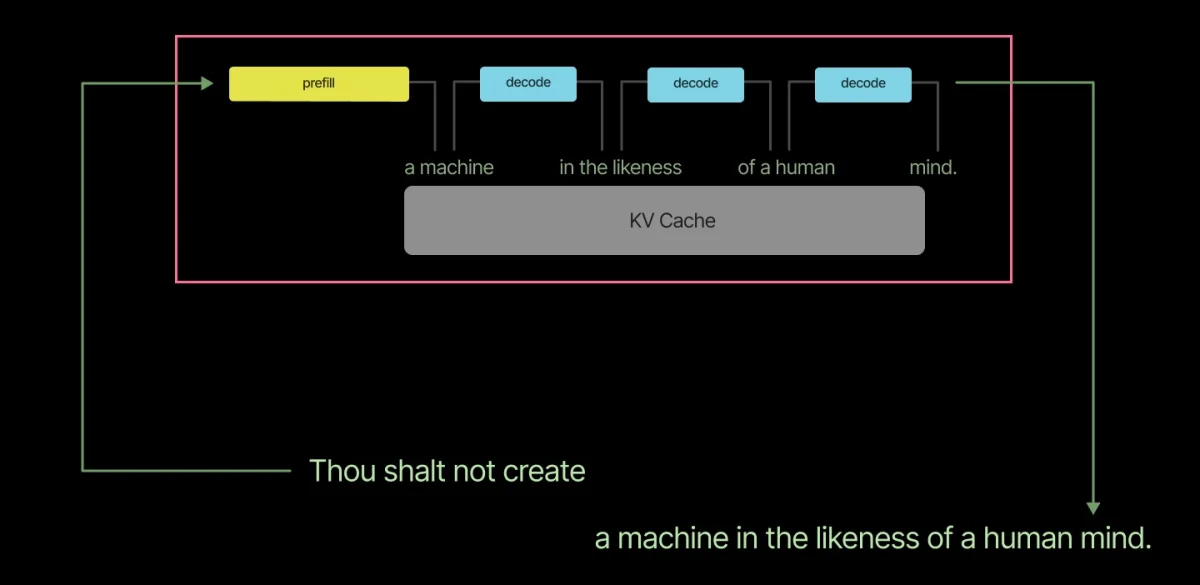 Optimizing FlashAttention-4 for Efficient Inference: Enhancements and Performance Metrics
Optimizations to FlashAttention-4 target improved inference efficiency, with a focus on lower precision inputs and enhanced memory access strategies.
GateMachine Learning
Departs
 Ensuring Safety in Robotaxi Deployment with NVIDIA Halos System
NVIDIA's Halos system provides a comprehensive safety framework for robotaxis, addressing critical challenges in deployment and operation scalability.
GateMachine Learning
Departs
 NVIDIA Introduces Scalable AI Models for Grasping, Autonomous Driving, and Virtual Agent Training
NVIDIA's latest research presents three advanced AI models aimed at facilitating robotic grasping, enhancing autonomous vehicle reasoning, and trainin...
GateMachine Learning
Departs
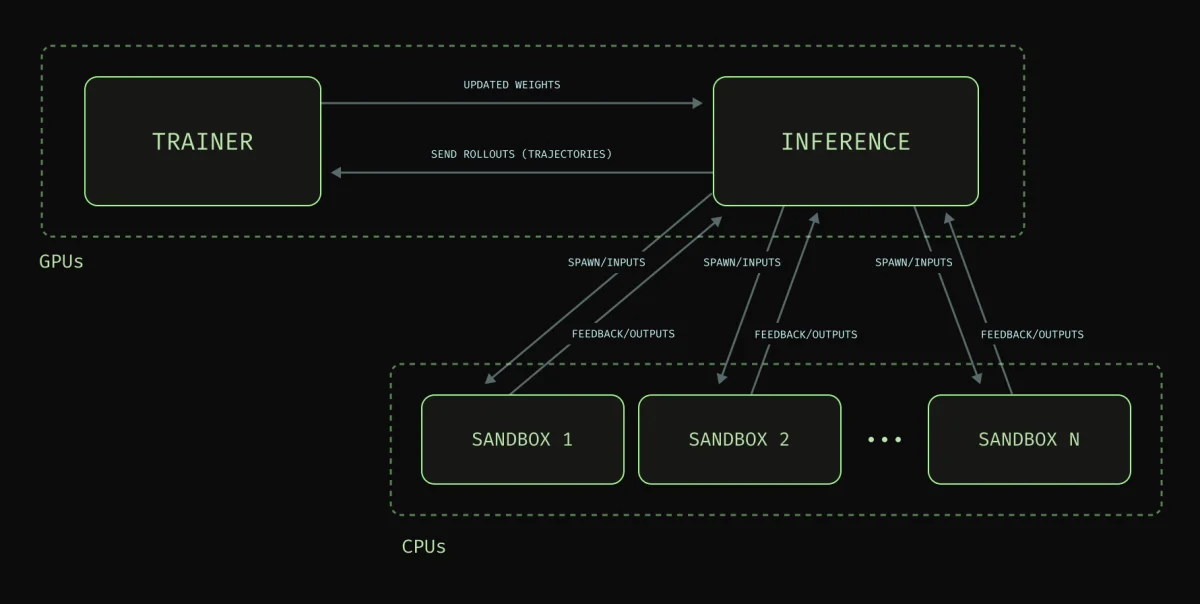 Challenges of Reinforcement Learning Infrastructure and Optimal Solutions
This article examines the critical infrastructure challenges faced in reinforcement learning (RL) training and presents strategic solutions to optimiz...
GateMachine Learning
Departs
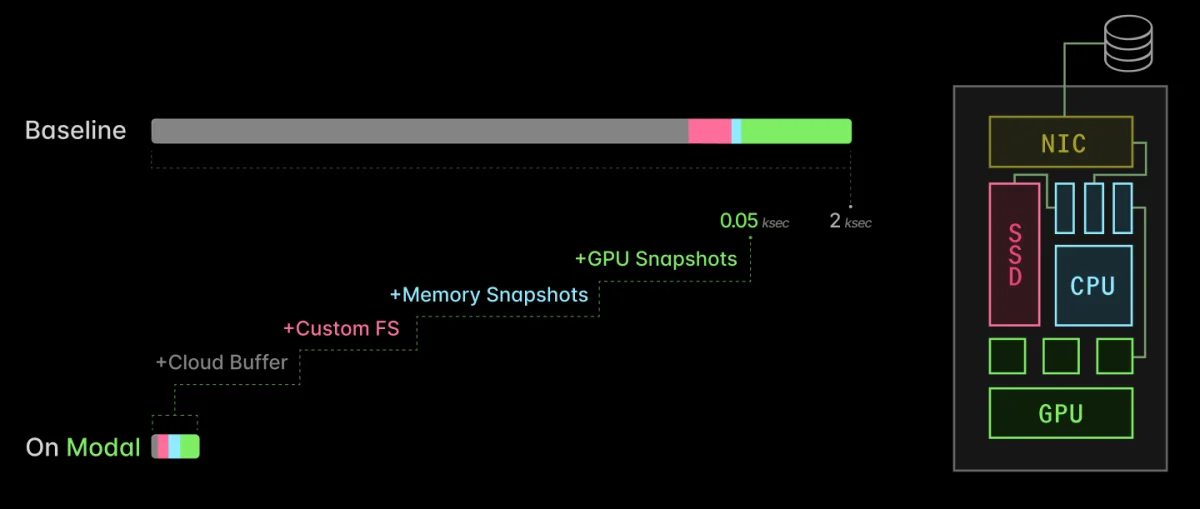 Optimizing Serverless GPU Inference: Achieving Rapid Scaling and High Utilization
Modal’s approach to serverless GPUs enhances allocation utilization and minimizes start times, addressing the challenges of dynamic inference workload...
GateMachine Learning
Departs