Understanding GPU Utilization: A Comprehensive Guide for Developers and Researchers
- Gate
- Machine Learning
- Departs
- Crew
- Charles Frye
- Passengers
- 986
This guide explores GPU utilization metrics, focusing on allocation, kernel, and FLOP/s utilization, providing insights on achieving optimal performance in machine learning workloads.
Graphics Processing Units (GPUs) have emerged as essential components in computational tasks, particularly where CPUs struggle to deliver the required performance. They excel at executing highly parallel tasks, such as matrix multiplications, which are fundamental to modern applications like neural networks. However, the high costs associated with these powerful processors drive the need for efficient GPU utilization among engineers and technical leaders. The mantra here is simple: “We’re paying a lot, so we’d better use all of it.”
At Modal, we have encountered various challenges surrounding GPU utilization and have developed strategies to help our users tackle these issues effectively. Interestingly, the term “GPU utilization” can refer to different metrics depending on the context, prompting us to establish a framework that clarifies these distinctions. This article will focus on three primary metrics of GPU utilization:
- GPU Allocation Utilization: The fraction of allocated GPUs running application code.
- GPU Kernel Utilization: The fraction of time application code runs on GPUs.
- Model FLOP/s Utilization: The ratio of actual throughput to theoretical arithmetic bandwidth.
We will concentrate specifically on neural network inference workloads due to their growing demand in various sectors, emphasizing the significance of turning inference from a cost center to a revenue-generating activity.
What is Utilization?
Utilization = Output Achieved ÷ Capacity Paid For
Utilization serves as a metric that links the available capacity of a system to its actual output. In GPU-centric applications, the capacity often reflects arithmetic bandwidth, while the output may be quantified as floating point operations per second (FLOP/s). Given its nature as a ratio, utilization is unitless and can encompass a variety of GPU-related measurements, depending on the implicit units of both the achieved output and the paid capacity.
What is GPU Allocation Utilization?
GPU Allocation Utilization = GPU-Seconds Running Application Code ÷ GPU-Seconds Paid For
GPU Allocation Utilization considers the number of GPUs allocated, whether they are physically owned or rented from a cloud provider. This metric signifies the fraction of allocated GPU-seconds that are actually utilized for running application code, representing one of the most fundamental metrics of GPU utilization.
There are economic and operational limits impacting the potential for GPU Allocation Utilization. Economically, the constraints stem from both technical and market limitations surrounding the procurement and management of GPUs. Unlike other resources, GPUs cannot be acquired, configured, and retired quickly enough to meet fluctuating demand, which leads to inefficiencies in utilization.
Moreover, while virtualization in cloud environments allows for more flexible allocation of GPU resources, existing market dynamics often enforce lengthy commitments that reduce flexibility in meeting quality of service (QoS) demands.
With a Fixed, Over-Provisioned GPU Allocation, Utilization is Low
High over-provisioning typically results in waste, as the fixed GPU allocations do not respond dynamically to real-time changes in workload demand.
At Modal, we aim to alleviate these challenges by streamlining GPU demand aggregation across users and improving efficiency in GPU allocation.
The real challenge for achieving high GPU Allocation Utilization also involves operational efficiencies. Even in a theoretically ideal market, considerable latency remains between acquiring GPU resources and their actual deployment for productive tasks—this includes overhead from configuring systems and transferring application code, which can result in reduced utilization rates.
If Allocation is Slow, Utilization and QoS Suffer
Without an effective strategy to manage rapid allocation and spin-up for GPU resources, organizations can fall short of desired utilization and quality-of-service metrics.
For optimal GPU Allocation Utilization, fast and efficient allocation processes are crucial, allowing organizations to quickly respond to workload increases.
With Fast, Automatic Allocation, Utilization and QoS Can Both Be High
This is one of the core advantages of Modal, leveraging a large multi-cloud GPU fleet to harness economies of scale while enhancing demand predictability. Our proprietary container stack, developed in Rust, significantly reduces latency from non-essential system tasks, positioning user workloads primarily around application functionality, thereby bypassing traditional VM management overhead.
What Level of GPU Allocation Utilization Can I Expect to Achieve?
Current statistics provide a sobering reality, with recent reports indicating that most organizations achieve less than 70% GPU Allocation Utilization during peak usage times. For instance, even advanced GPU platforms like Banana reportedly reached only an aggregate utilization of around 20%.
In contrast, Modal users can consistently achieve GPU Allocation Utilization exceeding 90%, not just at peak demand but across all usage scenarios.
If this peak utilization interests you, you’re encouraged to check out our documentation and pricing page.
What is GPU Kernel Utilization?
GPU Kernel Utilization = GPU-Seconds Running Kernels ÷ GPU-Seconds Paid For
Achieving overall GPU Allocation Utilization does not necessarily translate to effective usage of the GPU’s compute power, as it does not indicate the actual runtime of GPU kernels—specific execution units designed for GPUs. The GPU Kernel Utilization metric reveals the fraction of total allocation time spent executing code on the GPU itself.
It’s common for low GPU Allocation Utilization to result in similarly low GPU Kernel Utilization, highlighting an interconnectedness between these metrics. Factors contributing to low kernel utilization can include excessive overhead from non-GPU tasks that hinder effective data transfer, such as network or disk I/O operations and tasks involving heavy logging or data movement.
To optimize these elements, several strategies can be employed, including:
- Implementing parallelization practices and utilizing efficient data loading techniques, like lazy and eager loading.
- Increasing the bandwidth capabilities of non-GPU systems to minimize data transfer times.
- Applying code reduction principles, such as the “You Aren’t Gonna Need It” (YAGNI) approach to strip out unutilized code.
Another key issue arises when the CPU cannot supply tasks to the GPU at a sufficient pace, leading to idle GPU cycles. Managing the balance between computational tasks and concurrent execution is critical; if the CPU cannot rapidly finalize preparations for GPU workloads, GPU idling occurs.
Host overhead can often be mitigated by revisiting and optimizing host logic to minimize blocking processes. For instance, tasks requiring extensive log management can potentially impede performance if they are not streamlined away from the main data processing workflows.
To achieve optimal performance at GPU-level tasks, dual kernel launches or dynamic batching techniques can maximize operational coherence within the GPUs while also aggregating tasks for optimal performance without sacrificing responsiveness.
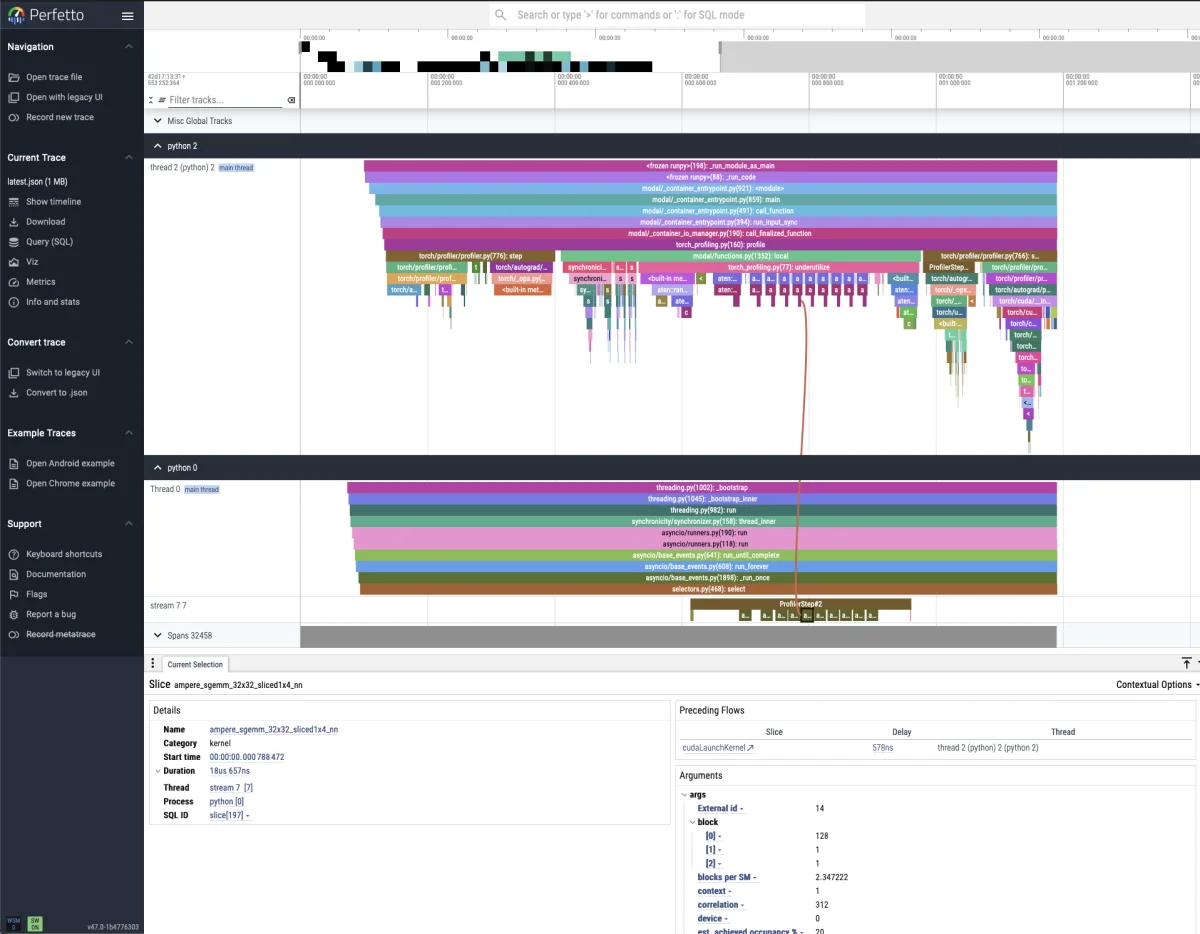
Developers can utilize profiling tools, such as the PyTorch Profiler, to identify key problem areas where the kernel utilization is low. By analyzing traces and identifying inactive CUDA streams, they can correlate those empty periods to host activities that may be contributing to inefficiencies.
What Level of GPU Kernel Utilization Can I Hope to Achieve?
Unlike CPU utilization, achieving a high level of GPU Kernel Utilization—ideally exceeding 90%—is not only feasible but desirable for developers aiming for efficiency. GPU applications typically exhibit lesser variability than those driven by CPU workloads, enabling more predictable performance and higher resulting utilization.
What is Model FLOP/s Utilization (MFU)?
Model FLOP/s Utilization = Model FLOP/s Throughput Achieved ÷ FLOP/s Bandwidth Paid For
From a broader financial perspective, investing in GPUs fundamentally signifies investments in the capacity for floating-point operations. This leads to the third and most advanced utilization metric: Model FLOP/s Utilization (MFU), which assesses the ratio of actual floating point operations achieved relative to the available bandwidth.
While low GPU Allocation or Kernel Utilization naturally leads to reduced MFU, high MFU at higher tier metrics is not guaranteed. Interdependently, GPUs also manage numerous tasks beyond straightforward compute operations; a significant part involves data movement, which is often bottlenecked by slower memory subsystems.
For achieving high MFU, optimization of data flow and overall kernel structure is essential. Efficient communication patterns and leveraging emerging technologies like Tensor Cores can dramatically affect performance. Resources like Si Boehm's log of experiences demonstrate the complexity surrounding these developments.
Monitoring options include utilizing tools such as the NVIDIA Data Center GPU Management tool, which offers specific metrics for FLOPs and memory throughput that are invaluable for tracking MFU.
What Level of Model FLOP/s Utilization Can I Hope to Achieve?
Measuring MFU accurately can be challenging, as theoretical bandwidth figures provided by hardware manufacturers often come with caveats that can affect their reliability. Leading organizations in the field, such as OpenAI and Meta, showcase the latest advancements in MFU with notable utilization rates, yet typically face hurdles in achieving noticeably high levels of utilization in extensive or distributed systems.
For inference-centric workloads, the potential for achieving higher MFUs (estimated around 70-80%) exists, although documented results from large deployments remain scant.
How Can I Improve My GPU Utilization?
If you are not already utilizing Modal, it’s worth considering as a potential avenue to enhance GPU Allocation Utilization significantly.
Moreover, embedding a deeper understanding of GPU computing principles can yield substantial benefits. We have compiled a GPU Glossary for a comprehensive look at key terms and resources that can facilitate learning in this domain.
Some recommended resources to further your knowledge include:
- A detailed talk by Horace He, a core member from the PyTorch team.
- An in-depth blog post by Abhinav Upadhyay.
- The ML Engineering Open Book by Stas Bekman, replete with insights and useful snippets across various aspects of GPU computing.
We appreciate the insights contributed by experts like Mark Saroufim from PyTorch and Erik Dunteman from Pig regarding the development of this article.


