NVIDIA L40S GPUs Now Available on Modal: Enhancements for Inference Workloads
- Gate
- Machine Learning
- Departs
- Crew
- Michael Johnson
- Passengers
- 680
Modal users can now access NVIDIA L40S GPUs, offering enhanced memory and speed advantages over the A10 GPU for demanding inference tasks.
Modal has announced the integration of NVIDIA L40S GPUs into its platform, targeting the growing demand for enhanced performance in AI inference workloads. This new offering focuses on providing users with flexible and powerful capacity by leveraging the strengths of the L40S, which is priced at $1.95 per hour for usage.
Key Advantages of the L40S GPU
The L40S brings significant upgrades compared to the widely used A10 GPUs. One of the most notable improvements is the memory capacity: the L40S features an impressive 48GB of DDR6 RAM, which is double that of the A10's 24GB. Such an increase in on-device memory isn’t just a number; it opens doors to executing larger models with more substantial inputs. Users handling big AI models often face hurdles due to memory limitations, which restrict the scope of their tasks.
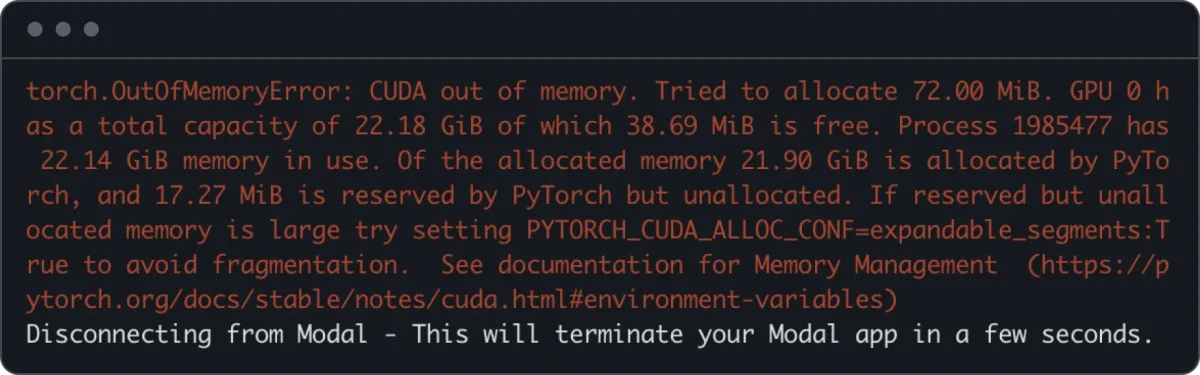
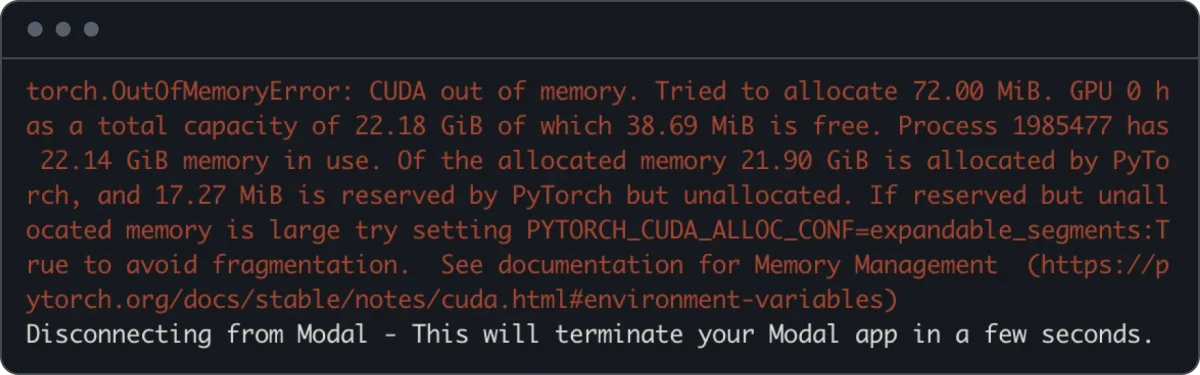
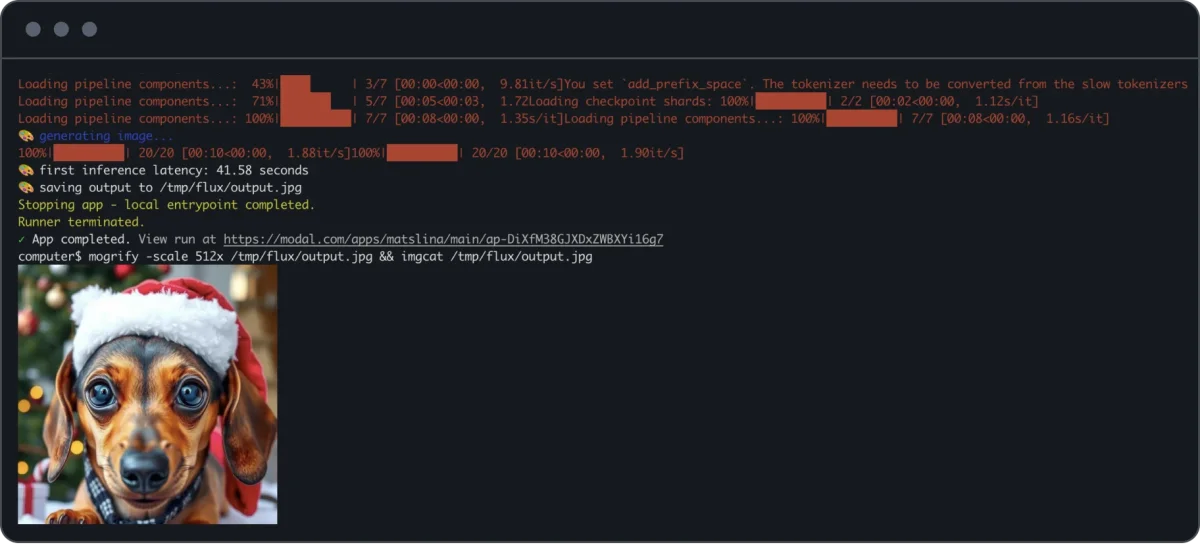
For example, when running Flux.1-schnell in 16-bit precision, the model’s weight storage alone requires 24 GB of RAM. When using the A10, this necessitates a CPU offload that can lead to performance bottlenecks and the dreaded "CUDA Out of Memory (OOM)" errors. These issues often hinder productivity and limit experimentation. In contrast, the L40S can comfortably accommodate this workload within its memory limits, allowing for improved operational efficiency and less hassle dealing with memory management.
Performance Speed Improvements
Speed isn’t merely a buzzword when discussing the L40S. Users can expect significant boosts, particularly in memory-bound jobs like small-batch inference tasks. Reports suggest an approximate 40% improvement in these scenarios. For compute-bound jobs, speed enhancements exceed 100%, especially when utilizing 16-bit Tensor Cores on the GPU. This improvement can dramatically reduce the time needed for tasks, which can be a vital factor in a more competitive market.
In informal testing, Modal achieved a 20% speedup in a basic load test designed for chat-type workloads. What’s interesting here is that this performance gain comes without requiring any tuning adjustments. This demonstrates not just raw power but also ease of use—a combination that could attract users hesitant to fine-tune every parameter of their setups.

Comparative Specifications of A10 vs. L40S
When contrasting the specifications of the A10 and the L40S side-by-side, the advantages of the L40S become even more evident. For those interested, here's a detailed look at how these two GPUs stack up against each other:
| Feature | A10 | L40S |
|---|---|---|
| Streaming Multiprocessor Architecture | Ampere | Ada Lovelace |
| Compute Capability | 8.6 | 8.9 |
| GPU RAM | 24 GB DDR6 | 48 GB DDR6 |
| Memory Bandwidth | 600 GB/s | 864 GB/s |
| FP16/BF16 Tensor Core Arithmetic Bandwidth | 125 TFLOP/s | 362 TFLOP/s |
| FP8 Tensor Core Arithmetic Bandwidth | N/A | 733 TFLOP/s |
Deployment and Cost-Effective Options
Setting up and running workloads on the L40S couldn’t be easier with Modal's infrastructure. Users can deploy code to GPUs in approximately one second. This kind of speed is not only pivotal for quick experimentation but also supports scaling seamlessly as project demands evolve. Modal's system features autoscaling across hundreds of GPUs, which ensures users are only charged for the resources they utilize. This pricing model could be particularly appealing for startups or smaller teams that lack the budget for high upfront infrastructure costs.
For those interested in exploring the L40S, Modal offers $30 worth of free compute each month. This allows new users to test the GPU capabilities at no cost initially, which could be a game-changer for those hesitant to invest in new technology. To get started, new users can sign up for Modal, install the Python SDK, and simply annotate functions with app.function(gpu="L40S"):
import modal

app = modal.App()

@app.function(gpu="L40S")
def run_flux_inference():
    # This will run on a Modal L40S
For questions regarding the L40S GPU or to share insights about projects built on this platform, users are encouraged to reach out via the community Slack.
Implications and Future Outlook
The implications of Modal’s integration of the L40S GPU extend beyond just technical upgrades. This move is likely to influence how developers and companies approach AI inference workloads. The scalability and performance enhancements offered by the L40S can lead to more efficient workflows. If you're working in this space, you might find yourself more willing to tackle larger and more complex AI problems, thanks to the enhanced capabilities.
Moreover, as AI continues to evolve and permeate various sectors, faster and more efficient processing will be vital. Organizations that embrace these advancements may find themselves better equipped to harness the power of AI effectively. With increasing competition in AI-driven innovation, tools like the L40S could provide a significant advantage. And yet, the long-term commitment to optimizing and integrating these technologies remains a challenge for many firms. Project timelines, budgets, and technical expertise are all crucial factors to consider as organizations navigate this landscape.
This could be more significant than it looks at first glance; having access to superior technology like the L40S might not just streamline operations but also lead to breakthroughs in how AI can be applied across various domains.


