NVIDIA DGX Spark Four-Node Kit Brings Multi-Node Scientific Computing to the Desk
- Gate
- Machine Learning
- Departs
- Crew
- Allen Bourgoyne
- Passengers
- 755
Four connected DGX Spark systems offer 512GB of combined memory and a local environment for developing and testing scientific workloads.
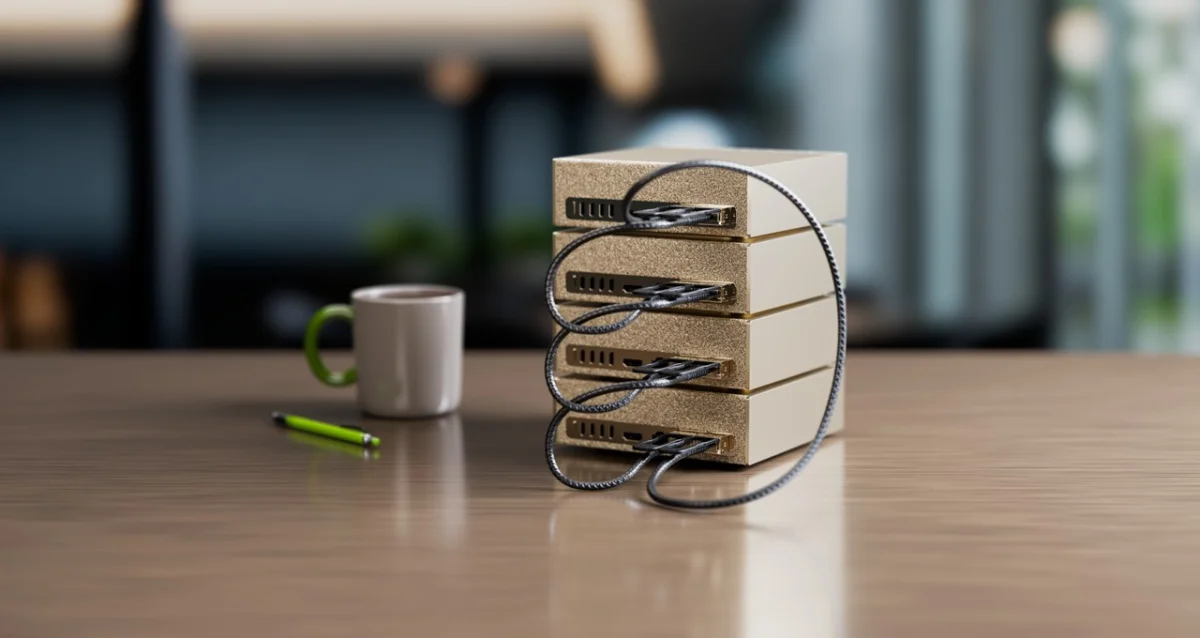
NVIDIA’s DGX Spark HPC Developer Kit is designed to move part of scientific computing closer to the researchers who build and debug workloads. The four-system cluster gives teams a local place to test multi-node applications and AI workflows before using larger shared systems. Its practical appeal is less about replacing those systems than reducing the wait and iteration costs that can slow early development.
Introduced at SC26 in Chicago, the kit links four DGX Spark systems in a ring through NVIDIA ConnectX-7 networking. Each node connects directly to its two neighbors, so the cluster does not require a separate network switch. Teams can also begin with one system and expand to four. NVIDIA says the four-node setup combines 512GB of memory with 20TB of NVMe storage.
Local development across four nodes
Each DGX Spark uses the GB10 Grace Blackwell Superchip. Across the cluster, researchers can distribute scientific workloads and AI models among the nodes, then inspect how computation and data move between them. That gives developers a way to find application and communication problems before scaling to a larger environment.
NVIDIA says NVFP4 lets researchers deploy models with up to 700 billion parameters locally across four DGX Spark systems, citing DeepSeek V4.1 as an example. That figure describes deployment under the specified low-precision format; it does not establish that every model at that size will fit or run with the same performance. The available information does not provide throughput, power use, or workload-specific comparisons with larger GPU clusters.
The intended software path is still being assembled. NVIDIA says an installation playbook for the HPC SDK is coming soon. It is expected to bring GPU-accelerated C, C++ and Fortran compilers, libraries, and message passing interface tools to the cluster. Those tools are used on NVIDIA-powered supercomputers, making the kit a local development environment for applications intended to scale across multiple nodes.
For researchers working under fixed compute allocations, local access can make it easier to develop and debug without waiting for shared-cluster time for every change. It can also keep unpublished results and proprietary datasets on an organization’s own infrastructure. Larger production runs will still depend on the capacity available to each team, but local iteration could reserve shared resources for jobs that need them.
Scientific workloads and reported use cases
NVIDIA has demonstrated four-system workloads that include LAMMPS with Kokkos for materials simulation and NAMD for molecular dynamics. The wider DGX Spark community has also validated GROMACS for molecular dynamics, OpenFOAM for fluid dynamics, and WRF for weather modeling. NVIDIA NIM microservices cited for biomolecular structure prediction include OpenFold3 and Boltz-2.
For the Nemotron 3.5 Super VL model, NVIDIA describes new open dataset and post-training recipes for life sciences and chemistry. These are intended to help researchers adapt the model to scientific tasks while running workflows on infrastructure their organizations control. The announcement does not specify training times or provide comparative results for these recipes.
Potential workflows include using agents to prepare simulation inputs, launch runs, and summarize results, with researchers checking the setup and conclusions. Another proposed use is training AI models to approximate slower simulations, such as exploring wing designs for lower drag. Teams could also use smaller experiments to identify which dimensions matter before committing to a simulation with 10 million cells. These examples describe development possibilities; they do not establish that an agent or surrogate model can replace scientific validation.
Several teams report work on individual DGX Spark systems. Kvantify says it used NVIDIA cuQuantum to run tensor-network simulations of quantum-chemistry circuits with up to 70 qubits and 975 gates. Its benchmarks used circuits generated for penicillin ground-state energy calculations. That result illustrates a specific workload and setup, rather than a general performance measure for quantum chemistry.
CYRAN AI, a spin-out from IIT Delhi, uses DGX Spark with its PixelFlux library to speed up JPEG 2000 decoding for large satellite images and support local geospatial analysis. OpenFold has described fine-tuning OpenFold3 on DGX Spark to improve protein-ligand structure predictions for drug discovery.
The Rubin Lab at the Innovative Genomics Institute at the University of California, Berkeley, uses DGX Spark and NVIDIA Evo 2 to predict bacterial traits from genome sequences. Its approach compares embeddings from genomic and protein language models with classical baselines. The lab reports that results arrived 15 times sooner on DGX Spark, avoiding an 11-hour cluster queue.
The Hartwig Group at UC Berkeley reports using one DGX Spark to fine-tune the Nemotron 3 Super 120B-A12B model with low-rank adaptation, or LoRA. The group trained a prediction head on experimental values and used NVFP4 quantization to fit the 120-billion-class model on a single device. It says this avoided multi-day cluster queues and allowed continuous training fits lasting eight to 24 hours. These are lab-reported outcomes; the announcement does not give the comparison hardware or a broader benchmark.
Availability and next steps
The developer kit is available for sale and on display at SC26. DGX Spark systems and cables can be purchased through NVIDIA Marketplace and participating manufacturers, including Acer, ASUS, Dell Technologies, GIGABYTE, H3C, HP, Lenovo, MSI, and xFusion. NVIDIA says the HPC SDK playbook is still forthcoming, so teams planning scientific development should account for that software setup guidance not yet being available.
The kit’s value will depend on whether a team’s applications fit its memory, storage, and networking setup, and whether local work meaningfully cuts iteration time. The reported projects offer concrete starting points across simulation, chemistry, biology, and image processing. The next useful evidence will be workload-level results showing performance across nodes and how closely local development carries over to larger systems.