Optimizing Multimodal Inference: Cache Lookup Enhancements in SGLang Yield Significant Performance Gains
- Gate
- Machine Learning
- Departs
- Crew
- David Garcia
- Passengers
- 747
SGLang v0.5.10 achieves over 16% throughput improvement and 10% latency reduction for multimodal inference through optimized cache lookups, enhancing efficiency and user experience.
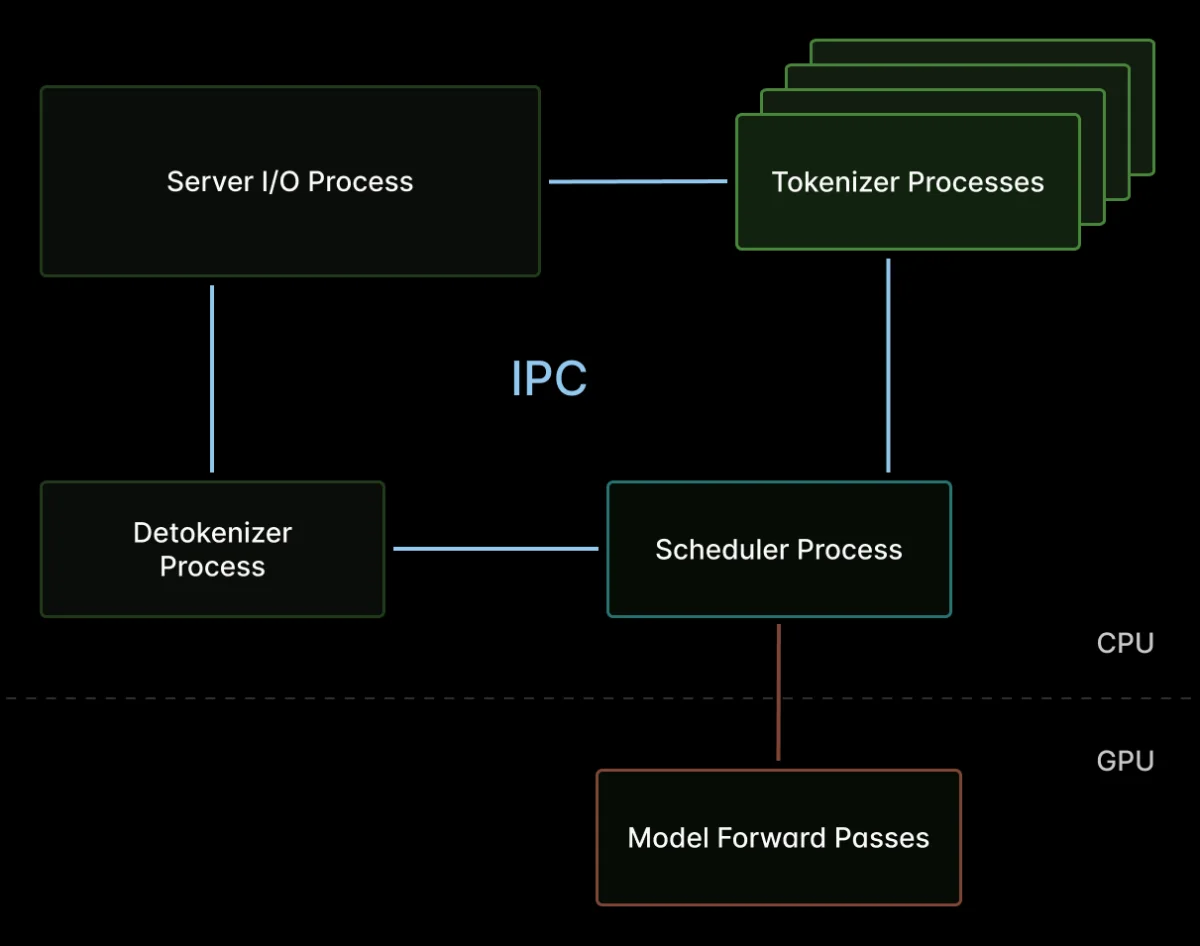
Multimodal models, especially vision-language models (VLMs), have shown remarkable potential in various applications. However, inference engines deployed for these models often face performance drawbacks that need addressing. A recent evaluation of SGLang’s scheduler on a multimodal workload revealed an untapped opportunity to enhance efficiency: by replacing resource-intensive bookkeeping for shared GPU memory with a straightforward cache lookup. This modification resulted in over 10% improvements in both throughput and latency, and it has been incorporated into SGLang version 0.5.10.
Understanding Multimodal Models and Their Challenges
VLMs enable AI systems to seamlessly integrate and interpret visual and textual information, allowing for highly advanced capabilities in document processing and application design. This dependence on processing unstructured data and the execution of multimodal tasks introduces fresh challenges for open-source inference frameworks like SGLang and vLLM. These challenges often stem from inefficient ways in which the models interact with GPU resources, impacting overall performance.
Performance Benchmarking and Identifying Bottlenecks
During a customer's benchmarking of the Qwen2.5-VL-3B-Instruct model on H100 GPUs, analysts observed that SGLang's throughput fell short of the GPU’s capabilities. They revisited the fundamental principles of performance engineering, specifically the maxim to “never block the GPU.” Isolating host-level overhead became crucial in identifying the bottleneck: a single-threaded scheduler that gates the work to the GPU was resulting in excessive delays.
Diagnosing Host Overhead with Profiling Techniques
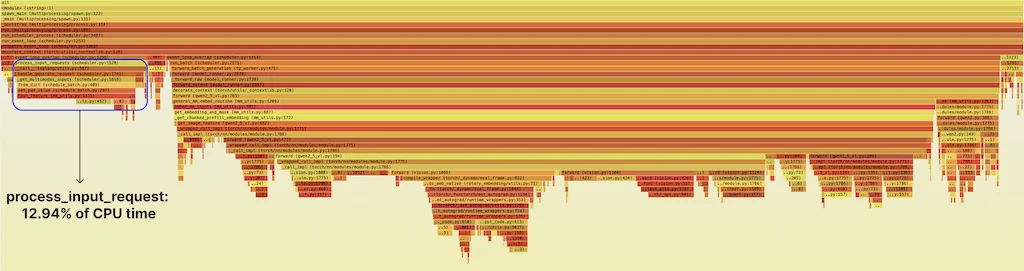
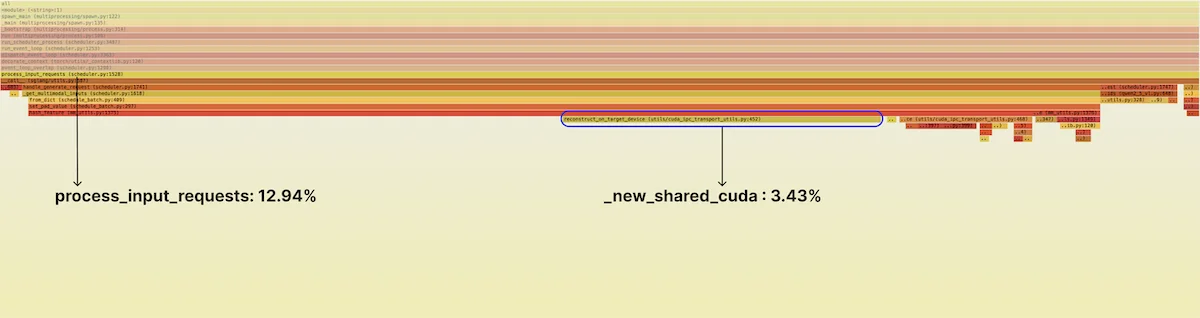
The SGLang scheduler is a critical component responsible for managing the traffic to the GPU. Profiling this element using tools such as py-spy illustrated that a significant portion of CPU time was expended in a function called process_input_requests, consuming approximately 13% of total scheduler CPU time. Within this function, it became clear that excessive time was dedicated to operations related to feature hashing, particularly the mapping of input images to hash-based IDs, which is essential for efficient retrieval during cache lookups.
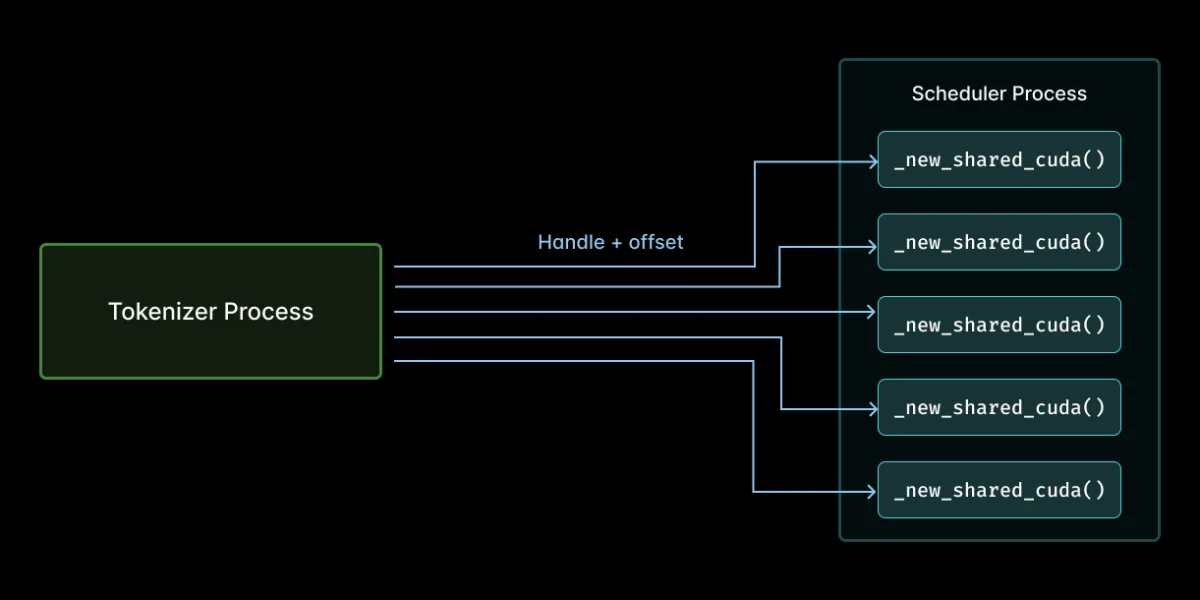
Streamlining the Process with Efficient Caching
To alleviate host overhead drastically, the team implemented a cache mechanism utilizing a Python dictionary to store references to allocated resources. This shift meant that the scheduler no longer needed to repeatedly reallocate resources for each tensor communication, incurring substantial time penalties. Instead of opening each resource anew, the caching solution allows the retrieval of existing handles, which are immutable once established. This adjustment ensures minimal interaction with the CUDA runtime for resource management between tokenizer processes and the inference scheduler.
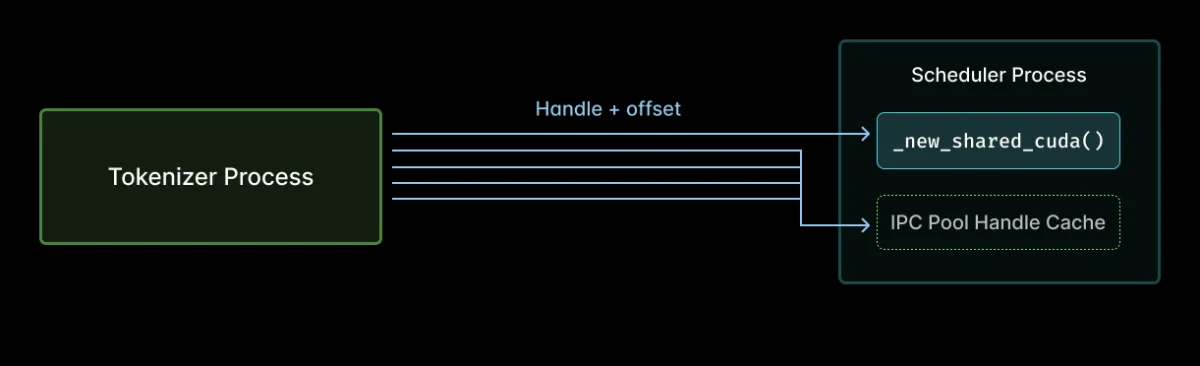
Profile Results After Optimization
The impact of the caching implementation was documented through repeated profiling cycles. With the cache active, the time spent in critical functions associated with resource sharing and retrieval dropped significantly. Notably, the hotspot in profiling effectively vanished, with the overall sample size in input processing being reduced by more than half. The changes led to measurable performance improvements reflected in a benchmark overview.
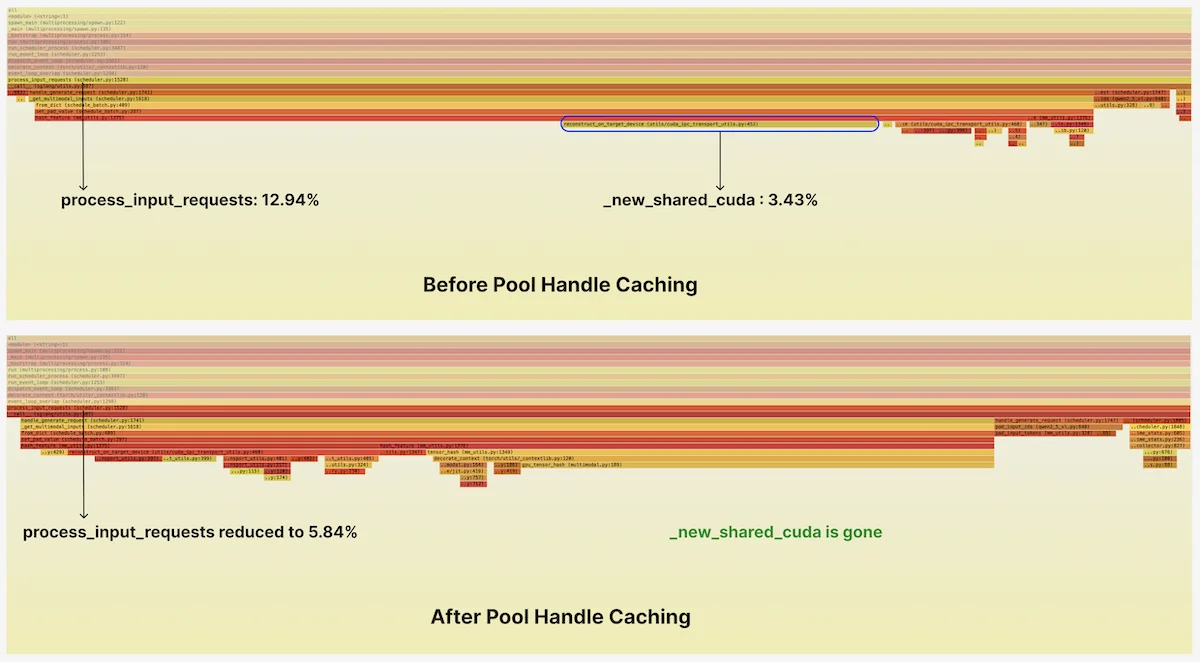
Documented Performance Improvements
In actual conditions, the enhanced SGLang configuration demonstrated impressive metrics, marking a notable advancement in processing capabilities:
| Metric | Handle Cache OFF | Handle Cache ON | Improvement |
|---|---|---|---|
| Throughput (req/s) | 22.2 | 25.7 | +16.2% |
| TTFT mean (ms) | 965 | 838 | -13.2% |
| TTFT p99 (ms) | 2058 | 1819 | -11.6% |
| TPOT mean (ms) | 72 | 60 | -17.2% |
| E2E latency mean (ms) | 1979 | 1768 | -10.6% |
| E2E latency p99 (ms) | 4309 | 3666 | -14.9% |
Real-World Impact and Conclusions
The overall optimizations mean that models benefiting from SGLang will enjoy a 10% drop in latency and a 16% boost in throughput during inference operations. This is significant for any applications relying on efficient multimodal processing. The changes enhance both user experience and operational efficiency, proving vital as multimodal AI applications continue to grow. As these optimizations have been merged upstream, they are now available for use in the latest SGLang versions.
If your work involves multimodal models, consider integrating these enhancements to capitalize on the improved performance. The modifications are activated simply by enabling a cache configuration flag, streamlining your efforts with the latest tools.
This pathway to optimization serves as an essential example of how focused profiling and thoughtful code adjustments can yield tangible performance gains, setting a precedent for future enhancements in multimodal AI systems.
Feel free to explore the latest benchmarks and practices for incorporating these optimizations, as they stand to benefit a wide array of applications.


