Developing a Reinforcement Learning Workflow for Automated Theorem Proving Using Modal
- Gate
- Machine Learning
- Departs
- Crew
- David Johnson
- Passengers
- 572
This article discusses the implementation of a reinforcement learning workflow for automated theorem proving using the Modal platform, focusing on efficiency and cost-effectiveness.
At AE Studio, we conduct extensive pretraining and fine-tuning on language models. Leveraging the Modal platform has allowed us to harness the power of thousands of GPUs in parallel, significantly reducing the time required for our workloads. In this article, we detail our research efforts utilizing reinforcement learning (RL) to train language models for proving mathematical theorems.
Motivation: Teaching AI to Prove Math Theorems
The conventional method for training models in RL is through techniques like Group Relative Policy Optimization (GRPO). In this method, the model generates multiple proof candidates, which are then ranked, adjusting weights to favor the more successful proofs. However, we aimed to explore a different method known as Evolution Strategies (ES).
ES offers an alternative to traditional backpropagation. Instead of leveraging gradient updates, it simulates natural selection by producing a population of varied model versions, evaluating their performance, and guiding the original model toward the successful variants. Recent studies suggest that ES may outperform GRPO in specific contexts, prompting us to evaluate its potential for theorem proving.
Setup
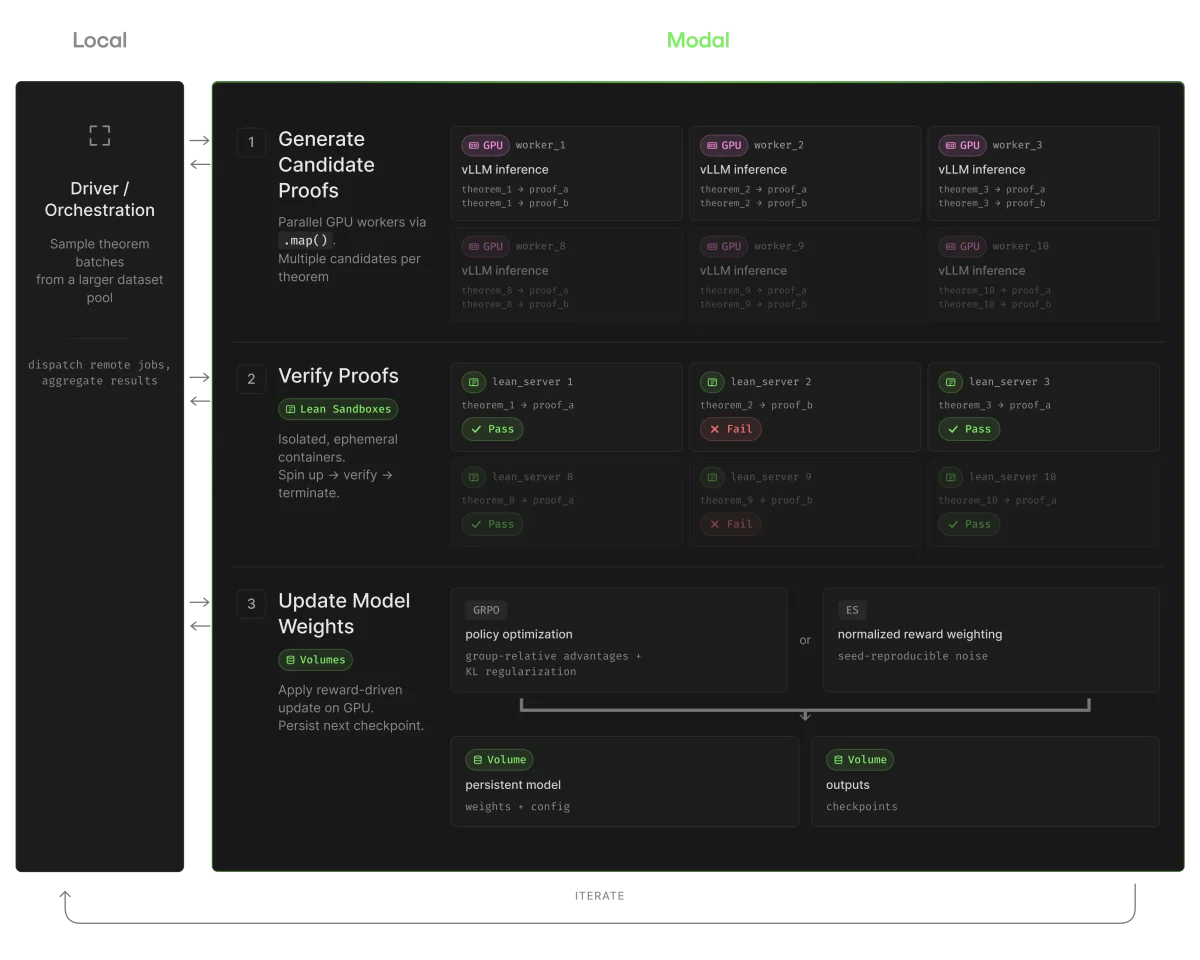
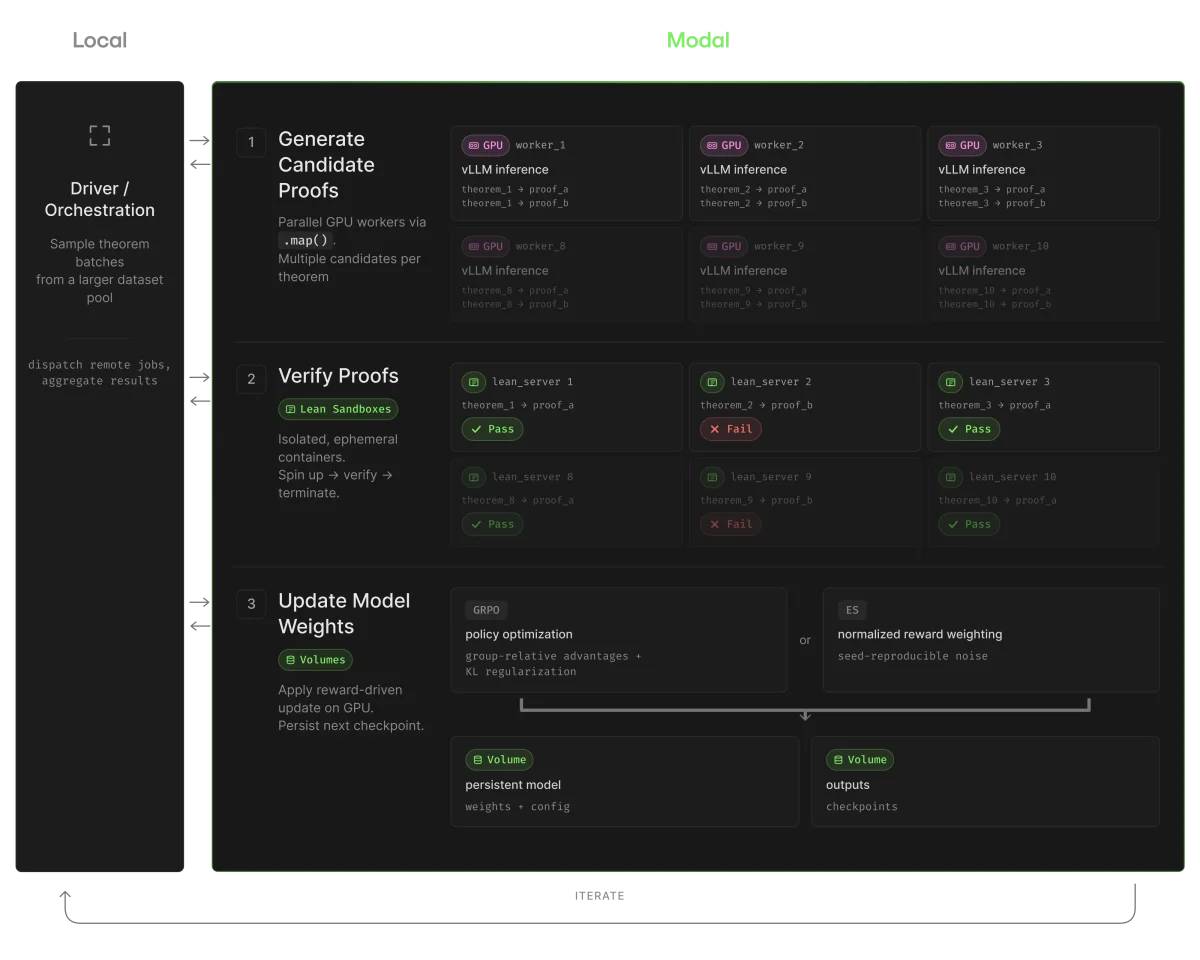
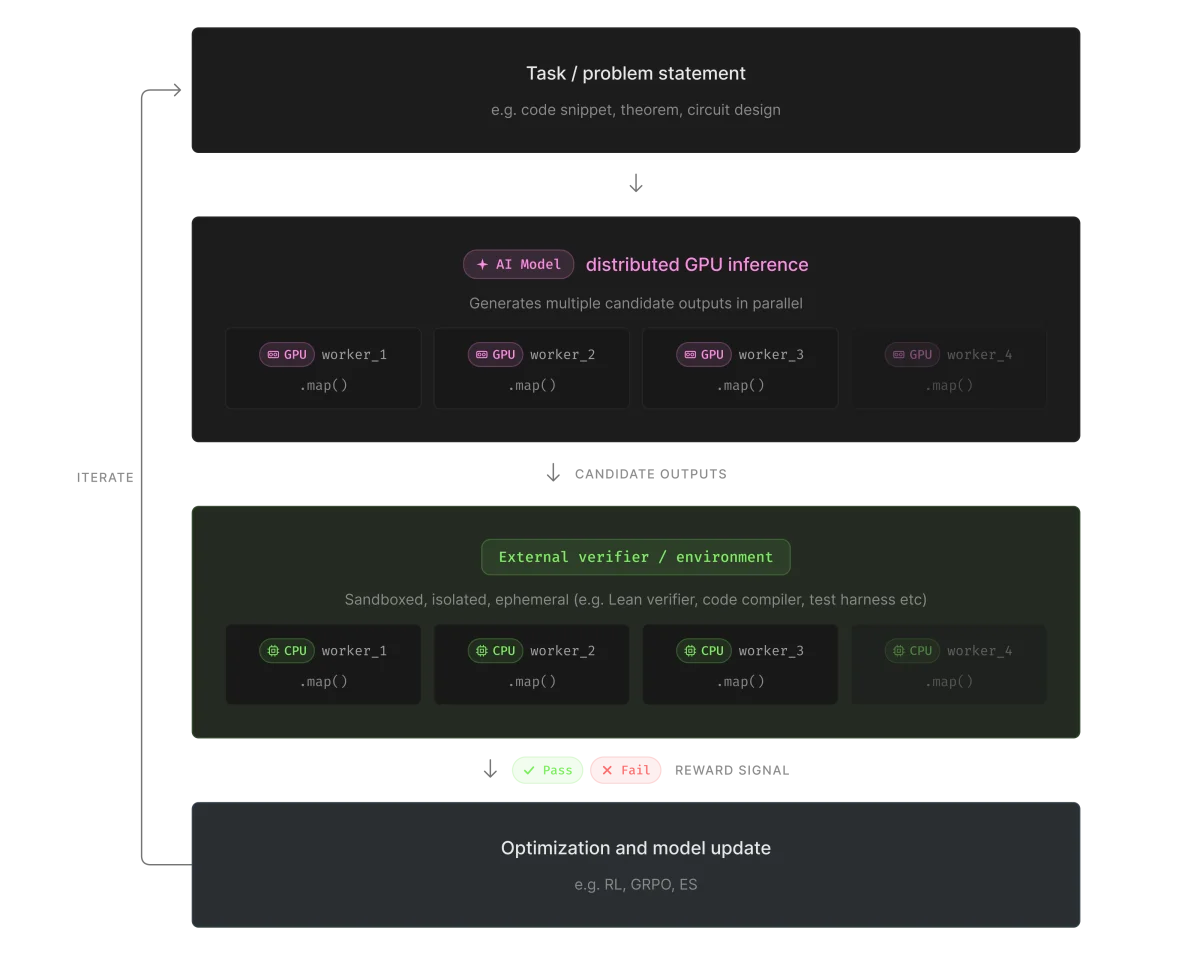
To enable a language model to generate formal proofs, we utilize the Lean theorem proving language, which compiles proof scripts for correctness verification. The complexity lies in integrating three different computational environments:
- Generating proofs: A GPU instance utilizing vLLM for inference generates proof attempts.
- Checking proofs: A Lean verifier running on a CPU analyzes each proof. Isolation is crucial since faulty proofs can disrupt the entire checking process.
- Coordinating everything: A lightweight process oversees the training loop, handling the distribution and tracking of theorem batches.
This infrastructure would typically require a significant investment of time and resources to set up multiple server environments and job scheduling systems. Instead, by deploying our workflow on Modal, we could focus on the research instead of infrastructure challenges.
The Modal implementation allowed us to streamline the process into:
| Workload Requirement | Modal Feature |
|---|---|
| Separate runtimes for GPU generation, Lean verification, and orchestration | Per-function images enable each step to establish its environment. |
| Numerous independent evaluations per ES iteration | .map() facilitates remote job distribution and returns results efficiently. |
| Lean verification needs isolation from errant proofs | Sandboxes allow each verification to have its short-lived environment. |
| Original base model must be accessible to all remote workers | Volumes ensure every GPU can load the base weights efficiently. |
| Gated access to the model via Hugging Face | Secure injection of credentials into remote functions keeps credentials safe. |
Utilizing Modal means we can avoid delays from cold startups seen in GPU sandboxes. Features like streamlined remote debugging enabled effective experimentation across multiple GPUs, making the process manageable.
The Training Process
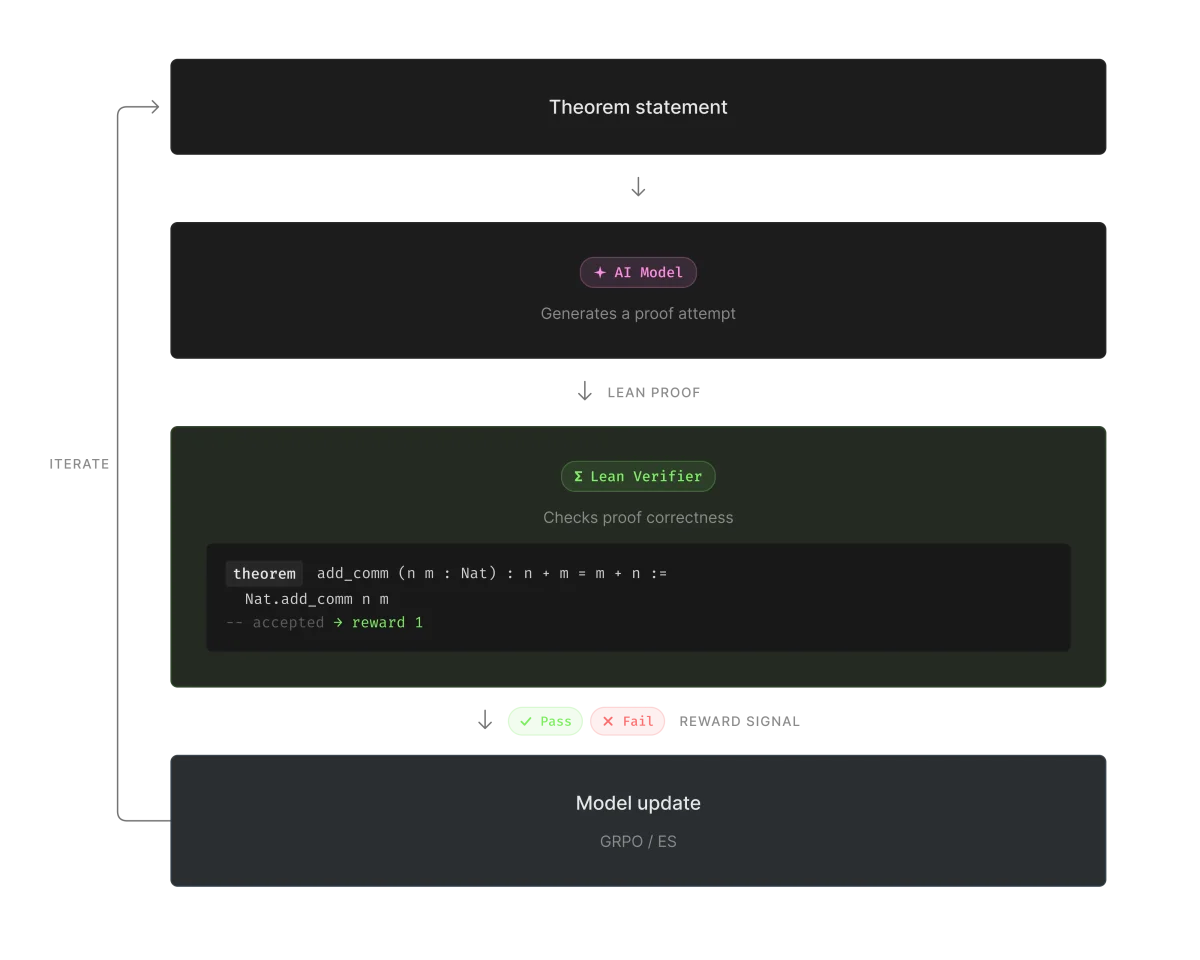
Our primary goal was to enhance the model's math theorem proving capabilities. By employing Lean, we acquire a verifiable reward signal for the training loop. Rather than focusing on plausibility, our focus shifts to whether the Lean verifier accepts the proof as valid.
An illustrative example involves proving that if a = b and b = c, then a = c. The model generates this proof in Lean, with rewards allocated based on correctness.
We kept our training loop constant while experimenting with different update rules, comparing GRPO and ES:
- GRPO: This method generates groups of proof attempts, offering gradient updates based on peer performance.
- ES: This strategy evaluates a diverse population of models, updating using a weighted combination from performance feedback.
How We Built It on Modal
Separate Images for Separate Jobs
By assigning distinct images for each compute role, we achieved a more manageable environment:
gpu_image = (
    modal.Image.debian_slim(python_version="3.11")
    .pip_install("vllm>=0.6.0", "torch", "transformers", "datasets", ...)
)

orchestrator_image = modal.Image.debian_slim(python_version="3.11").pip_install(
    "requests", "tqdm", "numpy"
)

lean_server_image = modal.Image.from_registry("projectnumina/kimina-lean-server:2.0.0")
This approach allows GPU workers to concentrate on inference, the Lean sandbox to focus on verification, and the orchestrator to remain lightweight. Reusing cached environments is also facilitated, optimizing efficiency.
Parallel GPU Fan-Out with .map()
Distributing ES computations was straightforward. Each evaluation required the current model checkpoint, theorem batch, perturbation seed, and generation parameters. We employed .map() for its structural alignment with the algorithm:
for candidates in generate_with_perturbation.map(
    [base_model_path] * population_size,
    [seed_reward_history] * population_size,
    [iteration_theorems] * population_size,
    perturbation_seeds,
    [sigma] * population_size,
    [temperature] * population_size,
    [max_tokens] * population_size,
):
    candidate_proofs.extend(candidates)
Notably, the updates in ES are determined by pre-set seeds, requiring no significant weight transfers between GPUs.
Sandboxed Lean Verification
To ensure isolated verification, we constructed a sandbox for each batch of proofs. By initializing the Lean server in a sandbox and terminating it after a verification, we mitigated risks associated with poor proof submissions:
sb = modal.Sandbox.create(
    image=lean_server_image,
    cpu=4,
    memory=16384,
    timeout=3600,
    encrypted_ports=[8000],
)

proc = sb.exec(
    "bash", "-c",
    "cd /root/kimina-lean-server && nohup python -m server > /tmp/server.log 2>&1 &",
)

tunnel = sb.tunnels()[8000]
server_url = tunnel.url
This method allows for parallel verification while maintaining an organized fan-out structure across tasks. For each run iteration, we produced 3,840 proof attempts, which we managed in batches of 64. Modal’s scalable model enables further expansion of this framework, as proof attempts can be uniformly distributed across more sandboxes for expedited verification.
Stateless Checkpointing with Seed Histories
A defining feature of ES is its ability to represent the model state through base weights plus a list of (seed, reward) pairs. The orchestrator maintained an ongoing list of seed/reward pairs to enhance efficiency:
seed_reward_history: List[Dict] = []
for iteration in range(num_iterations):
    result = run_es_iteration.remote(
        base_model_path=model_name,
        seed_reward_history=seed_reward_history,
    )
    seed_reward_history.append(result["history_entry"])
Detailed entries encompassed the seeds, rewards derived, and hyperparameters necessary for recomputing updates. Each entry was approximately 200 bytes, facilitating efficient data transfer between iterations.
Key Performance Metrics
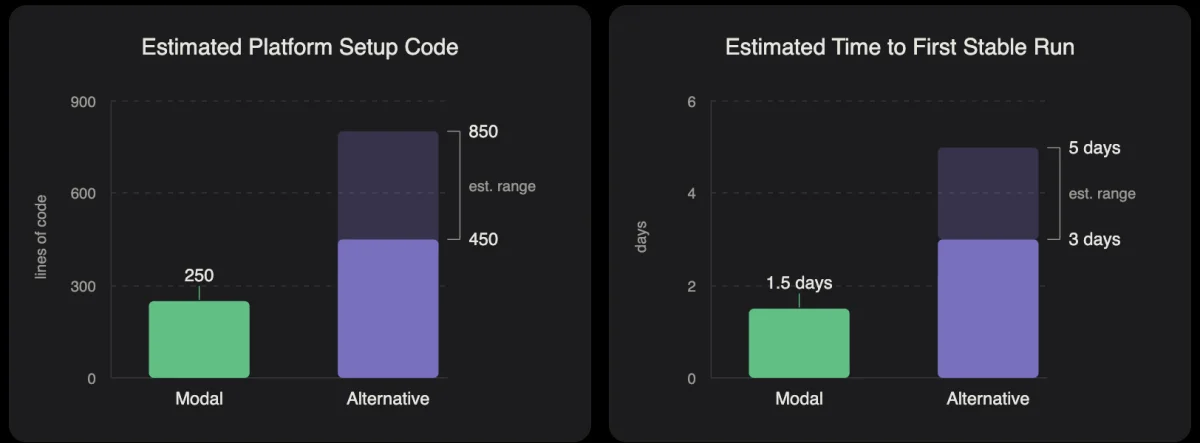
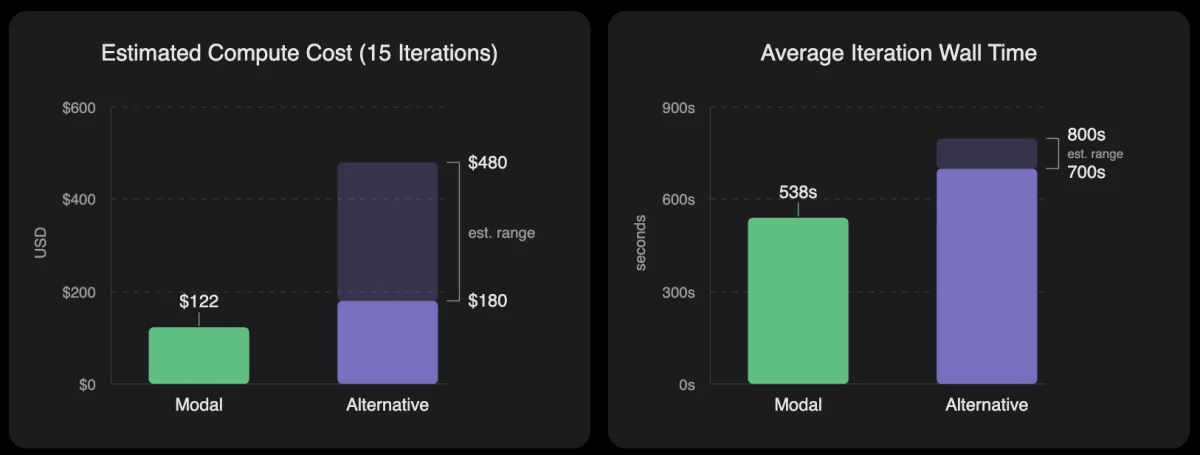
The Modal implementation proved to be an optimal balance of speed, simplicity, and affordability. Our setup required roughly 250 lines of implementation code— significantly fewer than the 600+ lines typically utilized in other environments. Consequently, we completed a training run in less than two days, a 60% improvement over similar platforms.
Runtime efficiency showed remarkable improvement. The generation phase, using GPUs, averaged 147 seconds per iteration, while the overall process required 538 seconds, primarily due to CPU-only verification. Modal’s flexibility led to approximately 3.7x reduction in GPU idle time compared to less dynamic environments.
Cost estimates for the full run on Modal were around $122; in contrast, alternatives would have incurred expenses ranging from $180 to $480. This streamlined setup stands out as the fastest and most economical means to achieve outcomes.
Results & What’s Next
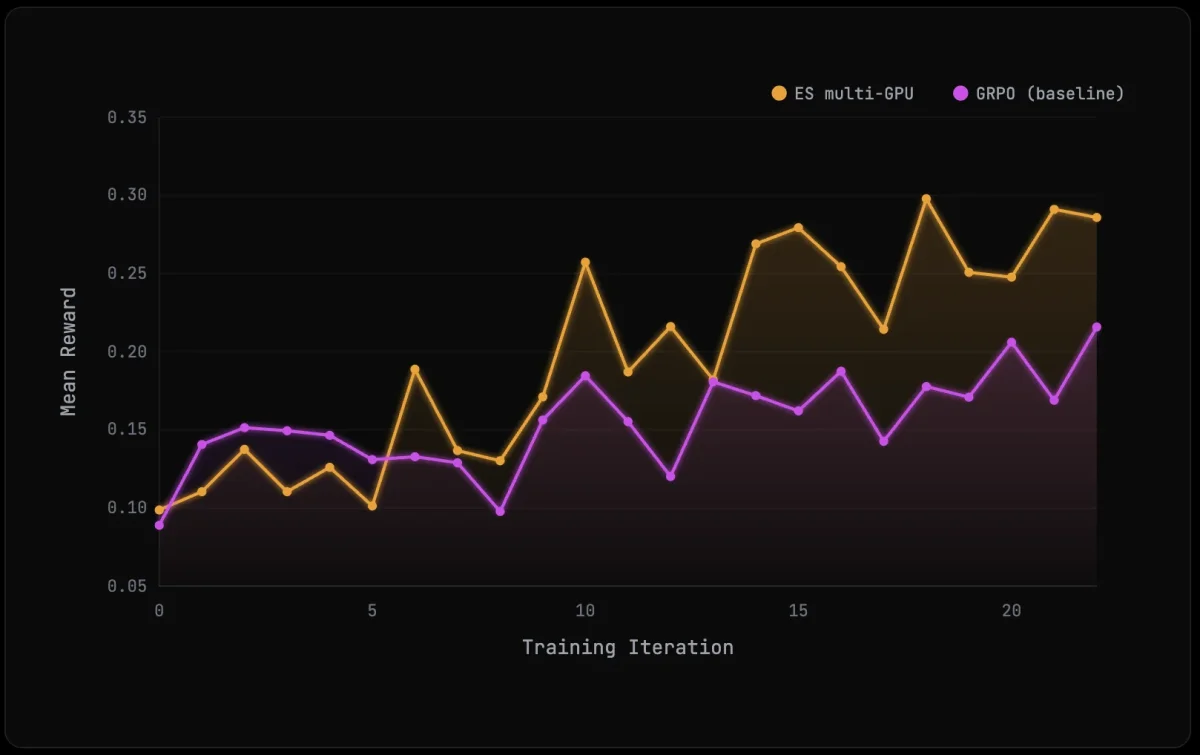
Initial results indicated that ES rivaled or outperformed the GRPO baseline in terms of verified proofs per iteration and demonstrated efficiency with limited training data. Nonetheless, variability in outcomes raises concerns about hyperparameter impacts and required further experimentation to identify conditions favoring ES.
Our infrastructure setup with Modal remains invaluable for continuous verification-enabled training loops. Future experiments will hone in on:
- Variance analysis: Systematic evaluations of factors like sigma, population size, and theorem selection to determine optimal ES conditions.
- Larger models: Testing the performance of the 7B distilled Kimina model could reveal differing dynamics.
Open questions mainly relate to experimental design and less to system reliability. This insight underlines the role of our workflow agility and adaptability without necessitating bespoke infrastructure.
What You Can Learn from This
The infrastructure architecture presented here extends beyond theorem proving, resembling frameworks seen in various ML systems. The process involves generating outputs on GPUs, running verification processes against those outputs, and converting outcomes into training signals in a cyclical manner.
A key element was the parallelization of GPU inference, isolation of verification tasks, and ensuring portable training states, all integrated within a single cohesive workflow. Using Modal, we successfully executed a sparse-reward RL strategy across diverse computational environments, enabling rapid experimentation and result generation, alleviating the stress of system reliability.
For full code and implementation guidance, refer to our project repository at github.com/agencyenterprise/modal-rl-theorem-case-study.
References
- Qiu, X., et al. (2025). Evolution Strategies at Scale: LLM Fine-Tuning Beyond Reinforcement Learning. arXiv:2509.24372. https://arxiv.org/abs/2509.24372
- Numina & Kimi Team. (2025). Kimina-Prover Preview: Towards Large Formal Reasoning Models with Reinforcement Learning. arXiv:2504.11354. https://arxiv.org/abs/2504.11354
- Raschka, S. Build a Reasoning Model from Scratch. Manning. https://www.manning.com/books/build-a-reasoning-model-from-scratch
- The base model was Kimina-Prover-Preview-Distill-1.5B, distilled from the 72B Kimina-Prover project.kfdong/STP_Lean_SFT


