Skip to departures
Machine Learning
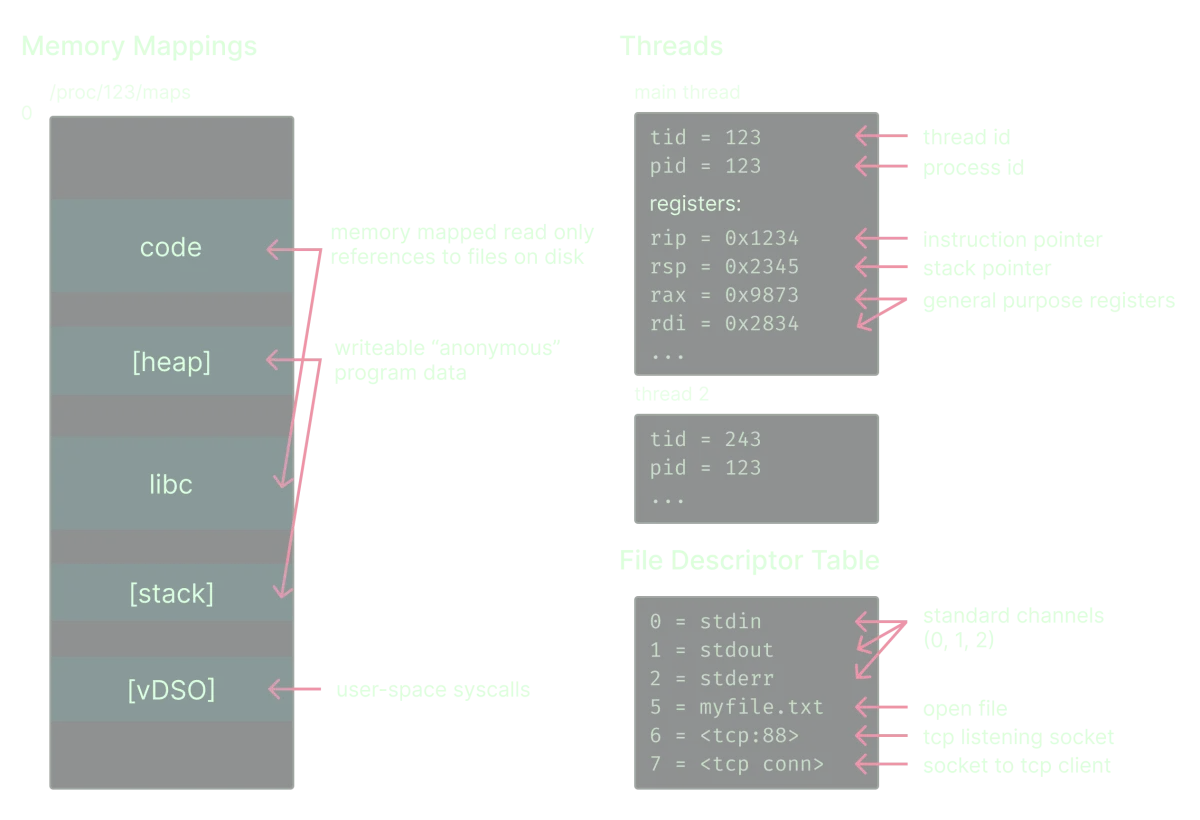 Memory Snapshots Enhance Serverless GPU Container Performance by Reducing Cold Start Times
Modal's introduction of memory snapshots significantly decreases cold start latency in GPU container runtimes, offering boosts in performance over tra...
GateMachine Learning
Departs
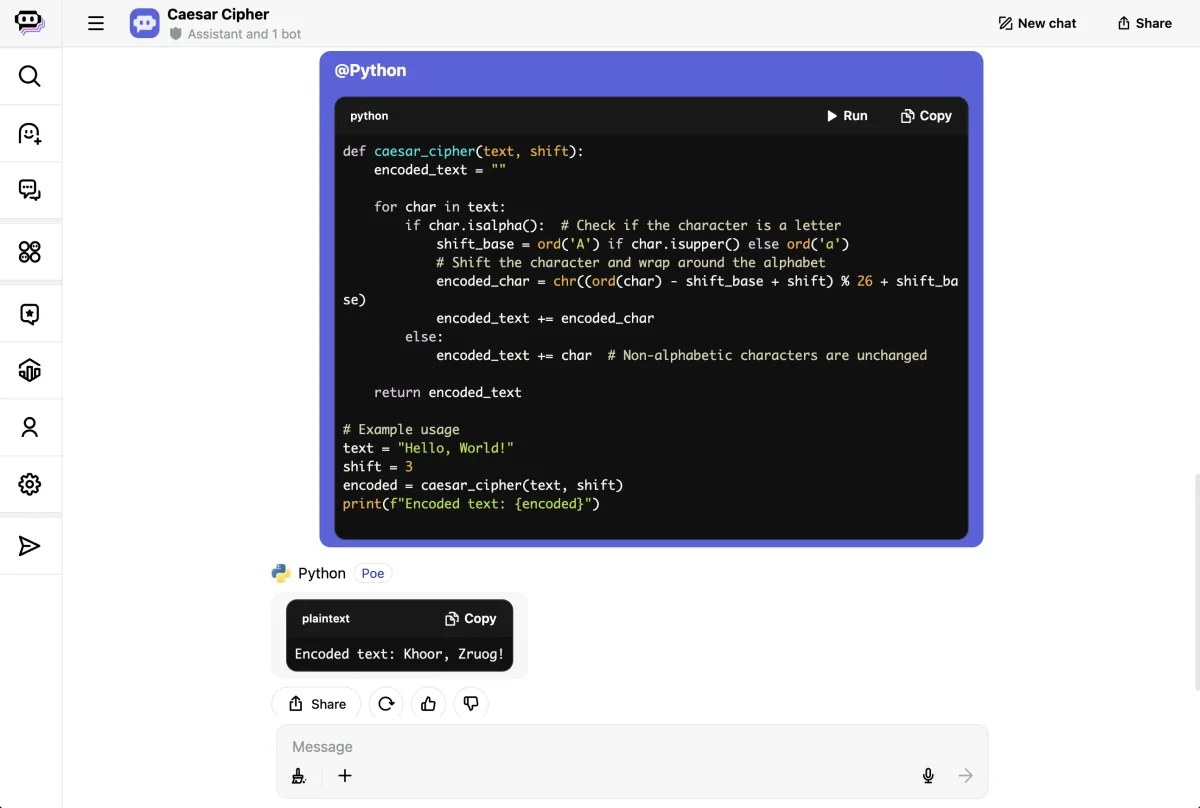 Modal Sandboxes Launch: Secure Environment for Untrusted Code Execution
Modal Sandboxes are now generally available, offering a secure environment for executing untrusted code with dynamic configurations and robust functio...
GateMachine Learning
Departs
 NVIDIA L40S GPUs Launch with Enhanced Performance and New Features on Modal
The NVIDIA L40S GPUs are now available on Modal, offering enhanced memory, speed, and several new features for developers and researchers.
GateMachine Learning
Departs
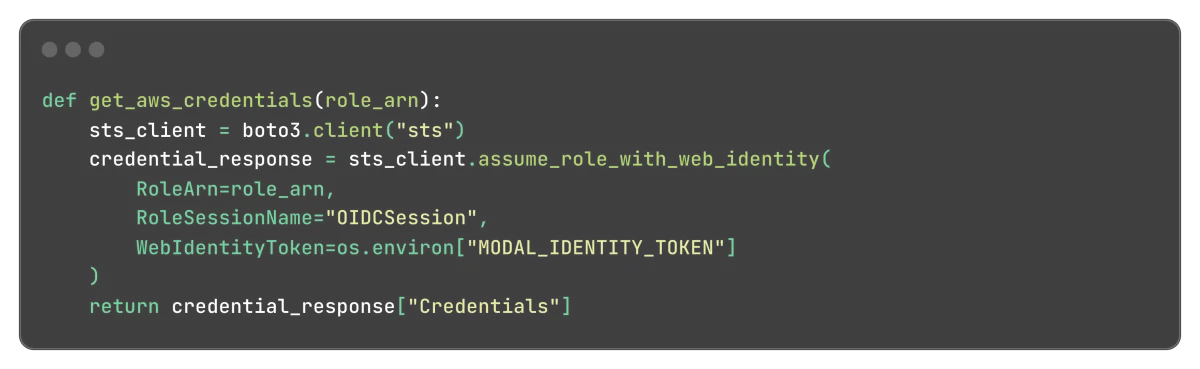 Modal Releases Key Updates: Enhanced Memory Snapshotting, Async Job Queues, and OIDC Integration
Modal's latest updates feature faster memory snapshotting, expanded async job queues, and OpenID Connect for improved authentication and integration.
GateMachine Learning
Departs
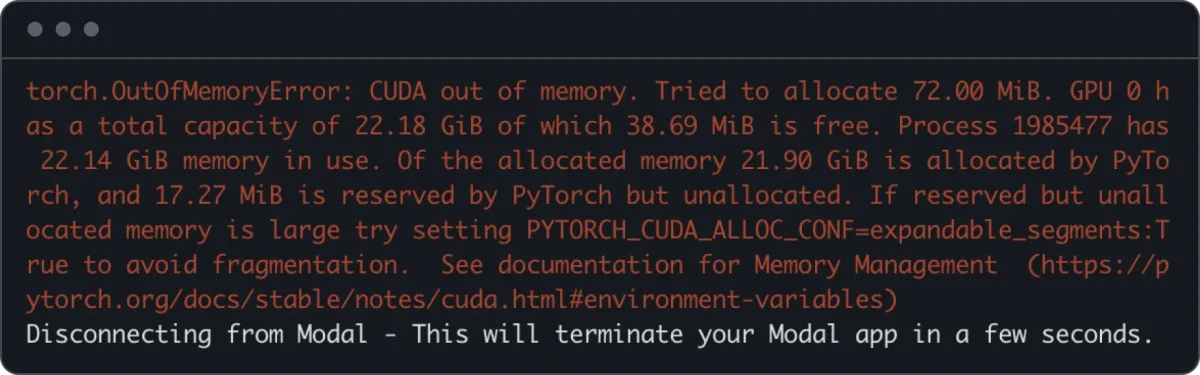 NVIDIA L40S GPUs Now Available on Modal: Enhancements for Inference Workloads
Modal users can now access NVIDIA L40S GPUs, offering enhanced memory and speed advantages over the A10 GPU for demanding inference tasks.
GateMachine Learning
Departs
 Understanding LLM Fine-Tuning: Benefits, Techniques, and Frameworks for 2025
Explore how fine-tuning large language models enhances task performance, reduces costs, and discover leading frameworks for implementation.
GateMachine Learning
Departs
 Insights from Modal's Hackathon: Projects Unveiling New Use Cases and Enhancements
Modal's internal hackathon showcased innovative projects, including AI tools and latency reduction strategies, enhancing productivity and real-time ap...
GateMachine Learning
Departs
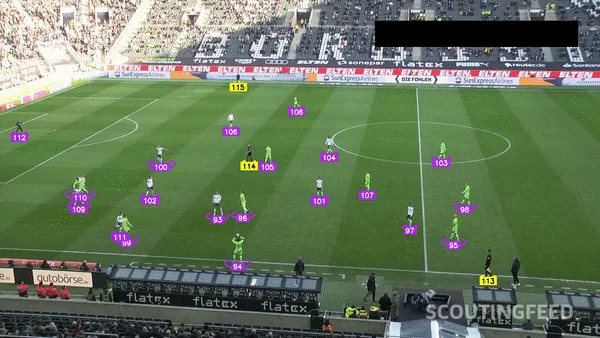 Data Processing Transformation: A European Soccer Team Cuts Costs and Speeds Up Analysis
A leading European soccer team enhanced its data processing efficiency and reduced costs by 50% through improved infrastructure and innovative batch p...
GateMachine Learning
Departs
 Building High-Availability VPN Proxies for Serverless Containers with WireGuard at Modal
Modal's implementation of a Go-based VPN proxy, vprox, enables static IP addresses for serverless containers, ensuring reliable connections and simpli...
GateMachine Learning
Departs
 OpenArt Streamlines AI Art Platform Scalability with Modal's Infrastructure
OpenArt has efficiently scaled its AI image generation platform using Modal, overcoming limitations of traditional API providers and cloud infrastruct...
GateMachine Learning
Departs
 Modal's New Features: Static IP Proxies, Enhanced Slack Integration, and Live Resource Monitoring
Modal introduces new features including static IP proxies, Slack integration for alerts, and a real-time usage dashboard for effective resource manage...
GateMachine Learning
Departs
 Tidbyt Joins Modal to Enhance Cloud Infrastructure for AI and Machine Learning
Tidbyt, known for its programmable LED screens, joins Modal to leverage mutual strengths in cloud infrastructure and customer acquisition.
GateMachine Learning
Departs
 Understanding the Need for Flexible GPU Capacity in AI Development
AI's demand for GPU compute is surging, but supply challenges exist. Exploring the shift to on-demand GPU models highlights implications for startups...
GateMachine Learning
Departs
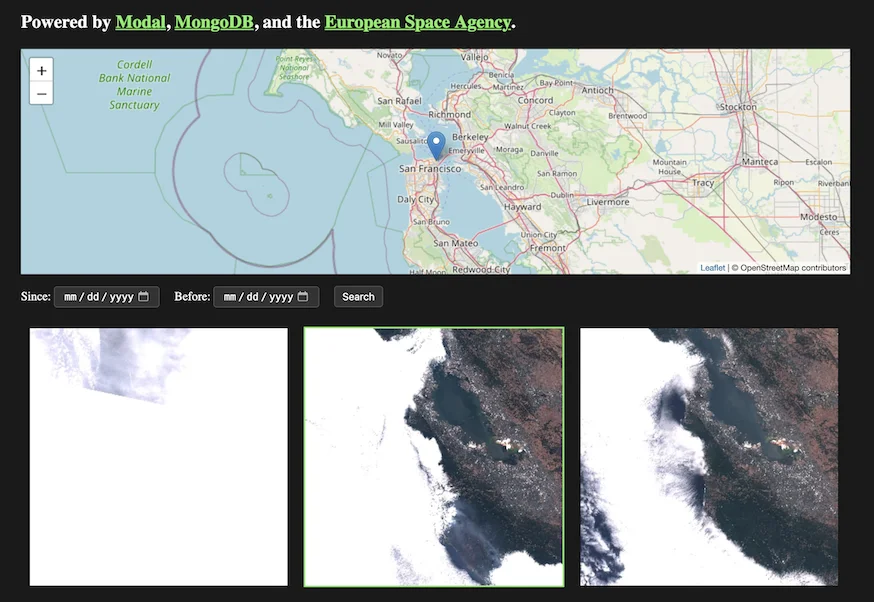 Leveraging Hybrid Search with MongoDB, Modal, and Clay for Enhanced California Data Insights
Explore a hybrid search application utilizing MongoDB, Modal, and Clay for satellite image analysis of California, showcasing data integration and rea...
GateMachine Learning
Departs
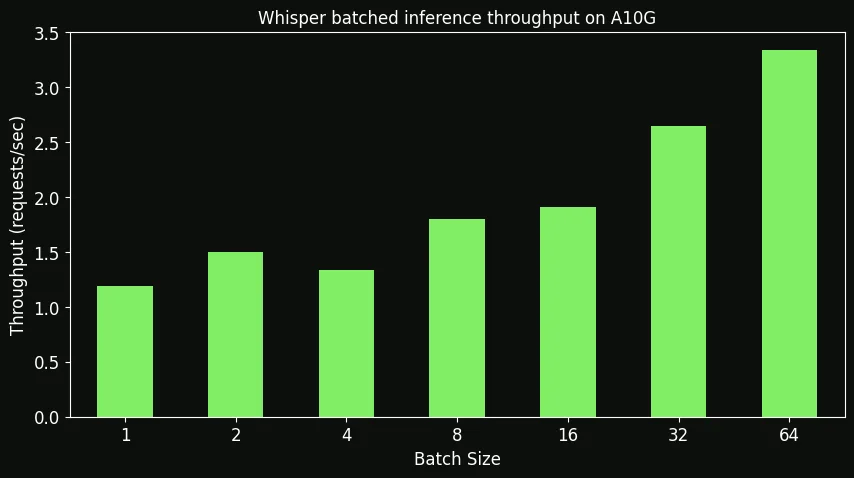 Enhancing Throughput with Dynamic Batching for Machine Learning Workloads
Dynamic batching can significantly improve the efficiency of machine learning workloads, offering up to 2.8x increased throughput with minimal code ch...
GateMachine Learning
Departs
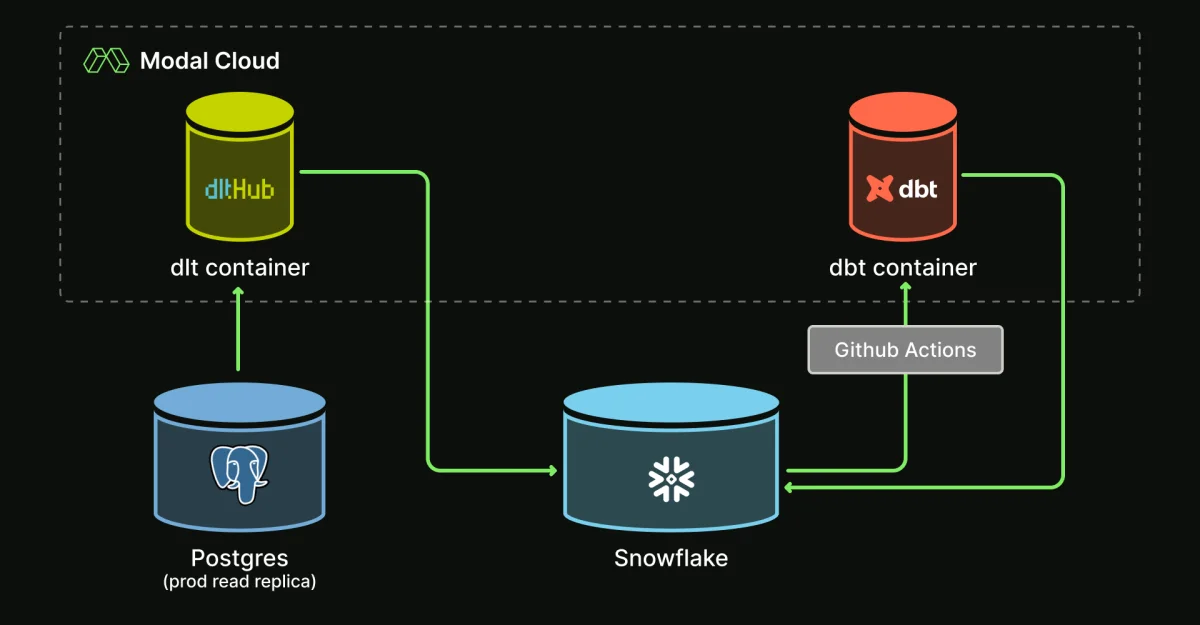 Cost-Effective Analytics Stack: Leveraging Modal, dlt, and dbt for Data Engineering Efficiency
This article outlines how to create a cost-efficient analytics stack using Modal, dlt, and dbt, highlighting data loading, transformation, and deploym...
GateMachine Learning
Departs
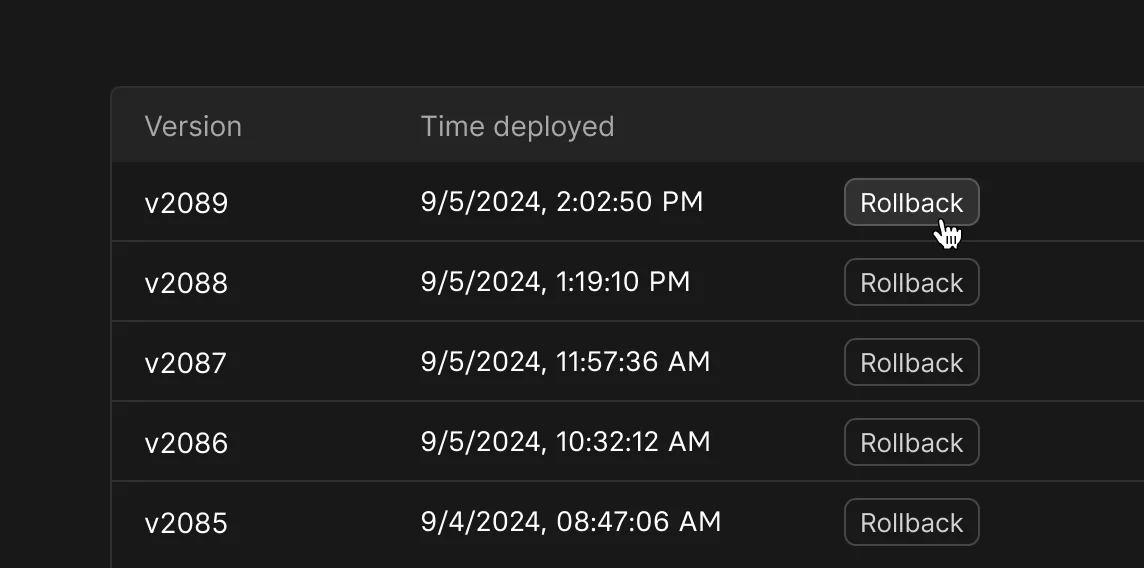 Modal Enhancements: App Rollbacks, Dynamic Batching, and New Pricing
Modal's latest updates include app rollbacks, dynamic request batching for efficiency, TCP tunneling in Sandboxes, and reduced pricing for CPU and GPU...
GateMachine Learning
Departs
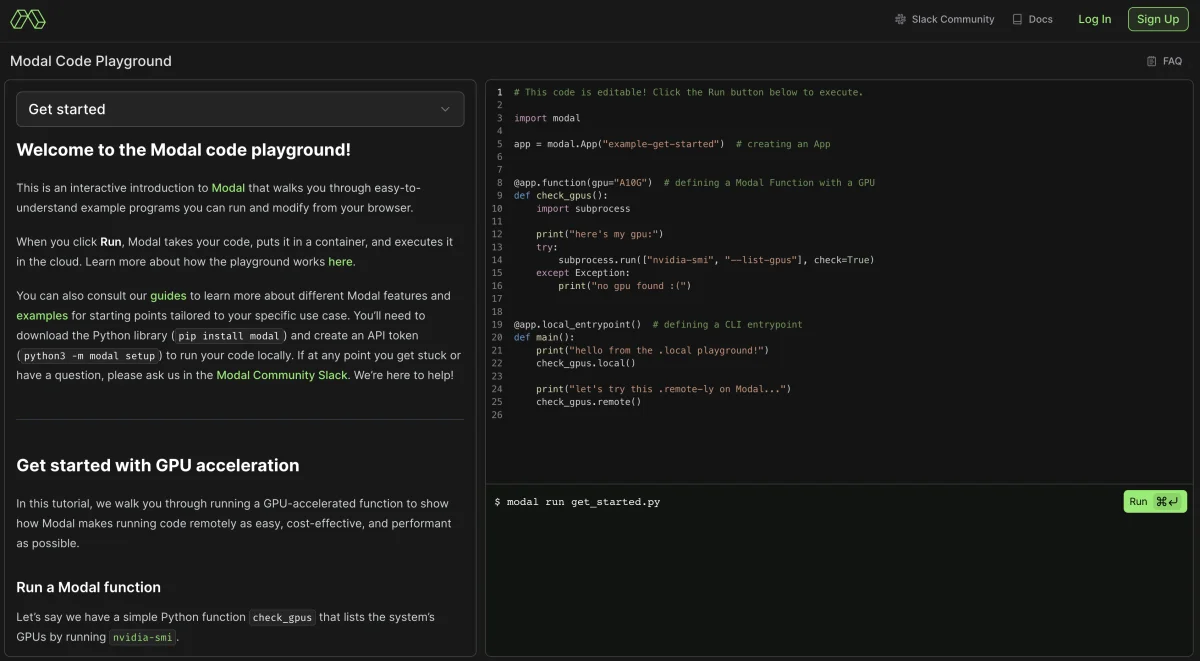 Exploring Modal's Interactive Code Playground: Architecture and Limitations
Modal's new interactive code playground allows users to execute code easily in the cloud, featuring robust tutorials but constrained by its environmen...
GateMachine Learning
Departs
 Modal Announces Reduction in GPU Prices and Changes to Billing Structures
Modal has cut GPU prices by 15-30% while updating its CPU/memory billing practices, aiming to enhance affordability for AI developers.
GateMachine Learning
Departs
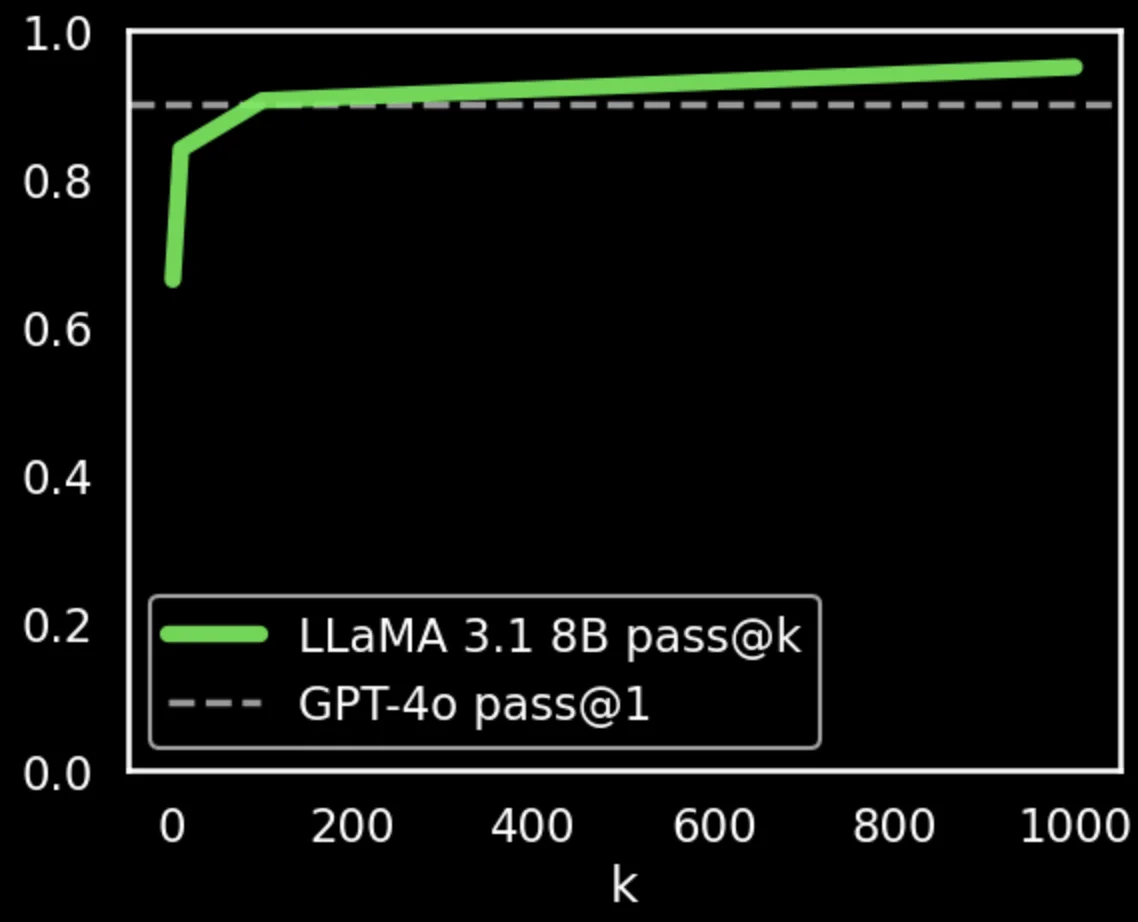 Leveraging Search with LLaMA: Surpassing GPT-4o in Python Tasks
This exploration shows how scaling search techniques with the LLaMA model can match or surpass the performance of GPT-4o in coding tasks, highlighting...
GateMachine Learning
Departs